
@agentgrit/core
v0.2.0
Published
Self-learning engine that makes AI agents smarter over time
Downloads
176

Maintainers
 hornjason
Readme
doc-type: reference status: active owner: jason updated: 2026-08-07
AgentGrit
Self-learning engine that makes AI agents smarter over time.

AgentGrit closes a feedback loop around AI agents: it captures signals from your sessions (ratings, corrections, sentiment), detects recurring failure patterns, promotes learnings into durable rules, and builds a knowledge graph for contextual recall. Every session makes the next one smarter.
Key metrics: 1436 tests, 404 graph nodes, 16 domains, 98% domain coverage, hybrid BM25+vector+graph retrieval with config-driven RRF weights, 13 Claude Code hooks, 44/44 Docker E2E tests.
Design principles:
- Nothing hardcoded, everything lifecycled — all thresholds, weights, and domain classification are config-driven or graph-derived
- The graph is the source of truth — rules, domains, and correlations live in the graph
- Measure before and after every change
It targets Claude Code initially but is designed to be runtime-agnostic. The scoring, pattern detection, and optimization layers work with any LLM trace source.
How It Works
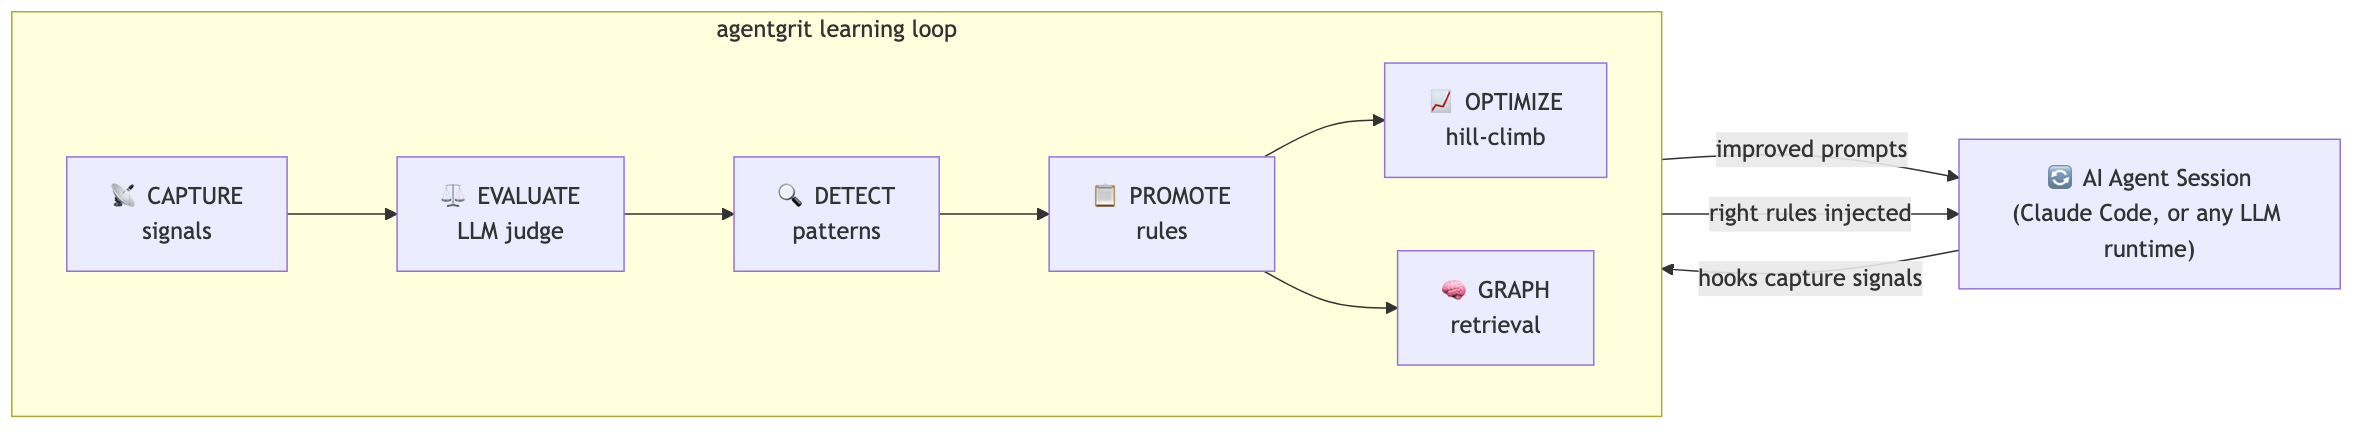
Signals flow in from every session. The daemon scores, detects patterns, and promotes rules. The graph injects the right rules into the next session. The loop tightens over time.
Quick Start
bun add -g @agentgrit/core
agentgrit init
agentgrit status
init walks you through setup interactively. It creates ~/.agentgrit/, copies the starter rubric, and writes your config. Signals begin capturing on your next Claude Code session.
Adoption Speeds
All code ships in one package. You choose what to enable at init.
| Speed | What's On | API Keys | Promotion |
|-------|-----------|----------|-----------|
| Quick | Signal capture to JSONL, pattern detection on session end, agentgrit inbox for review | None | Manual via inbox |
| Standard | Everything in Quick + LLM judge scores traces against rubrics + keyword-based graph + context injection at session start | One (Gemini, Claude, or OpenAI) | Manual via inbox |
| Full Auto | Everything in Standard + daemon every 30 min + hill-climbing optimizer + hybrid retrieval (BM25 + graph + RRF) + optional Langfuse sync | One + optional Langfuse | Auto or manual (configurable) |
Switch speeds anytime with agentgrit upgrade.
The Learning Loop
1. Capture — Signal Collection
Hooks fire automatically during Claude Code sessions. No manual work required.
| Signal | How It's Captured | Storage |
|--------|-------------------|---------|
| Rating | Explicit /rate command or simple thumbs up/down | ratings.jsonl |
| Correction | Regex detects correction language ("stop doing", "that's wrong", "I didn't ask") with noise filtering ("no worries", "not yet") | corrections.jsonl |
| Sentiment | LLM-based (Haiku) per-message sentiment + keyword fallback + session-end auto-scoring | Embedded in rating signals |
| Skill invocation | Logs which skills fired, duration, success/failure | skills.jsonl |
| Tool audit | Records every tool call with timing | tool-audit.jsonl |
| Debrief | End-of-session rule extraction | Via debrief hook |
Explicit ratings are optional. Corrections and sentiment are captured implicitly from natural conversation — the user doesn't need to do anything special.
Each signal includes a UUID, timestamp, session ID, and schema version. Correction signals also carry severity (1-10, assigned by pattern match) and context (truncated user message + assistant response).
2. Evaluate — Quality Scoring
Two independent scoring channels:
Channel 1: Human signals (always on, zero cost) Rating composites, corrections, and sentiment flow in automatically from hooks.
Channel 2: LLM judge (opt-in, requires API key) The judge reads an LLM trace (input + output pair) and scores it against each dimension in your rubric. It builds a structured prompt with the trace content and rubric criteria, sends it to the configured provider (Gemini, Claude, or OpenAI), and parses the JSON response into per-dimension scores with reasoning.
The judge supports retry with exponential backoff on rate limits (429), and gracefully returns empty results on API errors rather than crashing.
Rubrics define what "good" means for your domain. Each rubric is a JSON file with weighted dimensions:
{
  "version": "1.0",
  "schemaVersion": 1,
  "dimensions": [
    {
      "name": "task-completion",
      "description": "Did the output accomplish what was asked?",
      "weight": 0.30,
      "rubric": "Score 1-5. 1=completely wrong. 3=partially done. 5=fully accomplished."
    }
  ],
  "judgeModel": "gemini-2.5-flash"
}
The starter rubric covers four universal dimensions: task-completion (30%), accuracy (30%), conciseness (20%), and safety (20%). Write custom rubrics for your domain — multiple rubrics compose via composeRubrics(), which merges dimensions and renormalizes weights.
The rubric loader validates structure: dimension names must be unique, weights must sum to ~1.0, and schemaVersion must be present.
3. Detect — Pattern Recognition
Two detection strategies run in parallel:
Failure pattern detection (failures.ts): Reads correction signals, groups them by keyword similarity (Jaccard coefficient, threshold 0.3), and surfaces groups that cross a configurable frequency threshold (default: 5 occurrences). Each group produces a candidate rule with the most common trigger text.
Cross-signal pattern mining (patterns.ts): Builds per-session snapshots combining ratings, corrections, and skill invocations. Finds three pattern types:
- Low-rated sessions with corrections — sessions averaging <= 4.0 that also have correction signals
- Skill miss patterns — skills that failed across 2+ sessions
- Score drops — when recent session averages drop >= 1.5 points below early session averages
Trajectories (trajectories.ts): The flip side of failure detection. Stores "what worked" episodes from high-rated sessions. Domain-tagged for contextual retrieval. Capped at 100 entries — when full, the lowest-rated trajectory is evicted. Queried by domain overlap (Jaccard) for retrieval.
4. Promote — Rule Management
Detected patterns become candidate rules. The router determines where each rule goes.
Three-tier routing (router.ts):
- Single project →
PROJECTtier (that project's CLAUDE.md) - Multi-project + behavioral keywords (verify, check, always, never) →
GLOBALtier (~/.claude/CLAUDE.md) - Multi-project + procedural keywords (run, spawn, invoke, deploy) →
GRAPHtier (knowledge-graph.json, injected at session start)
Classification uses keyword counting: behavioral keywords vs. procedural keywords. Whichever set has more matches determines the tier.
Budget enforcement (budget.ts): Global and project tiers default to 25 rules max each. Graph tier is unlimited. When a tier reaches 20 rules, status changes to WARNING. Above 25, it's OVER_BUDGET and new promotions are blocked.
Rule tracking (rules.ts): Each rule tracks injection count, correlated session ratings (sliding window of 20), and high/low rating activations. Rules that are frequently injected but don't correlate with improved ratings become eviction candidates.
Atomic CLAUDE.md writes (bridge.ts): Rules are written to CLAUDE.md using a write-to-temp-then-rename pattern. The bridge finds the rules section by marker (### Rules or ## Rules), locates the last rule line, and inserts the new rule after it. If the write fails, the temp file is cleaned up. Removal works by filtering out lines matching the rule ID pattern.
Promotion ledger (ledger.ts): Every promotion is recorded in promotions.jsonl with before/after snapshots. agentgrit undo reverses recent promotions by replaying the ledger.
Weekly learning review (review.ts): Clusters rating signals by sentiment summary similarity, identifies clusters of 3+ low-rated entries (avg <= 4.0), and proposes candidate rules. Also computes score trend direction (up/down/flat) by comparing first-half and second-half averages.
5. Optimize — Hill-Climbing Improvement
The hill-climbing engine (hill-climb.ts) is generic: propose a change, evaluate it, keep it if the score improves, discard it if not.
How it works:
- Evaluate the current text to get a baseline score
- For each round: propose a variation, check if the change is within the size limit (default 15%), evaluate the proposal, keep it only if the score strictly improves
- Log every round to
experiments.jsonlwith score, delta, outcome, and latency - Flag large improvements (>15% delta) for human review
Prompt tuner (prompt-tuner.ts): Applies hill-climbing to system prompts. Fetches the N lowest-scoring traces for a target dimension, identifies the most common system prompt among them, generates the initial output for each test case, proposes improved prompts, re-generates all test cases with the new prompt, and keeps the change only if the weighted average across all rubric dimensions improves.
Skill tuner (skill-tuner.ts): Same engine applied to skill description optimization.
The 15% maximum change ratio prevents the optimizer from making drastic rewrites in a single round. Proposals that exceed this limit are logged as rejected_size and skipped.
6. Graph — Knowledge Retrieval
The knowledge graph stores rules as nodes connected by domain relationships. At session start, the graph injects the most relevant rules based on the current task's domain.
Building the graph (builder.ts + domain-propagation.ts):
- Discovers rule files (markdown with YAML frontmatter)
- Classifies each rule into domains using a three-tier system:
- Primary: BM25 neighbor propagation — infers domains from classified neighbors via weighted graph edges (co_occurred=1.0, reinforces=1.5, sibling=0.8)
- Secondary: BM25 text similarity — top-3 most-similar classified nodes vote on domain
- Fallback: Keyword regex patterns (13 domains: verification, escalation, scope, delivery, communication, deployment, security, ui-testing, data, browser, memory, algorithm, delegation)
- Achieves 91% domain coverage (up from 53% with keyword-only)
- Builds
same_domainedges between rules sharing a primary domain (max 4 edges per node) - Incremental: only re-classifies rules whose content hash changed since the last build
- Tracks
domainSourceper node: "propagation", "bm25", "keyword", "ai", or "override"
Querying (query.ts): Scores each node by domain overlap (50%), blended edge strength (30%), and activation history (20%). Builds clusters by following reinforces, sibling, caused_by_same_root, and same_domain edges. Expands candidates via high-strength embedding edges (>= 0.6). Returns ranked clusters with connected nodes.
BM25 full-text search (bm25.ts): Builds an inverted index over rule files. Strips frontmatter and markdown formatting, tokenizes, computes IDF using the smooth variant, and scores documents using BM25 (k1=1.5, b=0.75).
Hybrid retrieval (retrieval.ts): 3-way merge of BM25 keyword results, vector similarity, and graph domain expansion using Reciprocal Rank Fusion (RRF, k=60). Configurable weights via config.json (defaults: bm25=2x, vector=1x, graph=0.5x). Includes node-type weighting: feedback/steering 1.0x, success 0.8x, reference 0.5x, project 0.3x. RRF weights are auto-tunable via the hill-climbing weight optimizer.
Session-start context injection (context.ts): Detects domains from the current task text. Queries the graph and BM25 index, merges results via 3-way RRF, and returns up to 10 rules for injection. Also BM25-filters CLAUDE-LEARNED.md rules (top 10 of 50+) for task-specific learned rule injection.
Weight optimization (weight-optimizer.ts): Hill-climb optimizer tunes RRF weights against the gold set. Perturbs one weight at a time by ±0.25, evaluates precision@5, keeps improvements. Baseline floor enforced at 0.76 — optimizer never degrades below current quality. Optimal weights written to config.json.
7. Daemon — Automation
30-minute cycle (daemon.ts):
- Score — evaluate recent traces against rubrics using the LLM judge
- Detect — scan for failure patterns and cross-signal patterns
- Promote — route detected patterns to rules (if auto-promote is enabled and budget allows)
- Sync — push scores to Langfuse (if configured)
- Optimize — flag dimensions with scores <= 2 for hill-climbing
Weekly cycle (runs on the configured day, default Sunday):
- Full learning review with pattern synthesis
- Knowledge graph rebuild
- Budget status check across all tiers
Health checks (doctor.ts): Inspects five sections:
- CAPTURE — checks each signal file exists and was modified within 14 days
- SCORING — verifies judge API key is configured and scores file is recent
- GRAPH — checks knowledge-graph.json exists and was rebuilt within 7 days
- RULES — counts rules against budget caps
- SIGNALS — checks JSONL file sizes (warning at 5MB, error at 20MB)
Scheduler (scheduler.ts): Generates and installs platform-specific daemon configuration:
- macOS: LaunchAgent plist at
~/Library/LaunchAgents/com.agentgrit.daemon.plist - Linux: systemd user service + timer at
~/.config/systemd/user/
Supports install, uninstall, and status checks. Parses interval strings (30m, 1h, 300s).
Session cleanup (cleanup.ts): Removes stale session state files (>30 days old) and temporary/backup files (>7 days old). Rotates oversized signal files (default threshold: 10MB) by renaming to timestamped .bak and starting fresh.
CLI Reference
| Command | Description |
|---------|-------------|
| init | Interactive setup wizard. Creates ~/.agentgrit/, copies starter rubric, writes config. Accepts --quick, --standard, --full, or --import backup.json flags. |
| status | Signal counts, score trends, rule budget utilization |
| doctor | Health check across all five subsystems (capture, scoring, graph, rules, signals) |
| inbox | Review pending rule candidates with tier routing rationale |
| rules | List, rebalance, or compact rules across tiers |
| eval | Evaluate traces, sessions, or recall accuracy against rubrics |
| optimize | Hill-climb prompts or skill descriptions for a target dimension |
| graph | Build, query, or inspect the knowledge graph |
| review | Run the weekly learning review manually |
| signals | Check signal file sizes, trigger rotation |
| undo | Reverse recent rule promotions using the ledger |
| export | Export graph + rules + rubrics for machine migration |
| upgrade | Switch adoption speed (quick/standard/full) |
Usage Examples
# Setup
agentgrit init --quick               # Zero API keys, manual review
agentgrit init --standard            # One API key, LLM judge
agentgrit init --full                # Daemon + optimizer + Langfuse

# Daily use
agentgrit inbox                      # Review pending rule candidates
agentgrit status                     # Check signal counts and trends
agentgrit doctor                     # Verify everything is healthy

# Evaluation
agentgrit eval traces                # Score recent traces against rubric
agentgrit eval traces --local        # Score from local JSONL only

# Optimization
agentgrit optimize prompts \
  --dimension task-completion \
  --rounds 3                         # Hill-climb a specific dimension

# Graph
agentgrit graph build                # Incremental graph rebuild
agentgrit graph query "testing"      # Find rules relevant to testing

# Maintenance
agentgrit rules rebalance            # Route rules to correct tiers
agentgrit signals rotate             # Rotate oversized signal files
agentgrit undo                       # Reverse recent promotions
Rubrics
A rubric defines what "good" means for your domain. It's a JSON file with scored dimensions.
The starter rubric (rubrics/starter.json) ships with every install and covers four universal quality dimensions:
| Dimension | Weight | What It Measures | |-----------|--------|-----------------| | task-completion | 30% | Did the output accomplish what was asked? | | accuracy | 30% | Are all claims, code, and references correct? | | conciseness | 20% | Is the output minimal without losing clarity? | | safety | 20% | Does it avoid destructive actions, data loss, security issues? |
Writing a Custom Rubric
Create a JSON file in ~/.agentgrit/rubrics/:
{
  "version": "1.0",
  "schemaVersion": 1,
  "dimensions": [
    {
      "name": "code-correctness",
      "description": "Does the generated code compile and handle edge cases?",
      "weight": 0.40,
      "rubric": "Score 1-5. 1=syntax errors or broken logic. 3=works for happy path. 5=handles edge cases, proper error handling."
    },
    {
      "name": "test-coverage",
      "description": "Are tests included and do they cover meaningful scenarios?",
      "weight": 0.35,
      "rubric": "Score 1-5. 1=no tests. 3=happy path tested. 5=edge cases, error paths, and regressions covered."
    },
    {
      "name": "documentation",
      "description": "Are changes documented appropriately?",
      "weight": 0.25,
      "rubric": "Score 1-5. 1=no docs. 3=basic comments. 5=clear commit message, updated README if needed."
    }
  ],
  "judgeModel": "gemini-2.5-flash"
}
Rules for rubrics:
- Dimension weights must sum to 1.0 (tolerance: 0.01)
- Dimension names must be unique
schemaVersionis required (currently1)- Multiple rubrics compose: both run independently, scores are tracked separately per dimension
Reference the rubric in your config by filename: rubrics: ["starter.json", "coding.json"].
Architecture
agentgrit/
├── bin/                          CLI entry point + 13 command modules
│   ├── agentgrit.ts                 CLI dispatcher (lazy-loads commands)
│   └── commands/
│       ├── init.ts                  Setup wizard
│       ├── inbox.ts                 Rule candidate review
│       ├── status.ts               Signal/score/rule summary
│       ├── doctor.ts               Health diagnostics
│       ├── rules.ts                Rule management
│       ├── eval.ts                 Trace/session/recall evaluation
│       ├── optimize.ts             Hill-climbing optimization
│       ├── graph.ts                Graph build/query/stats
│       ├── review.ts               Manual weekly review
│       ├── signals.ts              Signal file management
│       ├── undo.ts                 Promotion rollback
│       ├── export.ts               Portable export
│       └── upgrade.ts              Adoption speed switch
│
├── src/
│   ├── capture/                  Signal capture (hooks)
│   │   ├── rating.ts                Explicit ratings + keyword sentiment
│   │   ├── corrections.ts           Correction language detection
│   │   ├── skills.ts                Skill invocation logging
│   │   ├── debrief.ts               Session-end rule extraction
│   │   ├── tool-audit.ts            Tool usage recording
│   │   └── index.ts                 Hook config generation + re-exports
│   │
│   ├── evaluate/                 Quality scoring
│   │   ├── judge.ts                 LLM-as-judge (Gemini/Claude/OpenAI)
│   │   ├── rubric.ts                Rubric loading, validation, composition
│   │   ├── session.ts               Session-level composite scoring
│   │   ├── recall.ts                Recall accuracy evaluation
│   │   └── analysis.ts              Score aggregation and reporting
│   │
│   ├── detect/                   Pattern recognition
│   │   ├── failures.ts              Correction-based failure patterns
│   │   ├── patterns.ts              Cross-signal pattern mining
│   │   ├── trajectories.ts          High-rated session episode store
│   │   └── theme-cohorts.ts         Rule theme grouping
│   │
│   ├── promote/                  Rule management
│   │   ├── router.ts                Three-tier routing logic
│   │   ├── rules.ts                 Rule tracking and correlation
│   │   ├── budget.ts                Per-tier cap enforcement + learned budget
│   │   ├── bridge.ts                Atomic CLAUDE.md writer (7-day cooling)
│   │   ├── evict.ts                 Staleness, correlation, duplicate eviction
│   │   ├── ledger.ts                Promotion history + undo
│   │   ├── review.ts               Weekly learning review
│   │   └── domain-review.ts        Auto-review rule-domains.json
│   │
│   ├── optimize/                 Hill-climbing optimization
│   │   ├── hill-climb.ts            Generic propose-evaluate engine
│   │   ├── weight-optimizer.ts      RRF weight tuning via hill-climb
│   │   ├── prompt-tuner.ts          System prompt optimization
│   │   ├── skill-tuner.ts           Skill description optimization
│   │   ├── skill-metrics.ts         Skill effectiveness metrics
│   │   └── benchmark.ts             Frozen benchmark corpus builder
│   │
│   ├── graph/                    Knowledge graph + retrieval
│   │   ├── types.ts                 Graph, BM25Index, cluster types
│   │   ├── builder.ts               Incremental graph construction
│   │   ├── query.ts                 Domain-based graph traversal
│   │   ├── bm25.ts                  Full-text search index
│   │   ├── retrieval.ts             Hybrid BM25+graph+RRF retrieval
│   │   ├── context.ts               Session-start context injection + learned rule filtering
│   │   ├── domain-propagation.ts    BM25 neighbor domain propagation
│   │   ├── embedder.ts              Vector embeddings (optional)
│   │   └── index.ts                 Public API re-exports
│   │
│   ├── adapters/                 Data layer
│   │   ├── types.ts                 All shared interfaces
│   │   ├── jsonl.ts                 Atomic JSONL read/write/rotate
│   │   ├── paths.ts                 Path resolution (~/.agentgrit/)
│   │   ├── claude-code.ts           Claude Code hook + CLAUDE.md integration
│   │   └── time.ts                  Time utilities
│   │
│   └── daemon/                   Background automation
│       ├── daemon.ts                Main loop (30-min + weekly cycles)
│       ├── doctor.ts                Five-section health diagnostics
│       ├── scheduler.ts             LaunchAgent/systemd installer
│       └── cleanup.ts               Stale file removal + signal rotation
│
├── rubrics/
│   └── starter.json              Universal starter rubric
│
├── templates/
│   └── hooks.json                Hook registrations for settings.json
│
├── agentgrit.config.ts           Three preset configurations
├── package.json                  @agentgrit/core
└── tsconfig.json
Data Flow
Module writes →                         → Module reads
───────────────────────────────────────────────────────
capture/rating.ts    → ratings.jsonl    → evaluate/judge.ts, detect/patterns.ts
capture/corrections  → corrections.jsonl → detect/failures.ts, detect/patterns.ts
capture/skills.ts    → skills.jsonl     → detect/patterns.ts, evaluate/recall.ts
evaluate/judge.ts    → scores.jsonl     → daemon/daemon.ts, optimize/*
detect/failures.ts   → (in memory)      → promote/router.ts
promote/bridge.ts    → CLAUDE.md        → (Claude Code reads at session start)
promote/ledger.ts    → promotions.jsonl → bin/commands/undo.ts
graph/builder.ts     → knowledge-graph.json → graph/query.ts, graph/context.ts
graph/bm25.ts        → (in memory)      → graph/retrieval.ts
optimize/hill-climb  → experiments.jsonl → (human review)
detect/trajectories  → trajectories.json → graph/context.ts
daemon/daemon.ts     → daemon.log       → daemon/doctor.ts
State Files
All state lives under ~/.agentgrit/ (override with AGENTGRIT_DIR env var):
~/.agentgrit/
├── config.json              User configuration (written by init)
├── signals/                 JSONL signal files (append-only)
│   ├── ratings.jsonl
│   ├── corrections.jsonl
│   ├── skills.jsonl
│   ├── scores.jsonl
│   └── tool-audit.jsonl
├── state/                   Computed state
│   ├── knowledge-graph.json
│   ├── promotions.jsonl
│   ├── experiments.jsonl
│   └── trajectories.json
├── rubrics/                 Rubric definitions
│   └── starter.json
├── daemon.log               Daemon stdout
└── daemon.err               Daemon stderr
Configuration
agentgrit.config.ts exports three presets (quick, standard, full). After init, your active config lives at ~/.agentgrit/config.json.
| Field | Type | Default | Description |
|-------|------|---------|-------------|
| signalDir | string | ~/.agentgrit/signals | Where JSONL signal files are stored |
| adapter | "local" | "langfuse" | "both" | "local" | Data source adapter |
| langfuse.publicKey | string | — | Langfuse public key (Full Auto only) |
| langfuse.secretKey | string | — | Langfuse secret key (Full Auto only) |
| langfuse.baseUrl | string | https://us.cloud.langfuse.com | Langfuse API base URL |
| judge.provider | "gemini" | "claude" | "openai" | "gemini" | LLM judge provider |
| judge.model | string | "gemini-2.5-flash" | Judge model ID |
| judge.apiKey | string | — | Judge API key (env var recommended) |
| rubrics | string[] | ["starter.json"] | Rubric filenames to load |
| rules.globalBudget | number | 25 | Max rules in global CLAUDE.md |
| rules.projectBudget | number | 25 | Max rules per project CLAUDE.md |
| rules.autoPromote | boolean | false | Auto-promote without inbox review |
| rules.learnedBudget | number | 50 | Max rules in CLAUDE-LEARNED.md |
| rules.pendingExpiryDays | number | 30 | Days before pending rules expire |
| thresholds.coolingPeriodDays | number | 7 | Days before a proposed rule can promote |
| thresholds.ratingLowThreshold | number | 4 | Rating below this = "bad" session |
| thresholds.correlationThreshold | number | 3.0 | Avg rating below this = eviction candidate |
| thresholds.similarityThreshold | number | 0.85 | Jaccard threshold for near-duplicate detection |
| thresholds.expansionDecay | number | 0.5 | Score decay for graph-expanded neighbors |
| thresholds.defaultDomains | string[] | ["verification","delivery","deployment"] | Fallback domains when detection returns empty |
| rrfWeights.bm25 | number | 2 | BM25 weight in hybrid retrieval |
| rrfWeights.graph | number | 0.5 | Graph expansion weight in hybrid retrieval |
| rrfWeights.vector | number | 1 | Vector similarity weight in hybrid retrieval |
| daemon.interval | string | "30m" ("0" = disabled) | Daemon cycle interval |
| daemon.weeklyDay | string | "sunday" | Day for weekly review cycle |
Environment variables:
AGENTGRIT_DIR— override the base directory (default:~/.agentgrit)
Testing
bun test                    # Run full test suite
bun test test/capture/      # Run tests for one module
bun test --watch            # Watch mode during development
Tests live in test/ mirroring src/ structure. Each module has isolated unit tests. Integration tests cover the capture-to-promote pipeline. CLI tests verify command output formatting.
The test suite uses fixture JSONL files with known patterns that must produce specific candidates, and noise files that must not trigger false positives.
Roadmap
v0.1.8 (current)
- 1436 tests across 112+ files
- Full PAI learning loop parity — 0 gaps, 13 hooks, real-time incident detection
- 44/44 Docker E2E tests — clean install, integration, PAI coexistence, parity features
- Enriched graph context — performance signals + failure patterns injected at session start
- 6 new capture subcommands — session-score, debrief, work-completion, incident-analysis, incident (PostToolUse), skill
- All 7 subsystems: capture, evaluate, detect, promote, optimize, graph, daemon
- CLI with 20+ commands +
init --importfor machine migration - Three adoption speeds (quick/standard/full)
- LLM judge with Gemini, Claude, and OpenAI support
- 3-way hybrid retrieval: BM25 (2x) + vector similarity (1x) + graph expansion (0.5x) via RRF merge
- Grid-searched RRF weights — 100 combos evaluated against gold set, optimal written to config
- Vector search in context injection — all-MiniLM-L6-v2 query embeddings fed into RRF merge
- BM25 neighbor domain propagation — 98% domain coverage across 16 domains
- Config-driven thresholds — all weights, budgets, and thresholds in config.json, not hardcoded
- Per-domain diversity cap — max 3 rules per domain per source in retrieval
- Rule effectiveness tracking — before/after correction frequency per rule
- Critical Rules demotion path — eviction system can demote even critical rules
- Docker E2E test suite — containerized end-to-end pipeline tests (4 phases)
- Hill-climbing optimizer for prompts, skills, and retrieval weights
- LaunchAgent (macOS) and systemd (Linux) scheduler
- Atomic CLAUDE.md writes with promotion ledger and undo (
--yesflag for non-interactive) - Published on npm as
@agentgrit/core
Planned
- CI/CD pipeline — automated changelog, release notes, npm publish on tag
- Migration cutover — parallel run, archive PAI hooks, verify (#75)
- Gold set rebuild with full task context for accurate eval
- VERSION constant should read from package.json
- Rubric discovery from correction history
- Example rubrics (sales, coding, support)
- Voyage AI reranking in hybrid retrieval
License
MIT