
@conduit-labs/conduit-ai
v0.1.2
Published
Reliable model execution with timeouts, retries, and fallback chains

Maintainers
 opuadm
Readme
Conduit AI
Conduit AI provides a compact interface for executing language model calls with consistent timeout, retry, and fallback behavior.
It is designed for applications that need predictable operational controls without repeating timeout and retry setup at every call site. A configured language model is passed into each request, so model selection and provider configuration remain under application control.
Features
- Per-request timeouts
- Configurable retry limits
- Ordered model fallback chains
- Provider-agnostic model inputs
- Full TypeScript declarations
- Direct access to generated text, usage, and response metadata
- Small public API with no global configuration
Requirements
- Node.js 22 or newer
- A compatible language model configured by the application
- Bun, npm, pnpm, or another compatible package manager
Installation
With Bun:
bun add @conduit-labs/conduit-aiWith npm:
npm install @conduit-labs/conduit-aiQuick start
The model can come from any compatible provider integration. In this example,
configuredModel is exported by the application's model configuration file.
import { configuredModel } from './models';
import { runModel } from '@conduit-labs/conduit-ai';

const result = await runModel({
  model: configuredModel,
  prompt: 'Explain event loops in one paragraph.',
});

console.log(result.text);
By default, a request has a 30 second timeout and allows two retries.
Configure timeout and retries
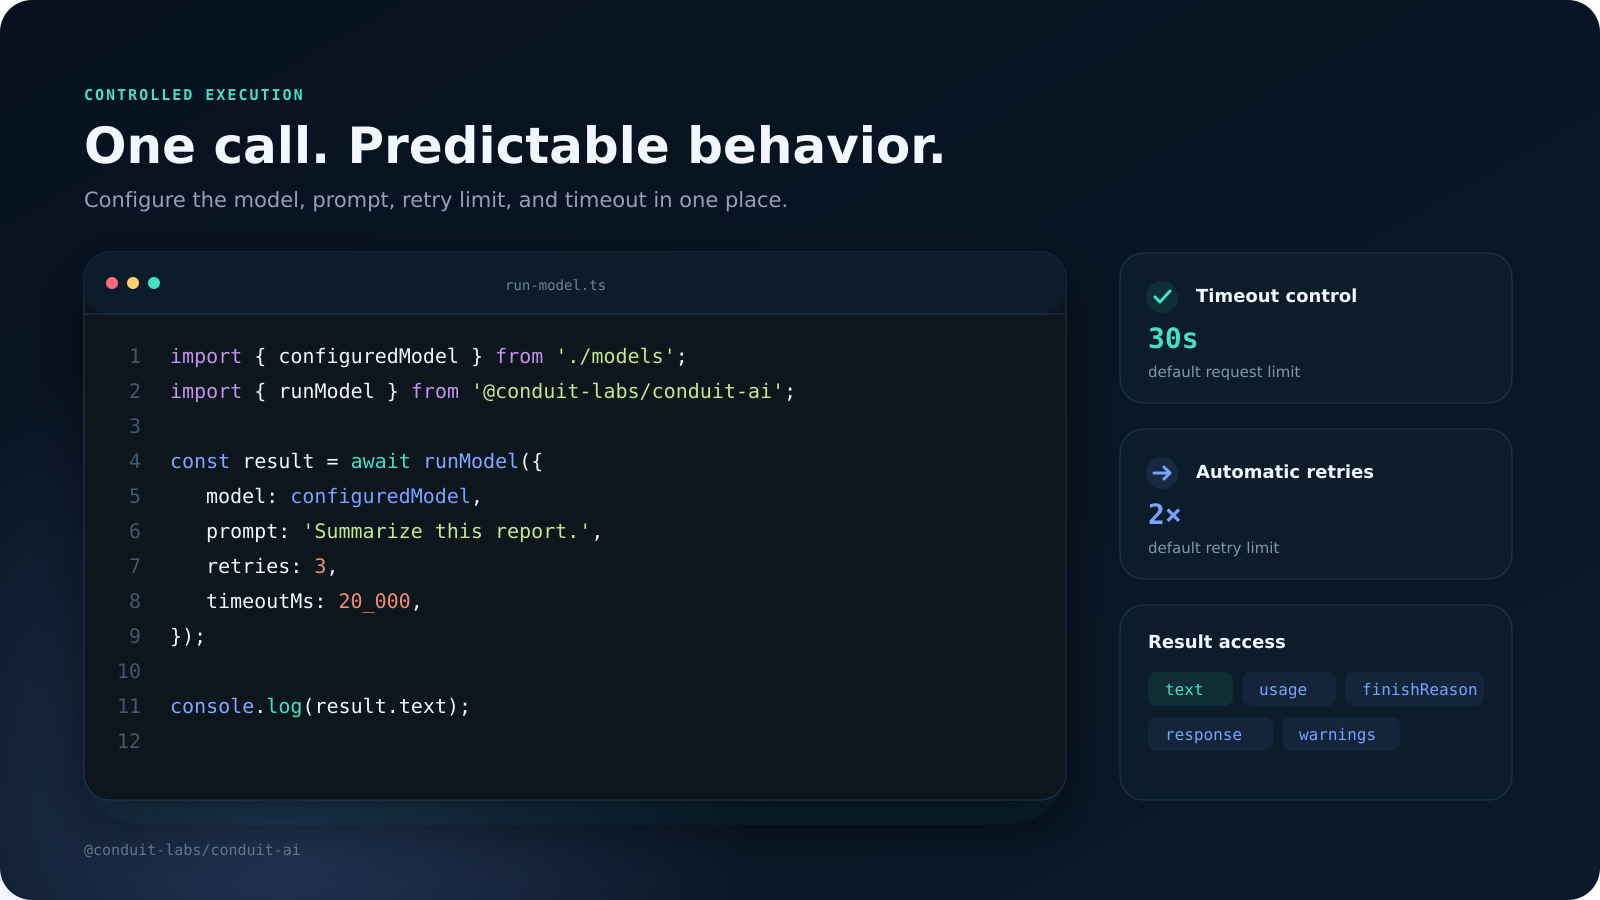
Use timeoutMs to limit each request and retries to control how many times a
failed request may be retried.
import { configuredModel } from './models';
import { runModel } from '@conduit-labs/conduit-ai';

const result = await runModel({
  model: configuredModel,
  prompt: 'Write a concise release summary.',
  retries: 3,
  timeoutMs: 20_000,
});

console.log(result.text);
The timeout is cleared as soon as the request completes. When the timeout is reached, the active request is aborted.
Use a fallback chain
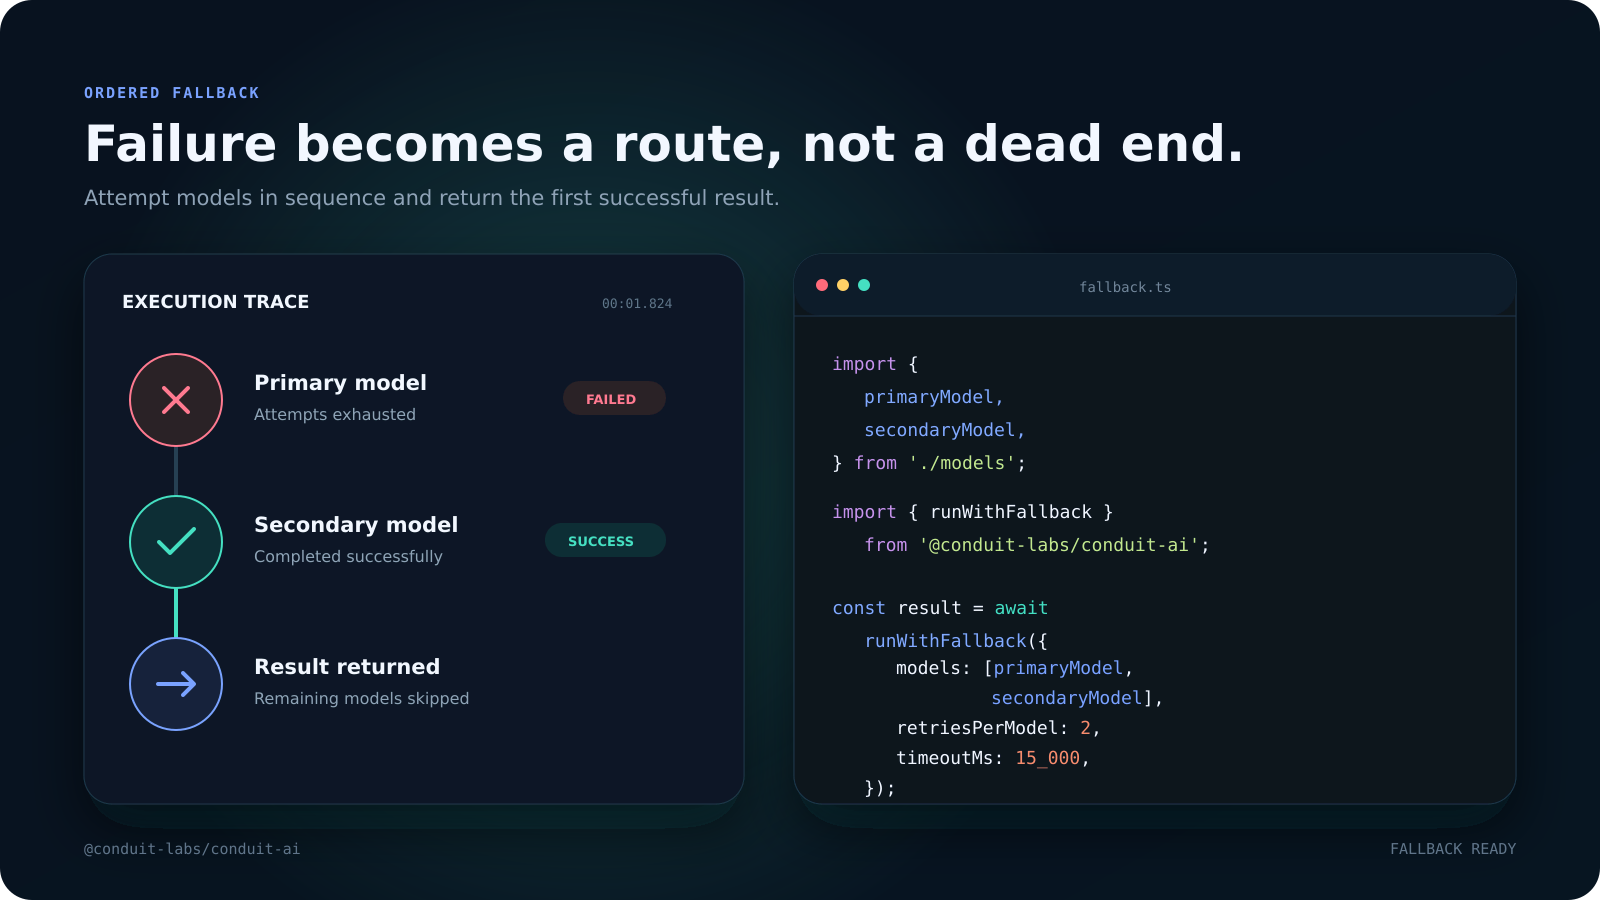
runWithFallback accepts an ordered list of models. Each model is attempted in
sequence. If one model fails after its retry limit is exhausted, the next model
is attempted.
import { primaryModel, secondaryModel } from './models';
import { runWithFallback } from '@conduit-labs/conduit-ai';

const result = await runWithFallback({
  models: [primaryModel, secondaryModel],
  prompt: 'Summarize the supplied report.',
  retriesPerModel: 2,
  timeoutMs: 15_000,
});

console.log(result.text);
The timeout applies separately to each model attempt. The first successful result is returned immediately, and remaining models are not called.
Handle failures
Both functions reject when execution cannot produce a result. Standard
try and catch handling can be used around a request.
import { configuredModel } from './models';
import { runModel } from '@conduit-labs/conduit-ai';

try {
  const result = await runModel({
    model: configuredModel,
    prompt: 'Generate a status report.',
    timeoutMs: 10_000,
  });

  console.log(result.text);
} catch (error) {
  console.error('Model execution failed', error);
}
An empty fallback list throws At least one model is required. If every model
in a fallback chain fails, the final error is Every model attempt failed and
the last model error is available as its cause.
Results
The underlying generation result is returned without reducing it to a custom response shape. Applications can access the generated text along with usage, finish reason, response metadata, warnings, and other available result fields.
const result = await runModel({
  model: configuredModel,
  prompt: 'Describe the request lifecycle.',
});

console.log(result.text);
console.log(result.usage);
console.log(result.finishReason);
API reference
runModel(options)
Executes one configured model.
Options:
model: The language model used for generation.prompt: The text prompt sent to the model.retries: Optional retry limit. Defaults to2.timeoutMs: Optional timeout in milliseconds. Defaults to30000.
runWithFallback(options)
Attempts configured models in order until one succeeds.
Options:
models: An ordered, non-empty list of language models.prompt: The text prompt sent to each attempted model.retriesPerModel: Optional retry limit for each model. Defaults to2.timeoutMs: Optional per-model timeout in milliseconds. Defaults to30000.
Operational guidance
- Put the preferred model first in a fallback chain.
- Use shorter timeouts for interactive requests.
- Use longer timeouts for background generation tasks.
- Keep retry counts low when providers already perform internal retries.
- Log the final error cause when every fallback model fails.
- Track usage data when enforcing application limits or budgets.
License
MIT