
@goopil/clusterkit
v2.2.1
Published
Zero-dependency Node.js cluster orchestrator for containers: SO_REUSEPORT detection, graceful shutdown with ACK protocol, crash circuit breaker, worker recycling and cgroup-aware sizing.

Maintainers
 goopil
Readme
@goopil/clusterkit
Core orchestrator for multi-worker Node.js servers.
This README focuses on the package-level contract (capabilities, options, API). For monorepo context and examples catalog, see the root README.
Capabilities
| Capability | Details |
|------------|---------|
| Worker orchestration | Spawns and supervises workers with cluster |
| Platform capability detection | Orchestrator.getCapabilities() reports platform, reusePort |
| Crash protection | Exponential restart backoff + circuit breaker (restart.*) |
| Health & recovery | Worker heartbeats, RSS recycling, wedged-worker detection, sustained-lag recycling, fleet health, boot-loop quarantine (health.*, workers.maxRssMb) |
| Graceful shutdown | ACK-based worker shutdown, configurable timeouts/signals (shutdown.*) |
| Worker start context | run(({listen, shutdown})) — platform-aware server listen + shutdown registration |
| Lifecycle controls | Worker recycling (workers.maxAgeMs), env patching and worker-count override APIs |
| Observability | Typed events, getMetrics(), getHealth(), getFleetHealth() |
| Plugin system | use(plugin) with install/uninstall lifecycle |
Installation
pnpm add @goopil/clusterkitQuick start
import { createServer } from "node:http";
import { Orchestrator } from "@goopil/clusterkit";

const orchestrator = new Orchestrator({ logger: console });

// This callback runs in every worker process
orchestrator.run(async ({ listen, shutdown }) => {
  const server = createServer((_req, res) => {
    res.end("ok");
  });

  // Platform flags (SO_REUSEPORT + exclusive on Linux, cluster IPC elsewhere)
  // are injected. Defaults: PORT env (fallback 3000) on 0.0.0.0.
  const bound = listen(server);

  shutdown(() => bound.close());
});
Worker count
| Condition | Workers spawned |
|--------------------------------------------------|-----------------------------|
| workers.count: 'auto' + WEB_CONCURRENCY set | Value of WEB_CONCURRENCY |
| workers.count: 'auto' + SO_REUSEPORT available | os.availableParallelism() |
| workers.count: 'auto' + no SO_REUSEPORT | os.availableParallelism() with cluster round-robin |
| workers.count: N | Exactly N workers |
macOS note — SO_REUSEPORT detection is unreliable on macOS. Use
WEB_CONCURRENCY=4to force multi-worker mode, or test on Linux with the Docker harness described in the root README.
Configuration options
Unknown keys inside a section (workers, restart, shutdown, health) are ignored but emit a
ClusterKitConfigWarning — with a suggestion when the key exists in another section (e.g. health.maxRssMb →
"did you mean 'workers.maxRssMb'?"). Unsupported top-level keys throw.
Top-level (OrchestratorConfig)
| Option | Type | Default | Description |
|--------|------|---------|-------------|
| logger | Logger \| null | null | pino/winston/console-compatible logger |
| workers | WorkersConfig | {} | Worker count/process options |
| restart | RestartConfig | {} | Crash handling + restart policy |
| shutdown | ShutdownConfig | {} | Shutdown lifecycle options |
| health | HealthConfig | {} | Worker health monitoring options |
workers
| Option | Type | Default | Description |
|--------|------|---------|-------------|
| count | number \| 'auto' | 'auto' | Number of workers |
| env | NodeJS.ProcessEnv | undefined | Extra env vars merged into worker env (security guards apply, see below) |
| execArgv | string[] | undefined | Node.js args passed to workers (dangerous flags blocked, see below) |
| maxAgeMs | number | 0 | Worker recycling interval (0 disables) |
| maxRssMb | number | 0 | Recycle a worker whose RSS exceeds this value in MB, through the bounded drain (0 disables). RSS is reported by the health heartbeat, so it requires health.heartbeatMs > 0 |
A practical container recipe for maxRssMb: budget ≈ 70 % × (cgroup memory limit − primary-process overhead) / workers.
Leave headroom because RSS includes V8 overhead that --max-old-space-size does not control. On Linux the cgroup limit
is what the container actually gets; @goopil/clusterkit-sizing can compute the whole plan for you.
Security guards
execArgvblocklist — flags that load or execute arbitrary code, attach a debugger, or write diagnostics to disk are rejected with aWorkerManagerValidationError:--require/-r,--eval/-e,--print/-p,--inspect/--inspect-brk/--inspect-port,--import,--loader/--experimental-loader,--tls-keylog,--cpu-prof*,--heap-prof*,--report-*,--diagnostic-dir, and--redirect-warnings. Code-loading and debug flags are blocked because a JSON/YAML config could otherwise carry remote code into every worker; profiling and diagnostic flags are blocked because they silently write files (or leak TLS keys) from every worker.envprototype-pollution guard — the keys__proto__,constructor, andprototypeare rejected in every env path: the config,patchWorkerEnv(), and therestartWorkers()env overlay.NODE_OPTIONSadvisory — aNODE_OPTIONSkey inworkers.envis accepted but emits aClusterKitSecurityWarningat validation, becauseNODE_OPTIONScan carry--requireand bypass theexecArgvblocklist. Avoid it.
restart
| Option | Type | Default | Description |
|--------|------|---------|-------------|
| crashThreshold | number | 5 | Crash count before tripping circuit breaker |
| crashWindowMs | number | 60000 | Sliding window for crash counting |
| backoffMs | number | 1000 | Initial restart delay |
| maxBackoffMs | number | 30000 | Backoff upper bound |
| backoffMultiplier | number | 2 | Exponential backoff multiplier |
| stabilityWindowMs | number | 30000 | Crash-free time required to reset backoff (0 = immediate reset) |
| bootFailQuarantine | number | 0 | Consecutive boot failures (worker exits before its first online) before the slot is quarantined — the primary stops re-forking it while other workers serve (0 disables). Remedy: restartWorkers() |
Restart/backoff is cluster-level, not worker-local. Every non-graceful worker exit is recorded in the crash window and
queued for replacement unless shutdown is already in progress or the circuit breaker has tripped. Replacements are
started one at a time through the restart queue, using the current backoff delay. A healthy worker that was not part of
the crash does not reset the delay by itself; backoff resets only after a replacement has stayed online for
stabilityWindowMs without another crash. This keeps partial flapping conservative while avoiding a full-cluster stop
unless crashThreshold is reached inside crashWindowMs.
shutdown
| Option | Type | Default | Description |
|--------|------|---------|-------------|
| timeoutMs | number | 12000 | Max graceful shutdown duration before forced kill |
| ackTimeoutMs | number | 3000 | Max wait for worker ACK before disconnecting that worker |
| messagePrefix | string | "__wm" | Internal IPC message prefix |
| sigtermDelayMs | number | 2000 | Delay before escalating SIGTERM -> SIGINT |
| sigintDelayMs | number | 1000 | Delay before escalating SIGINT -> SIGKILL |
health
| Option | Type | Default | Description |
|--------|------|---------|-------------|
| heartbeatMs | number | 0 | Worker health report (RSS, heap, event-loop lag) interval in ms (0 disables) |
| wedgedTimeoutMs | number | 0 | Recycle a worker whose heartbeat has been silent this long (0 disables). Requires heartbeatMs > 0 and ≥ 2 × heartbeatMs |
| degradedAfterMs | number | 0 | Duration active < target must persist before fleet:degraded fires (0 disables) |
| maxEventLoopLagMs | number | 0 | Recycle a worker whose reported event-loop lag exceeded this value (ms) for lagRecycleBeats consecutive beats (0 disables). Requires heartbeatMs > 0 |
| lagRecycleBeats | number | 3 | Consecutive heartbeats above maxEventLoopLagMs before the lag recycle fires (1 = first beat above the threshold) |
| lagSpikeMs | number | 0 | Recycle a worker on a single heartbeat whose event-loop lag exceeds this value (ms) — catches one-off long sync blocks the sustained-lag policy never sees (0 disables). Requires heartbeatMs > 0 |
Workers report RSS, heap, and event-loop beat drift over IPC every heartbeatMs; the primary-side monitor feeds four
opt-in policies: RSS recycling (workers.maxRssMb), wedged-worker detection (health.wedgedTimeoutMs), sustained
lag recycling (health.maxEventLoopLagMs), and one-off lag spikes (health.lagSpikeMs). A wedged
worker cannot ACK anything, so the drain escalates to SIGKILL. All policies run through the same bounded drain as
age-based recycling and never count toward the crash circuit breaker.
Health features work at every worker count: at count: 1 a single worker is forked and reports heartbeats over IPC
exactly like a larger fleet. Since 2.0 there is no no-fork mode — the primary is always a supervisor and the app always
runs in a worker process.
Migration to 2.0
workers.count: 1now forks one worker instead of running the app in the primary. The primary is a pure supervisor: OOM/wedge of the app no longer kills the process tree — the worker is restarted with backoff and the crash-loop breaker. Budget ~30-50 MB extra RSS for the extra process.orchestrator.isPrimaryis nowfalsein the application process at count 1. Gate primary-only resources onisPrimaryas you would in multi-worker mode.- Health features (heartbeats, RSS recycling, wedged detection, fleet degradation) work at count 1 — the 1.x startup warnings are gone.
- SIGHUP (plugin-signal-restart) and file/env watching (plugin-file-watcher) trigger in-process rolling restarts at count 1.
- Debugging: attach the inspector to the worker process — Node auto-increments cluster worker inspector ports.
Runtime API (high level)
const orchestrator = new Orchestrator(config);

await orchestrator.run(start); // start(ctx) runs in every worker — see below
orchestrator.use(plugin); // must be called before run() — throws afterwards
orchestrator.registerOnShutdown(cb);

orchestrator.overrideWorkerCount(4); // capped at 256
orchestrator.patchWorkerEnv({ NODE_OPTIONS: "--max-old-space-size=256" });

const metrics = orchestrator.getMetrics();
const health = orchestrator.getHealth();
const fleet = orchestrator.getFleetHealth(); // { target, active, quarantined, breaker }

orchestrator.isPrimary; // true in the primary (the supervisor), false in forked workers — incl. the app process at count 1

orchestrator.setNotReady(); // mark ready=false (e.g. during rolling deploys)
orchestrator.setReady();    // restore ready=true (no-op during shutdown)

orchestrator.resetCircuitBreaker(); // after fixing a crash-loop cause; refills missing workers
orchestrator.restartWorkers(opts);  // rolling-restart workers without dropping connections
orchestrator.workerCount;           // resolved worker count (number)

// restartWorkers opts: { env?: NodeJS.ProcessEnv, filter?: (id: number) => boolean, staggerMs?: number, reason?: string }

const supportsReusePort = await Orchestrator.supportsReusePort();
const capabilities = await Orchestrator.getCapabilities();
Worker start context (run(start))
The start callback receives a context that abstracts the per-worker listen/shutdown plumbing:
interface WorkerStartContext {
  // Binds target.listen() with the right platform flags — SO_REUSEPORT +
  // exclusive when the kernel balances connections across workers, cluster
  // IPC round-robin otherwise. Defaults: PORT env (fallback 3000) on 0.0.0.0.
  // Returns whatever target.listen() returns (the bound server).
  listen<T extends Listenable>(target: T, opts?: { port?: number | string; host?: string }): ReturnType<T["listen"]>;
  // Same as orchestrator.registerOnShutdown(cb).
  shutdown(cb: (signal: string) => void | Promise<void>): void;
}listen()is synchronous (SO_REUSEPORT support is resolved once before the callback runs) and works with any Node-style listen target: an express app, a rawhttp.Server, a Koa app,fastifyInstance.server, NestJSgetHttpServer().- Close stays explicit — register it with
shutdown(() => server.close())(or a framework-specific close such as NestJSapp.close()). registerOnShutdown()andOrchestrator.getCapabilities()remain available unchanged.
Lifecycle and shutdown semantics
The primary process owns worker supervision, restart policy, plugin installation, and coordinated shutdown. Worker
processes only run the application bootstrap passed to run() and any shutdown callbacks registered with
registerOnShutdown().
During SIGTERM or SIGINT, the primary coordinates a clean shutdown:
- Sends an IPC shutdown message to all workers
- Waits for each worker to ACK, exit, or disconnect (max
shutdown.ackTimeoutMsper worker) - Calls
worker.disconnect()on all workers - Waits up to
shutdown.timeoutMsfor workers to exit cleanly - Force-kills any remaining workers (
SIGTERM→SIGINT→SIGKILL) - Calls
plugin.uninstall()on all registered plugins - Exits the primary with code
0
In each worker, the shutdown sequence is:
- Receives IPC message (or
SIGTERM/SIGINT) - Sends ACK to primary
- Calls your shutdown callbacks (registered via
ctx.shutdown()in therun()callback, orregisterOnShutdown()) - Exits with code
0
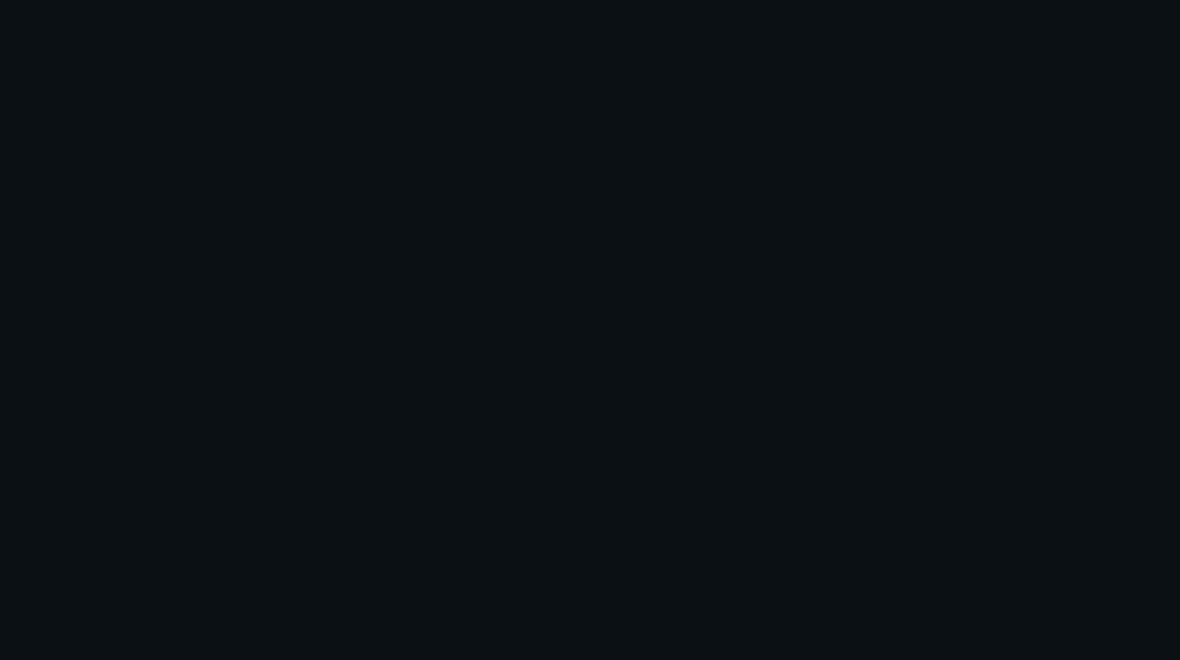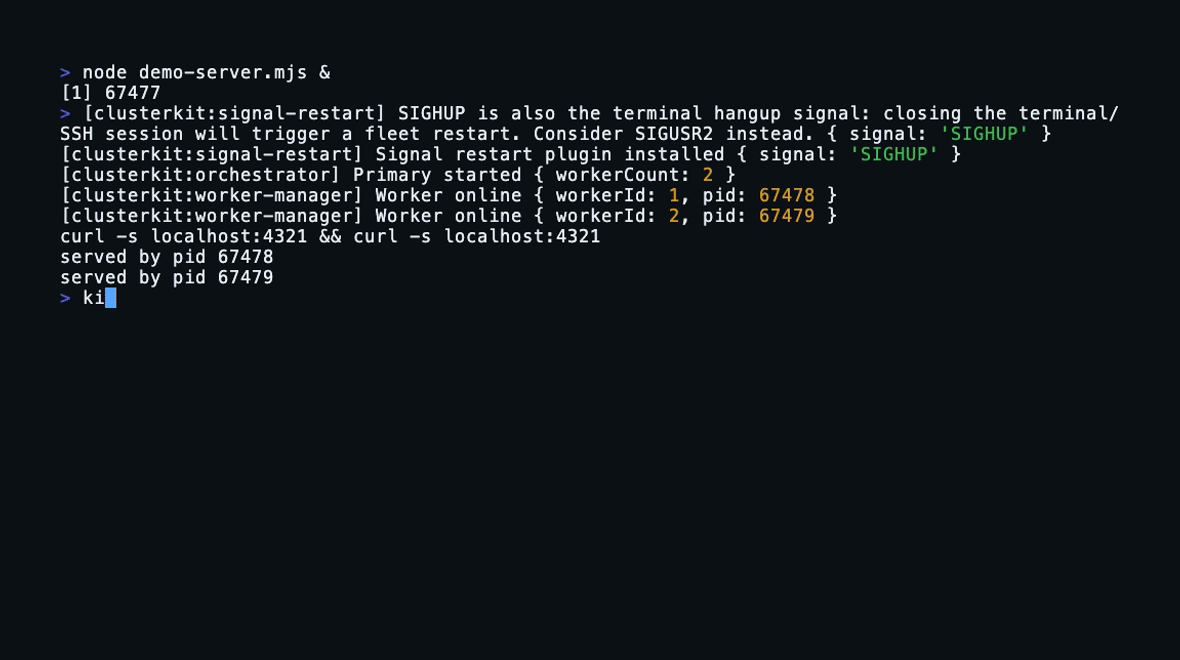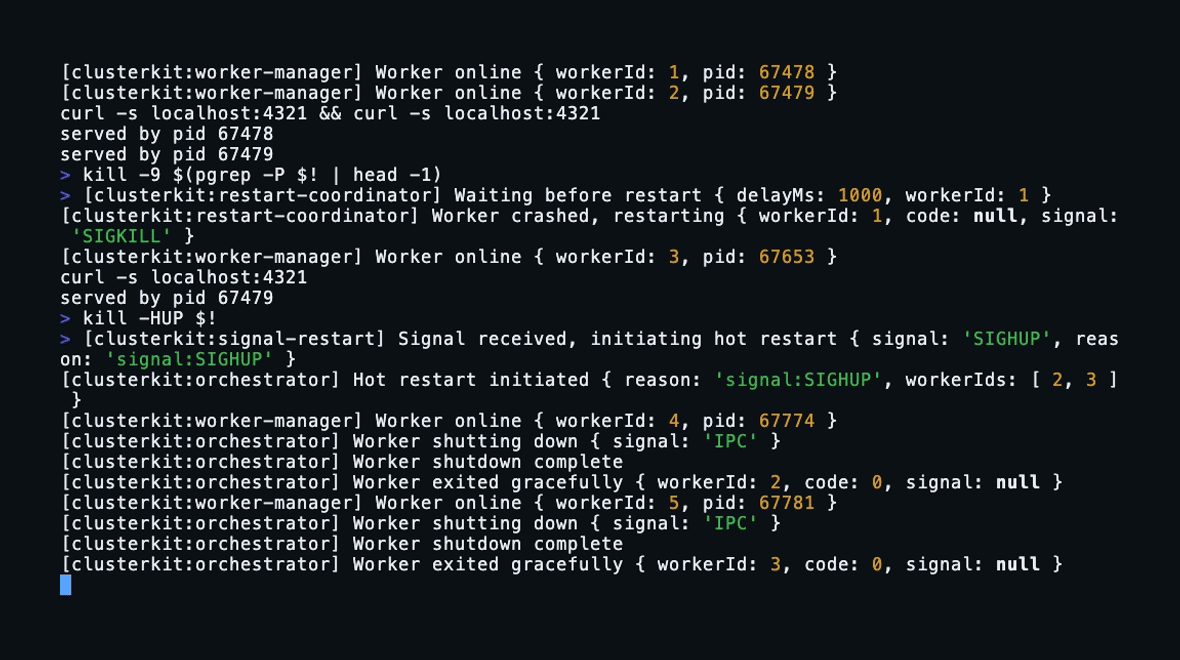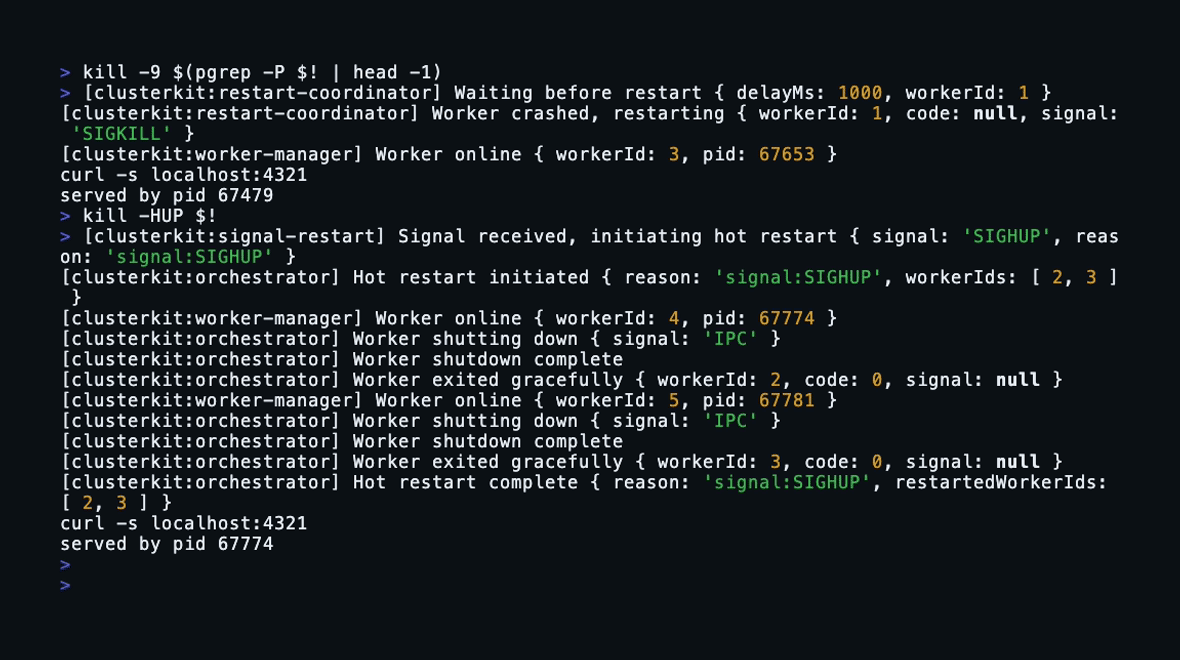
SIGHUP is a silent no-op on the primary (the handler is registered so Node's default behavior — terminating the
process — does not apply). If you need rolling restart functionality (e.g. for zero-downtime deployments on bare metal),
use a dedicated plugin instead.
ACK is the preferred cooperative signal, but a worker that terminates before sending ACK is also treated as complete for that ACK wait. This keeps container shutdown predictable when an application closes quickly or the process exits during its own cleanup path.
Register server cleanup in workers, not the primary:
orchestrator.run(async ({ listen, shutdown }) => {
  const server = createServer(handler);
  listen(server, { port: 3000 });

  shutdown(() => server.close());
});
Set shutdown.timeoutMs below your platform termination grace period so forced escalation can happen before the
container or process supervisor kills the primary process.
Circuit breaker
If workers crash more than restart.crashThreshold times within restart.crashWindowMs, the orchestrator stops
restarting them and emits circuit-breaker:tripped. This prevents infinite crash loops that would otherwise exhaust
system resources. Each trip also emits a process.emitWarning (code ClusterKitCrashLoop) so setups without a
configured logger are not fully silent. Restart queue entries are dropped once the breaker is tripped — after a
resetCircuitBreaker() call, missing capacity is refilled.
A failed worker fork (for example EMFILE/ENOMEM under resource exhaustion) no longer permanently shrinks the
fleet: the restart is re-queued and retried through the normal backoff. After 3 consecutive fork failures the
environment is treated as unrecoverable and the pending restarts are abandoned.
Exit codes
The primary flags a failure exit code (process.exitCode = 1) while the fleet is down or unrecoverable:
- any crash that empties the fleet (all workers down, replacements pending),
- the circuit breaker tripping (restarts stopped),
- 3 consecutive fork failures exhausting the restart queue (an environment that can no longer fork).
While the fleet is empty with restarts pending, the primary holds its event loop alive so the restart queue can
still fork replacements — the flag clears (process.exitCode = 0) as soon as full capacity is restored or a
resetCircuitBreaker() refill brings the fleet back. The primary only drains and exits — with the failure visible
to supervisors, Kubernetes, and process managers instead of masked as a clean exit 0 — when no more forks are
coming: a breaker trip or a dead fork environment. The hold is released on shutdown, so a graceful exit is never
delayed. Graceful shutdowns always exit with code 0.
Health checks
const health = orchestrator.getHealth();
// { ready: boolean, live: boolean }

// live is always true by design — readiness is the signal, not liveness
// ready becomes false during shutdown, after a circuit-breaker trip, or via setNotReady()
Use these with your Kubernetes liveness / readiness probes.
Typed events (OrchestratorEvents)
| Event | When it fires |
|-------|---------------|
| worker:online | A worker reaches the cluster online state. |
| worker:exit | A worker exits, including graceful disconnects and crashes. |
| worker:crash | A worker exits non-gracefully and is recorded in the crash window. |
| worker:restart | A replacement worker is forked after restart backoff. |
| worker:draining | A worker was marked for replacement, before the network drain starts — the moment new work should stop being routed to it: { workerId, pid, reason }. |
| worker:recycle | A worker is replaced through the bounded drain. reason is "maxAge" (default), "rss" (workers.maxRssMb exceeded), "wedged" (heartbeat silent for health.wedgedTimeoutMs), or "lag" (event-loop lag above health.maxEventLoopLagMs for health.lagRecycleBeats consecutive beats, or a single beat above health.lagSpikeMs). |
| worker:health | A worker reported health (requires health.heartbeatMs > 0): { workerId, pid, rss, heapUsed, eventLoopLagMs }. |
| worker:wedged | A worker's heartbeat was silent for health.wedgedTimeoutMs — it is recycled through the bounded drain: { workerId, pid, silentMs }. |
| worker:quarantined | A slot was quarantined after restart.bootFailQuarantine consecutive boot failures while other workers serve: { consecutiveBootFailures }. |
| fleet:degraded | active < target persisted for health.degradedAfterMs: { target, active }. |
| fleet:recovered | Capacity restored to target: { target, active, degradedDurationMs }. |
| shutdown:start | Primary shutdown coordination starts for SIGTERM or SIGINT. |
| shutdown:complete | Primary shutdown has finished — emitted after user shutdown callbacks and plugin uninstall(), in every mode. Plugins doing final work must do it in uninstall(): their shutdown:complete listener is removed before the event fires. |
| circuit-breaker:tripped | Crash count reached restart.crashThreshold inside restart.crashWindowMs. |
| restart:start | A hot restart cycle begins via restartWorkers(). |
| restart:complete | A hot restart cycle finishes — all targeted workers replaced. |
Stop accepting early on
worker:draining— for TCP, the listening socket and the established connections are separate: callingserver.close()in theworker:draininghandler removes the worker from theSO_REUSEPORTgroup immediately (the kernel stops routing new connections to it) while existing connections keep draining, and Linux ≥ 5.10 migrates in-flight connection requests to the remaining group members. Onworker:recyclethe drain is already underway —worker:drainingfires earlier.
Capability helpers
Use Orchestrator.getCapabilities() when startup needs the full platform summary, and
Orchestrator.supportsReusePort() when only SO_REUSEPORT support matters. Both helpers are asynchronous because
capability detection can probe the runtime platform. Most apps do not need them: the listen() helper from the
worker start context applies the right socket flags automatically.
Fleet health, quarantine and recovery
getFleetHealth() returns a point-in-time snapshot:
{ target: 4, active: 3, quarantined: 1, breaker: { count: 2, tripped: false } }target/active— configured worker count vs. currently online workers.quarantined— slots stopped by the boot-loop guard (see below).breaker— crash-window count and circuit-breaker state.
Boot-loop quarantine. A worker that exits without ever reaching online is a boot failure. After
restart.bootFailQuarantine consecutive boot failures — while the rest of the fleet is still serving — the slot is
quarantined: the primary stops re-forking it instead of burning forks in a loop. Quarantined boot failures write no
crash record, so one bad slot cannot trip the fleet circuit breaker.
Remedy. restartWorkers() clears the quarantine counters and refills the missing capacity — every slot gets a
fresh boot attempt as part of the roll. resetCircuitBreaker() also refills missing capacity but does not clear the
quarantine counters, so getFleetHealth().quarantined can over-report while such a refill is already serving the slot.
Recycle path. All recycle reasons (maxAge, rss, wedged, lag) share one bounded drain: the replacement is forked
first, then the old worker is retired through IPC shutdown → disconnect → SIGTERM → SIGKILL. RSS and wedged recycles
never count toward the crash circuit breaker.
Plugins
Extend the orchestrator with custom plugins:
import type {OrchestratorPlugin, Orchestrator} from '@goopil/clusterkit';

const myPlugin: OrchestratorPlugin = {
    name: 'my-plugin',

    async install(orchestrator: Orchestrator) {
        // Runs on the primary before workers are forked.
        // Use orchestrator.patchWorkerEnv() or orchestrator.overrideWorkerCount()
        // to influence worker configuration.
        orchestrator.on('worker:crash', ({workerId}) => {
            // send alert, update dashboard, etc.
        });
    },

    async uninstall(orchestrator: Orchestrator) {
        // cleanup — called automatically during shutdown
    },
};

orchestrator.use(myPlugin).run(/* ... */);
use() is chainable and plugins are installed in registration order. Plugins must be registered before run() —
calling use() afterwards throws.
Plugin helpers available in install():
// install(orchestrator, logger, config) receives the ResolvedConfig —
// read config.workers.count / config.workers.env for the current settings.
orchestrator.patchWorkerEnv(env)        // merge env vars into workerEnv
orchestrator.overrideWorkerCount(n)     // override an 'auto' worker count (max 256)
Plugins install before the initial fork, so both helpers apply to the whole fleet. They throw if called after workers have been forked.