
@metaharness/router
v0.4.1
Published
Cost-optimal model router for agent harnesses: sends each query to the cheapest model that is good enough, using k-NN over labelled embeddings.

Maintainers
 ruvnet
Readme
@metaharness/router
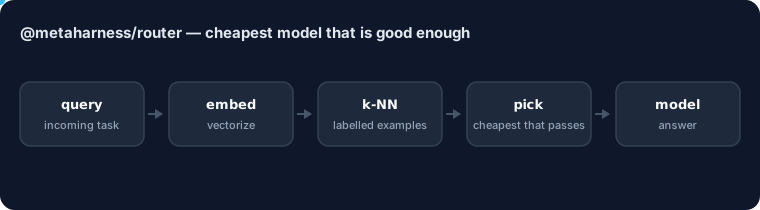
@metaharness/router routes each query to the cheapest model that is predicted to be good enough. For every candidate model it predicts quality on the new query by k-NN over that model's labelled examples (query embedding and the quality it achieved), then returns the cheapest candidate that clears your quality bar.
Supported environments: Node.js 20+ on Linux, macOS and Windows. ESM library, no dependencies, no model files and no network. Bring vectors from any embedding model.
Quickstart
mkdir demo && cd demo && npm init -y >/dev/null
npm install @metaharness/router
cat > quickstart.mjs <<'JS'
import { Router } from '@metaharness/router';

// Two candidates, each with labelled examples: [query embedding, quality it achieved].
const router = new Router({
  k: 1,            // nearest labelled example decides (default 5)
  qualityBar: 0.8,
  candidates: [
    { id: 'small-model', costPerMTok: 1, examples: [
      { embedding: [1, 0], quality: 0.9 },   // good on "type A" queries
      { embedding: [0, 1], quality: 0.4 },   // weak on "type B" queries
    ] },
    { id: 'large-model', costPerMTok: 15, examples: [
      { embedding: [1, 0], quality: 0.95 },
      { embedding: [0, 1], quality: 0.9 },
    ] },
  ],
});

console.log('type A:', router.route([0.9, 0.1]));
console.log('type B:', router.route([0.1, 0.9]));
JS
node quickstart.mjs
Expected output:
type A: {
  id: 'small-model',
  costPerMTok: 1,
  predictedQuality: 0.9,
  metBar: true
}
type B: {
  id: 'large-model',
  costPerMTok: 15,
  predictedQuality: 0.9,
  metBar: true
}
Next: @metaharness/harness — wrap the routed models as workers behind safety gates and receipts.
Reference
Route each query to the cheapest model that's good enough. The productized
form of the DRACO Phase-2 finding (ruvnet/agent-harness-generator, ADR-040):
on cross-domain research, structure/fusion does not beat a strong model on
quality — but routing each query to the right, cheapest model is a measured
Pareto win. A learned embedding router beat the best fixed model on DRACO, and
its accuracy rises monotonically with training data (the learning curve).
Dependency-free, no model files, no network. Bring any embedding model; the router only needs the vectors.
Install
npm install @metaharness/routerUse
import { Router } from '@metaharness/router';

const router = new Router({
  qualityBar: 0.8, // cost-optimal: cheapest candidate predicted to clear 0.8
  candidates: [
    {
      id: 'anthropic/claude-haiku-4.5',
      costPerMTok: 3,
      examples: [ /* { embedding, quality } from your eval logs */ ],
    },
    {
      id: 'anthropic/claude-opus-4',
      costPerMTok: 45,
      examples: [ /* ... */ ],
    },
  ],
});

const pick = router.route(queryEmbedding);
// → { id, predictedQuality, costPerMTok, metBar }
For each candidate the router predicts quality on the new query via k-NN over
that candidate's labelled examples (query embedding → quality it achieved),
then returns the cheapest candidate predicted to clear qualityBar (or the
best-predicted if none clear it / no bar is set). Feed it your own eval logs;
the more examples, the closer it gets to the per-query oracle (DRACO's learning
curve was still rising at n=19).
Why this and not "a bigger model" / "more structure"
DRACO measured it honestly: structure degrades quality, and a cheap model matches frontier quality at ~10× lower cost. The leverage is choosing the model, not wrapping it. This is that choice as a library.
Performance
route() is called once per query against a fixed candidate set, so
Router caches each candidate's example norms by object identity
(WeakMap<RouterCandidate, Float64Array>) instead of recomputing them
inside cosine() on every call, and computes the query's own norm once per
route() call instead of once per (candidate, example) pair. Behaviour is
unchanged — same k-NN, same tie-breaking, same public API — only the
redundant arithmetic is gone. Measured on bench/route-throughput.mjs
(npm run bench, deterministic synthetic data, 6 candidates):
| examples/candidate | embedding dim | before | after | |---|---|---|---| | 20 | 128 | 26,197 routes/s | 30,770 routes/s | | 200 | 128 | 2,430 routes/s | 2,801 routes/s | | 20 | 1536 | 4,332 routes/s | 5,236 routes/s | | 200 | 1536 | 421 routes/s | 498 routes/s |
~15–21% faster across the board. Full results in bench/results/.
MIT.
Trained router (kernel ridge regression)
For a learned, regularised router (vs. plain k-NN), train one from the same dataset — no model files, no native deps, pure TS (ADR-043):
import { trainRouter, TrainedRouter } from '@metaharness/router';

const { router, lambda, looQuality } = trainRouter(rows, prices, { qualityBar: 0.8 });
// rows: [{ embedding, scores: { modelId: quality } }]  · λ fit by leave-one-out CV
const pick = router.route(queryEmbedding);

// persist / reload the trained model (portable JSON)
const json = router.toJSON();
const same = TrainedRouter.fromJSON(json);
KRR with a cosine kernel is the regularised generalisation of k-NN; λ (fit by
LOO) controls the bias–variance trade-off that hurts k-NN on small data. On the
DRACO n=20 dataset it ties k-NN (the data ceiling); it's the router that
generalises better as your eval set grows.
Native FastGRNN router (optional, @ruvector/tiny-dancer)
The pure-TS router above needs zero native deps. For a trained native model,
the same { embedding, scores } dataset drives a real FastGRNN (Rust/NAPI,
gradients + Adam, persisted to .safetensors) — programmatically:
import { trainNativeRouter, NativeRouter, isNativeRouterAvailable } from '@metaharness/router';
// needs `npm i @ruvector/tiny-dancer` (optional peer); falls back to pure-TS otherwise
const res = await trainNativeRouter(rows, prices, { outputPath: './router.safetensors' });
const router = await NativeRouter.load({ modelPath: res.modelPath });
…or with zero code via the published CLI (validated on the DRACO routing dataset — trains at the full embedding dim, e.g. 1536):
npx ruvector tiny-dancer train draco.json --out model.safetensors --prices '{"haiku":1,"opus":15}'
npx ruvector tiny-dancer score model.safetensors --query @query.json   # high → route cheap
Pick the backend automatically with resolveRouterBackend('auto') ('native'
when tiny-dancer is installed, else 'js'). See ADR-043 for the measured data
ceiling and the train↔route dimension note.