
@power-seo/core
v1.0.19
Published
Framework-agnostic SEO analysis engines, types, and utilities

Maintainers
 ccbd.dev
Readme
@power-seo/core
Framework-agnostic SEO analysis engines, types, validators, and utilities — the shared foundation of the @power-seo ecosystem, usable as a standalone TypeScript library.



@power-seo/core is a zero-dependency TypeScript library that provides the low-level SEO primitives every other @power-seo package builds on: pixel-accurate title and meta-description validators, meta / Open Graph / Twitter Card tag builders, URL canonicalization, keyword-density analysis, text statistics, robots directive builders, a title-template engine, and a token-bucket rate limiter. It is framework-agnostic — it makes no assumptions about React, Next.js, or the DOM — so it runs unchanged in Next.js, Remix, Vite, plain Node.js, and Edge runtimes.
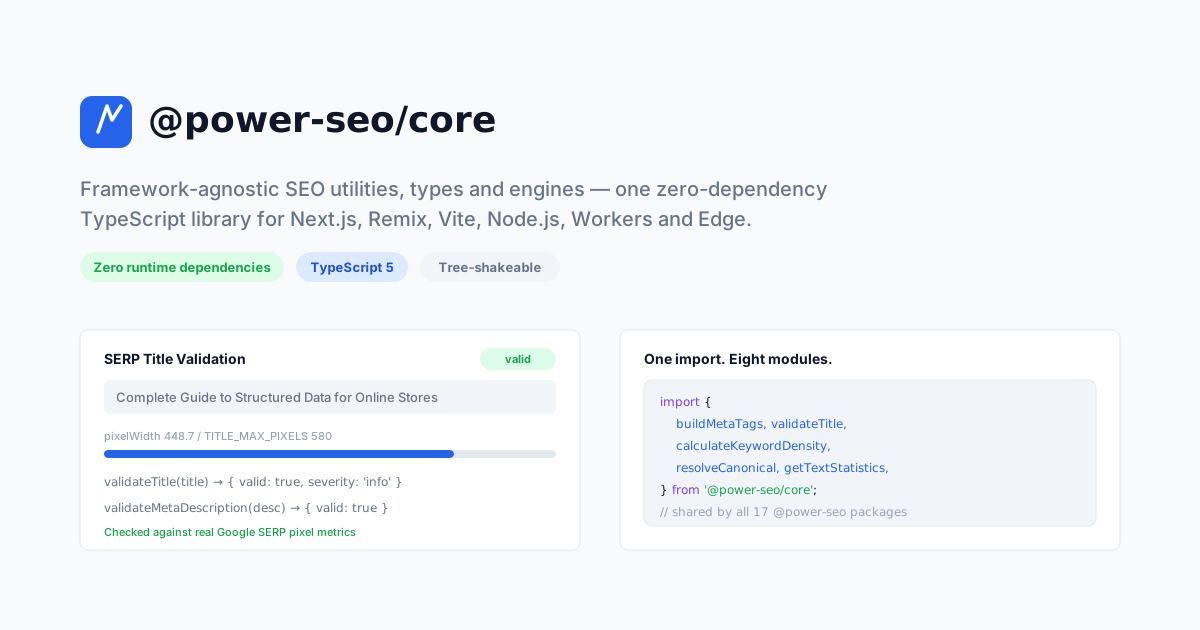
Zero runtime dependencies — installs clean with nothing else to pull in.
Why @power-seo/core?
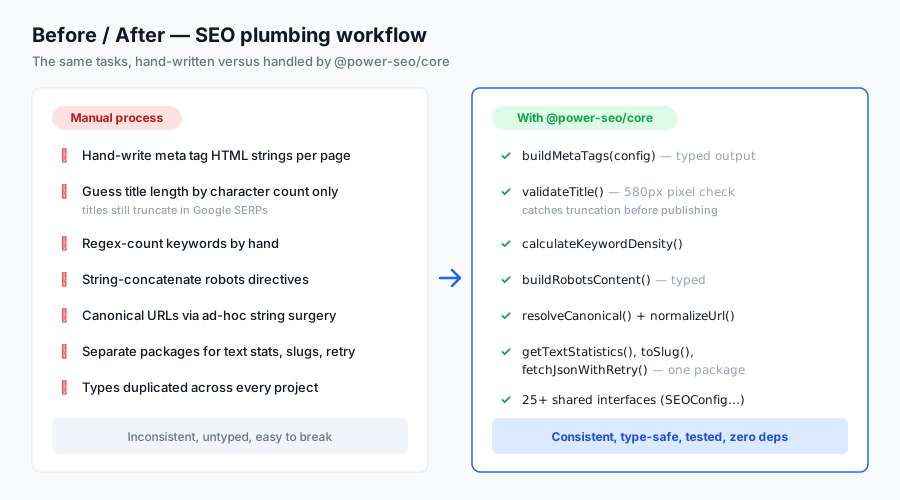
Most SEO helper code is scattered across single-purpose packages (keyword-density, url-normalize, text-statistics) or hand-rolled inline. @power-seo/core consolidates the primitives into one typed, tree-shakeable module so you import only the functions you use and share a single set of SEO constants and types across your codebase.
| | Without | With |
| -------------------- | -------------------------- | --------------------------------------------------------- |
| Meta tag building | Hand-written HTML strings | Type-safe buildMetaTags() with OG + Twitter |
| Title validation | Character count only | Pixel-accurate SERP width via validateTitle() |
| Keyword density | Manual regex counting | calculateKeywordDensity() returns count + density % |
| URL canonicalization | Ad-hoc string manipulation | resolveCanonical() + normalizeUrl() |
| Text statistics | Several separate packages | getTextStatistics() — words, sentences, syllables |
| Robots directives | Concatenated strings | Type-safe buildRobotsContent() / parseRobotsContent() |
| Rate limiting | No built-in utility | Token bucket via createTokenBucket() |
| Shared types | Duplicated across packages | One set of SEO interfaces and constants |
Features
- Meta tag builder —
buildMetaTags()returns a flatMetaTag[]from a typedSEOConfig; OG and Twitter title/description/url fall back to the top-level fields when not set explicitly - Open Graph builder —
buildOpenGraphTags()supportswebsite,article,profile,book,product, andvideo.*types, plus images, videos, article, and profile sub-tags - Twitter Card builder —
buildTwitterTags()forsummary,summary_large_image,player, andappcards - Hreflang builder —
buildHreflangTags()mapsHreflangConfig[]to<link rel="alternate">tags - Title template engine —
applyTitleTemplate()andcreateTitleTemplate()with%variable%substitution and dangling-separator cleanup - Pixel-accurate validators —
validateTitle()andvalidateMetaDescription()measure real SERP pixel width using Arial character metrics, not just character count - URL utilities —
resolveCanonical(),normalizeUrl(),toSlug(),stripTrackingParams(),extractSlug(),isAbsoluteUrl(), and more - Text statistics engine —
getTextStatistics()returns word, sentence, paragraph, syllable, and character counts from raw HTML - Keyword density —
calculateKeywordDensity()andanalyzeKeyphraseOccurrences()for single and multi-word keyphrases - Robots directives —
buildRobotsContent()/parseRobotsContent()round-trip between config objects and content strings - Rate limiting — token bucket with
createTokenBucket(),consumeToken(),getWaitTime(),calculateBackoff() - SEO constants — real values such as
TITLE_MAX_PIXELS = 580,KEYWORD_DENSITY = { MIN: 0.5, MAX: 2.5, OPTIMAL: 1.5 },OG_IMAGE,AI_CRAWLERS,SCHEMA_TYPES - Shared TypeScript types —
SEOConfig,MetaTag,OpenGraphConfig,TwitterCardConfig,RobotsDirective,ContentAnalysisInput, and more, reused across all 17 packages - ReDoS-free parsing —
stripHtml()and heading extraction use character scanners andindexOfloops instead of catastrophic-backtracking regex - Tree-shakeable —
"sideEffects": falsewith per-module named exports; dual ESM + CJS builds

Comparison
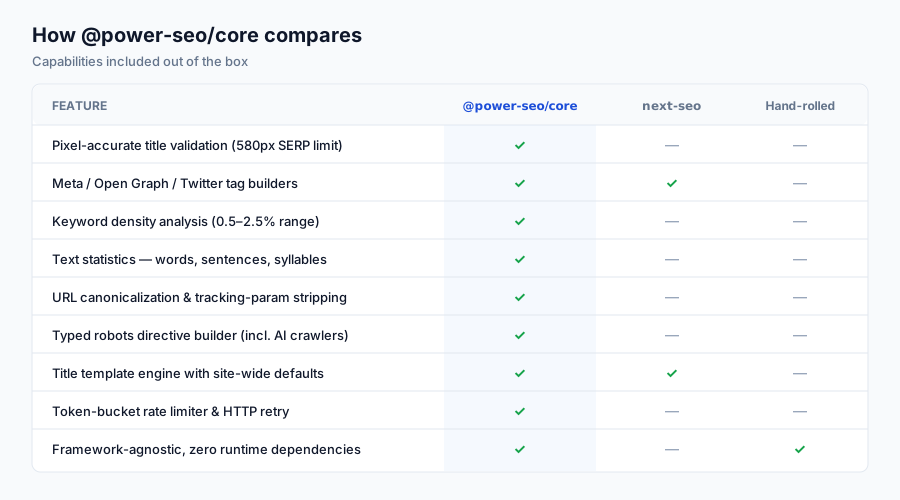
| Feature | @power-seo/core | next-seo | seo-utils | keyword-density | text-statistics | | ------------------------------------ | :-------------: | :------: | :-------: | :-------------: | :-------------: | | Meta tag builder | Yes | Partial | No | No | No | | Pixel-accurate title/meta validation | Yes | No | No | No | No | | Open Graph builder | Yes | Partial | No | No | No | | Twitter Card builder | Yes | Partial | No | No | No | | Keyphrase density calculator | Yes | No | No | Yes | No | | Keyphrase occurrence analysis | Yes | No | No | No | No | | Robots directive builder / parser | Yes | Partial | No | No | No | | URL normalization + slug | Yes | No | Partial | No | No | | Text statistics engine | Yes | No | No | No | Partial | | Title template engine | Yes | Partial | No | No | No | | Hreflang builder | Yes | Partial | No | No | No | | Token-bucket rate limiting | Yes | No | No | No | No | | Shared SEO types + constants | Yes | Partial | No | No | No | | Zero runtime dependencies | Yes | No | No | No | No |
Installation
npm install @power-seo/coreyarn add @power-seo/corepnpm add @power-seo/coreRequires Node.js >=18. Ships dual ESM + CJS builds with bundled .d.ts type declarations.
Usage
How do I build meta, Open Graph, and Twitter tags from one config?
Pass a single SEOConfig to buildMetaTags() and it returns a flat MetaTag[] array your framework renders into real <meta> elements. Open Graph and Twitter title, description, and url inherit from the top-level title, description, and canonical fields when you do not set them explicitly, so you avoid repeating yourself.
import { buildMetaTags, buildLinkTags, resolveCanonical } from '@power-seo/core';

const meta = buildMetaTags({
  title: 'Next.js SEO Guide',
  description: 'Master SEO in Next.js with structured data and meta tags.',
  canonical: 'https://example.com/nextjs-seo',
  robots: { index: true, follow: true, maxSnippet: 150, maxImagePreview: 'large' },
  openGraph: {
    type: 'article',
    images: [{ url: 'https://example.com/og.jpg', width: 1200, height: 630, alt: 'Next.js SEO' }],
  },
  twitter: { cardType: 'summary_large_image', site: '@mysite', creator: '@author' },
});
// meta → MetaTag[]  e.g. { name: 'description', content: '...' }, { property: 'og:title', content: '...' }

const links = buildLinkTags({
  canonical: resolveCanonical('https://example.com', '/nextjs-seo'),
});
// links → LinkTag[]  e.g. { rel: 'canonical', href: 'https://example.com/nextjs-seo' }
How do I check if a title will be truncated in Google search?
Character count is not what Google truncates on — pixel width is. validateTitle() and validateMetaDescription() sum per-character Arial widths (calculatePixelWidth()) and compare against TITLE_MAX_PIXELS (580) and META_DESCRIPTION_MAX_PIXELS (920). Each returns a ValidationResult with valid, severity ('error' | 'warning' | 'info'), a human-readable message, charCount, and pixelWidth.
import { validateTitle, validateMetaDescription } from '@power-seo/core';

const title = validateTitle('Best Running Shoes for Beginners — 2026 Buying Guide');
// { valid: true, severity: 'info', message: '...', charCount: 52, pixelWidth: ~289 }

const short = validateTitle('Shoes');
// { valid: true, severity: 'warning', message: 'Title is only 5 characters...', ... }

const meta = validateMetaDescription('Discover expert-reviewed running shoes for beginners.');
// { valid: true, severity: 'warning', ... }  // under 120 chars → warning to expand
How do I canonicalize and clean URLs?
The URL utilities normalize hosts, strip trailing slashes, remove tracking parameters, and generate slugs — all via the native URL API with no ReDoS-prone regex on user input.
import {
  resolveCanonical,
  normalizeUrl,
  toSlug,
  stripTrackingParams,
  stripQueryParams,
  extractSlug,
  isAbsoluteUrl,
} from '@power-seo/core';

resolveCanonical('https://example.com', '/blog/post');
// => "https://example.com/blog/post"

toSlug('My Blog Post Title! — 2026');
// => "my-blog-post-title-2026"

stripTrackingParams('https://example.com/page?utm_source=twitter&id=123');
// => "https://example.com/page?id=123"

stripQueryParams('https://example.com/page?utm_source=x&id=123', ['id']);
// => "https://example.com/page?id=123"

extractSlug('https://example.com/blog/my-post'); // => "my-post"
isAbsoluteUrl('/relative/path'); // => false
How do I measure keyword density and keyphrase placement?
calculateKeywordDensity(keyword, content) returns occurrence count, density percentage, and totalWords. For multi-word keyphrases the density weights by phrase word count. analyzeKeyphraseOccurrences(config) reports where the keyphrase appears — title, H1, first paragraph, sub-headings, slug, and image alt text.
import { calculateKeywordDensity, analyzeKeyphraseOccurrences } from '@power-seo/core';

const density = calculateKeywordDensity('react seo', bodyHtml);
// { keyword: 'react seo', count: 4, density: 1.8, totalWords: 450 }

const occurrences = analyzeKeyphraseOccurrences({
  keyphrase: 'react seo',
  title: 'React SEO Best Practices',
  metaDescription: 'Learn React SEO for faster indexing.',
  content: bodyHtml,
  slug: 'react-seo',
  images: [{ alt: 'React SEO diagram' }],
});
// { inTitle: true, inH1: false, inFirstParagraph: true, inHeadings: 2,
//   inContent: 4, inSlug: true, inAltText: 1, density: 1.8, totalWords: 450 }
How do I get word, sentence, and syllable counts from HTML?
getTextStatistics() strips HTML with a ReDoS-free scanner, then returns a TextStatistics object with counts and derived averages. It underpins readability scoring in @power-seo/readability and content checks in @power-seo/content-analysis.
import { getTextStatistics, stripHtml, getWords, getSentences } from '@power-seo/core';

const stats = getTextStatistics('<h1>Hello</h1><p>This is a test sentence. And another one.</p>');
// {
//   wordCount, sentenceCount, paragraphCount, syllableCount, characterCount,
//   avgWordsPerSentence, avgSyllablesPerWord
// }

stripHtml('<p>Clean <strong>text</strong>.</p>'); // => "Clean text."
getWords('one two three'); // => ['one', 'two', 'three']
getSentences('First. Second. Third.'); // => ['First.', 'Second.', 'Third.']
How do I generate and parse robots meta directives?
buildRobotsContent() serializes a RobotsDirective to a comma-separated content string; parseRobotsContent() reverses it. Both handle index/follow, noarchive, nosnippet, noimageindex, notranslate, maxSnippet, maxImagePreview, maxVideoPreview, and unavailableAfter.
import { buildRobotsContent, parseRobotsContent } from '@power-seo/core';

buildRobotsContent({ index: false, follow: true, maxSnippet: 150, maxImagePreview: 'large' });
// => "noindex, follow, max-snippet:150, max-image-preview:large"

parseRobotsContent('noindex, follow, max-snippet:150');
// => { index: false, follow: true, maxSnippet: 150 }
How do I apply a site-wide title template?
createTitleTemplate() returns a reusable factory pre-configured with your site name and separator; the default template is '%title% %separator% %siteName%' and the default separator is '|'. applyTitleTemplate() runs a one-off %variable% substitution and trims dangling separators.
import { createTitleTemplate, applyTitleTemplate } from '@power-seo/core';

const makeTitle = createTitleTemplate({ siteName: 'My Site', separator: '—' });
makeTitle('About Us'); // => "About Us — My Site"
makeTitle('Contact', { separator: '|' }); // => "Contact | My Site"

applyTitleTemplate('%title% | %siteName% — Page %page%', {
  title: 'Blog',
  siteName: 'My Site',
  page: 2,
});
// => "Blog | My Site — Page 2"
How do I rate-limit outbound API calls?
createTokenBucket(requestsPerMinute) builds a token bucket that refills continuously. Call consumeToken() before each request; if it returns false, getWaitTime() tells you how many milliseconds to sleep() before retrying. calculateBackoff(attempt) gives exponential backoff (base 1000ms, capped at 30000ms).
import { createTokenBucket, consumeToken, getWaitTime, sleep } from '@power-seo/core';

const bucket = createTokenBucket(60); // 60 requests per minute

async function callApi() {
  while (!consumeToken(bucket)) {
    await sleep(getWaitTime(bucket));
  }
  // make your rate-limited request here
}
How do I gate a CI build on content quality?
Combine getTextStatistics() and calculateKeywordDensity() with the exported MIN_WORD_COUNT and KEYWORD_DENSITY constants to fail a pipeline on thin content or off-target density.
import {
  getTextStatistics,
  calculateKeywordDensity,
  MIN_WORD_COUNT,
  KEYWORD_DENSITY,
} from '@power-seo/core';

const stats = getTextStatistics(bodyHtml);
const { density } = calculateKeywordDensity(keyphrase, bodyHtml);

if (stats.wordCount < MIN_WORD_COUNT) {
  console.error(`Word count too low: ${stats.wordCount} (minimum ${MIN_WORD_COUNT})`);
  process.exit(1);
}

if (density < KEYWORD_DENSITY.MIN || density > KEYWORD_DENSITY.MAX) {
  console.error(
    `Keyword density out of range: ${density}% (target ${KEYWORD_DENSITY.MIN}–${KEYWORD_DENSITY.MAX}%)`,
  );
  process.exit(1);
}
API Reference
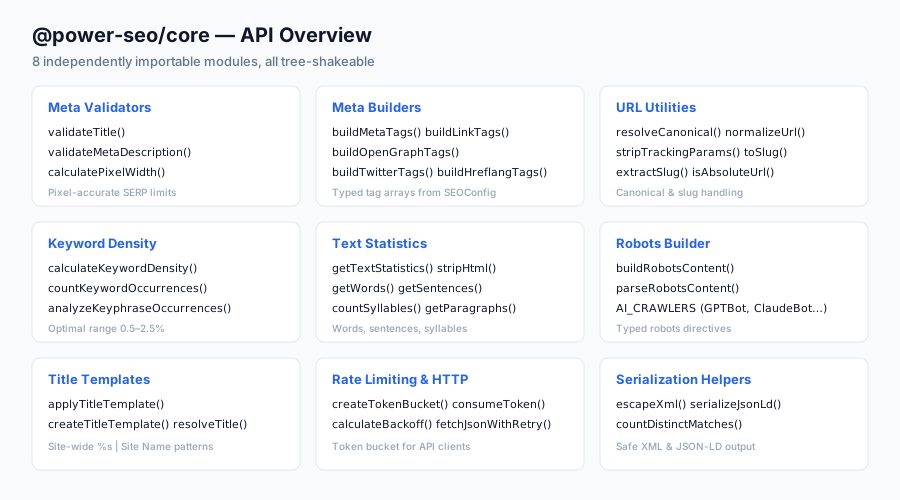
Meta Builder Functions
| Function | Signature | Description |
| ------------------------------- | ------------------------------------ | ------------------------------------------------------------------------- |
| buildMetaTags(config) | (SEOConfig) => MetaTag[] | Build meta tags; OG/Twitter inherit top-level title/description/canonical |
| buildLinkTags(config) | (SEOConfig) => LinkTag[] | Build canonical and hreflang link tags |
| buildOpenGraphTags(og) | (OpenGraphConfig) => MetaTag[] | Build Open Graph meta tags |
| buildTwitterTags(twitter) | (TwitterCardConfig) => MetaTag[] | Build Twitter Card meta tags |
| buildHreflangTags(alternates) | (HreflangConfig[]) => LinkTag[] | Build rel="alternate" hreflang link tags |
| resolveTitle(config) | (SEOConfig) => string \| undefined | Resolve final title, applying titleTemplate (%s) if present |
Meta Validator Functions
| Function | Signature | Description |
| ------------------------------- | ------------------------------ | ------------------------------------------------------- |
| validateTitle(title) | (string) => ValidationResult | Validate title char count and pixel width against 580px |
| validateMetaDescription(desc) | (string) => ValidationResult | Validate meta description against 920px |
| calculatePixelWidth(text) | (string) => number | Sum Arial per-character widths for SERP measurement |
URL Utility Functions
| Function | Signature | Description |
| ------------------------------- | ------------------------------- | ------------------------------------------------------ |
| resolveCanonical(base, path?) | (string, string?) => string | Resolve and normalize a canonical URL |
| normalizeUrl(url) | (string) => string | Drop default ports, collapse //, trim trailing slash |
| ensureTrailingSlash(url) | (string) => string | Add trailing slash to non-file URLs |
| removeTrailingSlash(url) | (string) => string | Strip trailing slash (except root) |
| stripQueryParams(url, keep?) | (string, string[]?) => string | Remove all or all-but-keep query params |
| stripTrackingParams(url) | (string) => string | Remove UTM, fbclid, gclid, and 15+ other trackers |
| extractSlug(url) | (string) => string | Return the last non-empty path segment |
| isAbsoluteUrl(url) | (string) => boolean | Test for http:// or https:// prefix |
| toSlug(text) | (string) => string | Lowercase, de-accent, hyphenate to a URL-safe slug |
Text Statistics Functions
| Function | Signature | Description |
| ---------------------------- | ---------------------------- | ----------------------------------------------------------- |
| getTextStatistics(content) | (string) => TextStatistics | Full stats — words, sentences, paragraphs, syllables, chars |
| stripHtml(html) | (string) => string | ReDoS-free HTML strip with entity decode |
| getWords(text) | (string) => string[] | Split plain text into words |
| getSentences(text) | (string) => string[] | Split into sentences on boundary punctuation |
| getParagraphs(html) | (string) => string[] | Extract paragraph blocks |
| countSyllables(word) | (string) => number | Heuristic English syllable count for one word |
| countTotalSyllables(text) | (string) => number | Sum syllables across all words |
Keyword Density Functions
| Function | Signature | Description |
| ------------------------------------------- | ------------------------------------------ | --------------------------------------------------- |
| calculateKeywordDensity(keyword, content) | (string, string) => KeywordDensityResult | Occurrence count, density %, total words |
| countKeywordOccurrences(text, keyword) | (string, string) => number | Word-boundary, case-insensitive count |
| analyzeKeyphraseOccurrences(config) | (object) => KeyphraseOccurrences | Placement map — title, H1, headings, slug, alt text |
Robots, Title Template & Rate Limiting
| Function | Signature | Description |
| -------------------------------------------- | --------------------------------------------- | ------------------------------------------------------- |
| buildRobotsContent(directive) | (RobotsDirective) => string | Serialize directives to a robots content string |
| parseRobotsContent(content) | (string) => RobotsDirective | Parse a robots content string to a directive |
| applyTitleTemplate(template, vars) | (string, TitleTemplateVars) => string | Apply %variable% substitution |
| createTitleTemplate(defaults) | (defaults) => (title, overrides?) => string | Build a reusable title factory |
| createTokenBucket(rpm) | (number) => TokenBucket | Create a token bucket at N requests/minute |
| consumeToken(bucket) | (TokenBucket) => boolean | Consume one token; true if allowed |
| getWaitTime(bucket) | (TokenBucket) => number | Milliseconds until the next token is available |
| sleep(ms) | (number) => Promise<void> | Promise-based delay |
| calculateBackoff(attempt, baseMs?, maxMs?) | (number, number?, number?) => number | Exponential backoff, defaults 1000ms base / 30000ms cap |
Constants
| Constant | Value | Description |
| ----------------------------- | -------------------------------------------------------- | -------------------------------------------------------- |
| TITLE_MAX_PIXELS | 580 | Google SERP max title display width (pixels) |
| TITLE_MAX_LENGTH | 60 | Recommended max title character length |
| TITLE_MIN_LENGTH | 50 | Recommended min title character length |
| META_DESCRIPTION_MAX_PIXELS | 920 | Google SERP max meta description width (pixels, desktop) |
| META_DESCRIPTION_MAX_LENGTH | 160 | Recommended max meta description length |
| META_DESCRIPTION_MIN_LENGTH | 120 | Recommended min meta description length |
| MIN_WORD_COUNT | 300 | Minimum word count to avoid thin content |
| RECOMMENDED_WORD_COUNT | 1000 | Recommended word count for long-form posts |
| MAX_URL_LENGTH | 75 | Maximum recommended URL length for SEO |
| KEYWORD_DENSITY | { MIN: 0.5, MAX: 2.5, OPTIMAL: 1.5 } | Keyword density range (percent) |
| READABILITY | { FLESCH_EASE_GOOD: 60, MAX_SENTENCE_LENGTH: 20, ... } | Readability scoring thresholds |
| OG_IMAGE | { WIDTH: 1200, HEIGHT: 630, ASPECT_RATIO: 1.91, ... } | Open Graph recommended image dimensions |
| TWITTER_IMAGE | { SUMMARY: {144×144}, SUMMARY_LARGE: {800×418} } | Twitter Card recommended image dimensions |
| AI_CRAWLERS | ['GPTBot', 'ClaudeBot', 'CCBot', ...] | Known AI crawler user agents |
| SCHEMA_TYPES | ['Article', 'Product', 'FAQPage', ...] | Common Schema.org types used in SEO |
Types
| Type | Shape / Notes |
| ---------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------- |
| SEOConfig | { title?, titleTemplate?, description?, canonical?, noindex?, nofollow?, robots?, openGraph?, twitter?, languageAlternates?, ... } |
| MetaTag | { name?, property?, httpEquiv?, content } |
| LinkTag | { rel, href, hreflang?, type?, sizes?, media? } |
| OpenGraphConfig | OG config with type, images, videos, article, profile |
| OpenGraphType | 'website' \| 'article' \| 'book' \| 'profile' \| 'product' \| 'video.movie' \| ... |
| OpenGraphImage | { url, secureUrl?, type?, width?, height?, alt? } |
| TwitterCardConfig | Card cardType, site, creator, image, player and app fields |
| TwitterCardType | 'summary' \| 'summary_large_image' \| 'app' \| 'player' |
| RobotsDirective | { index?, follow?, noarchive?, nosnippet?, noimageindex?, notranslate?, maxSnippet?, maxImagePreview?, maxVideoPreview?, unavailableAfter? } |
| HreflangConfig | { hrefLang, href } |
| ValidationResult | { valid, severity, message, charCount?, pixelWidth? } |
| ValidationSeverity | 'error' \| 'warning' \| 'info' |
| KeywordDensityResult | { keyword, count, density, totalWords } |
| KeyphraseOccurrences | { inTitle, inMetaDescription, inFirstParagraph, inH1, inHeadings, inContent, inSlug, inAltText, density, totalWords } |
| TextStatistics | { wordCount, sentenceCount, paragraphCount, syllableCount, characterCount, avgWordsPerSentence, avgSyllablesPerWord } |
| TitleTemplateVars | { title?, siteName?, separator?, tagline?, page?, [key]: string \| number } |
| TokenBucket | { tokens, lastRefill, maxTokens, refillRate } |
| ContentAnalysisInput | Input for content analysis — title, meta, content, focusKeyphrase |
| AnalysisStatus | 'good' \| 'ok' \| 'poor' \| 'na' |
| SitemapURL | { loc, lastmod?, changefreq?, priority?, images?, videos?, news? } |
| RedirectRule | { source, destination, statusCode, isRegex? } |
| SchemaBase | { '@context'?, '@type', '@id'?, [key]: unknown } |
The full list of exported types is available via import type { ... } from '@power-seo/core' — see src/types.ts.
Use Cases
- @power-seo packages — every other
@power-seopackage consumes core's shared types, constants, and utilities - Custom SEO tooling — build bespoke SEO features on typed primitives instead of hand-rolling regex and string math
- Next.js / Remix apps — call
buildMetaTags()andbuildLinkTags()server-side in route handlers or layouts - Content editors — validate SERP title and meta-description pixel widths before publishing
- CI content quality gates — enforce word count and keyword density with
getTextStatistics()and the exported constants - eCommerce — validate product titles, descriptions, and slug quality at scale
- Rate-limited integrations — use the token bucket to respect Google Search Console, Semrush, or Ahrefs API limits
- Headless CMS plugins — surface Yoast-style keyphrase feedback with
analyzeKeyphraseOccurrences()
Architecture Overview
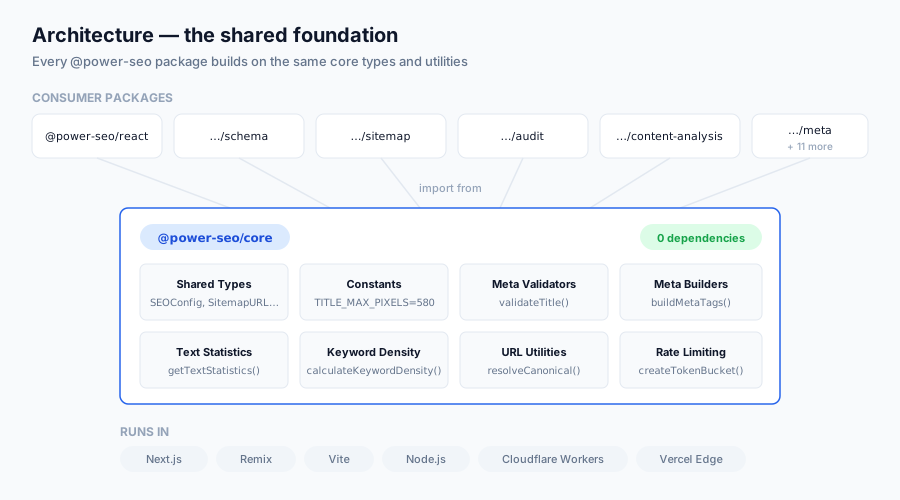
- Pure TypeScript — no compiled binaries or native modules
- Zero runtime dependencies — ships clean with nothing else to install
- Framework-agnostic — no assumptions about React, Vue, or any UI framework
- SSR compatible — safe in Next.js Server Components, Remix loaders, and Express handlers
- Edge-runtime safe — no Node-specific globals beyond
URL/setTimeout; runs on Cloudflare Workers and Vercel Edge - ReDoS-free —
stripHtml(), heading extraction, and URL trimming avoid catastrophic-backtracking regex on user input - Tree-shakeable —
"sideEffects": falsewith per-module named exports - Dual ESM + CJS — both formats shipped via tsup for any bundler or
require()

Supply Chain Security
- Published to npm with provenance attestation — every release is built and signed by the verified
github.com/CyberCraftBD/power-seoGitHub Actions workflow, so you can trace each tarball back to its exact source commit - Zero third-party runtime dependencies — packages depend only on other
@power-seopackages, nothing else gets pulled in - No network access at runtime — pure computation on the inputs you pass; nothing is fetched, phoned home, or telemetered
- No install scripts (
postinstall,preinstall) - No
evalor dynamic code execution - Safe for SSR, Edge, and server environments
The @power-seo Ecosystem
All 17 packages are independently installable — use only what you need.
| Package | Install | Description |
| ------------------------------------------------------------------------------------------ | ----------------------------------- | ---------------------------------------------------------------------------------- |
| @power-seo/ai | npm i @power-seo/ai | LLM-agnostic prompt templates and response parsers for AI-assisted SEO |
| @power-seo/analytics | npm i @power-seo/analytics | Merge Search Console data with audit results — trends and ranking insights |
| @power-seo/audit | npm i @power-seo/audit | SEO site health auditing with meta, content, structure, and performance rules |
| @power-seo/content-analysis | npm i @power-seo/content-analysis | Yoast-style SEO content analysis engine with scoring, checks, and React components |
| @power-seo/core | npm i @power-seo/core | Framework-agnostic SEO analysis engines, types, validators, and utilities |
| @power-seo/images | npm i @power-seo/images | Image SEO analysis — alt text quality, lazy loading, formats, image sitemaps |
| @power-seo/integrations | npm i @power-seo/integrations | Semrush and Ahrefs API clients with a shared rate-limited HTTP client |
| @power-seo/links | npm i @power-seo/links | Internal link graph analysis — orphan detection, suggestions, equity scoring |
| @power-seo/meta | npm i @power-seo/meta | SSR meta tag helpers for Next.js App Router, Remix v2, and generic SSR |
| @power-seo/preview | npm i @power-seo/preview | SERP, Open Graph, and Twitter Card preview generators with React components |
| @power-seo/react | npm i @power-seo/react | React SEO components — meta tags, Open Graph, Twitter Card, breadcrumbs |
| @power-seo/readability | npm i @power-seo/readability | Readability scoring — Flesch-Kincaid, Gunning Fog, Coleman-Liau, ARI |
| @power-seo/redirects | npm i @power-seo/redirects | Redirect rule engine with Next.js, Remix, and Express adapters |
| @power-seo/schema | npm i @power-seo/schema | Type-safe JSON-LD structured data — 23 schema.org builders plus React components |
| @power-seo/search-console | npm i @power-seo/search-console | Google Search Console API client — OAuth2, service accounts, rate limiting, retry |
| @power-seo/sitemap | npm i @power-seo/sitemap | XML sitemap generation, streaming, and validation with image, video, news support |
| @power-seo/tracking | npm i @power-seo/tracking | Analytics script builders with consent management and React components |
Keywords
seo, meta tags, open graph, twitter card, canonical url, hreflang, robots directives, keyword density, url normalization, text statistics, title validator, pixel width, meta builder, framework-agnostic, typescript, zero-dependency, tree-shakeable, nextjs, remix, edge runtime
About CyberCraft Bangladesh
CyberCraft Bangladesh is a Bangladesh-based enterprise-grade software development and Full Stack SEO service provider company specializing in ERP system development, AI-powered SaaS and business applications, full-stack SEO services, custom website development, and scalable eCommerce platforms. We design and develop intelligent, automation-driven SaaS and enterprise solutions that help startups, SMEs, NGOs, educational institutes, and large organizations streamline operations, enhance digital visibility, and accelerate growth through modern cloud-native technologies.
© 2026 CyberCraft Bangladesh · Released under the MIT License