
@shidesheng0218/agentguard
v1.8.0
Published
Runtime behavior guard for coding agents (Kimi Code CLI & Claude Code): loop detection, quota gates, checkpoint/resume, supervised Wire runs

Maintainers
 shidesheng0218
Readme
🛡️ agent-guard (formerly kimi-guard)
A runtime behavior guard for coding agents — Kimi Code CLI, Claude Code and Codex CLI — stop runaway agent loops before they burn your quota.
npm i -g @shidesheng0218/agentguard && agentguard install → done. (Existing users: your installed kimi-guard keeps working — its kguard bin and hook entries stay live.)


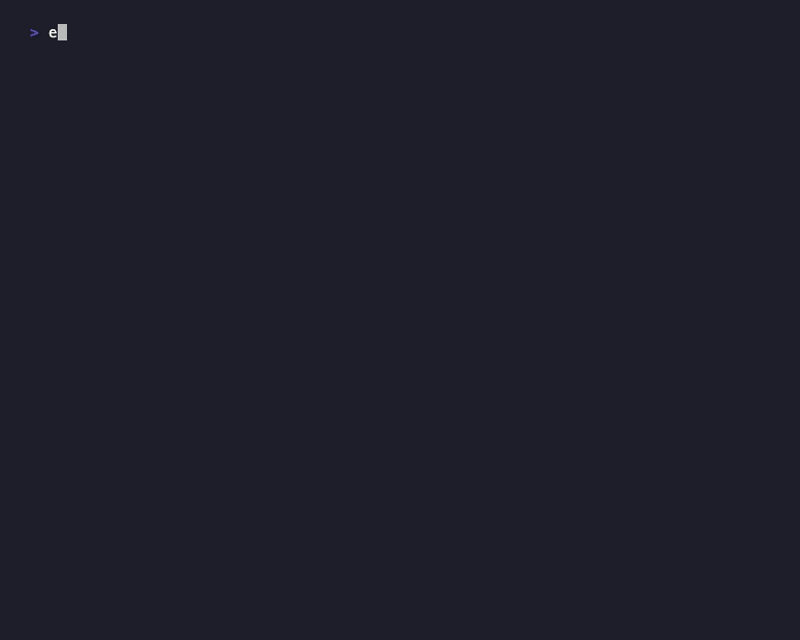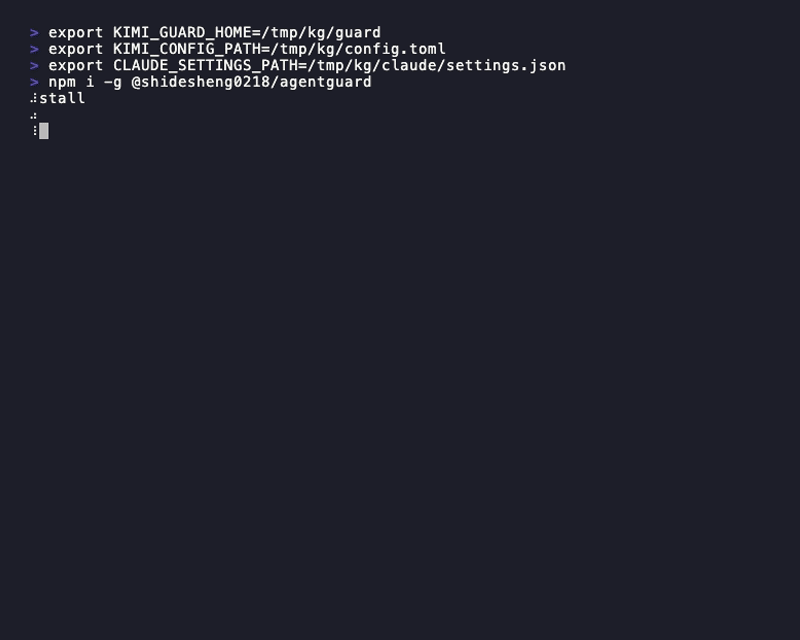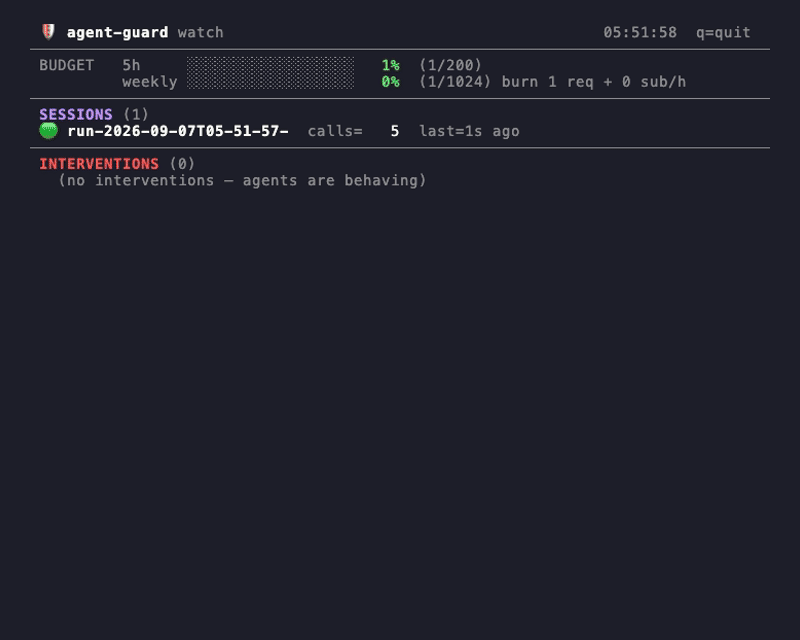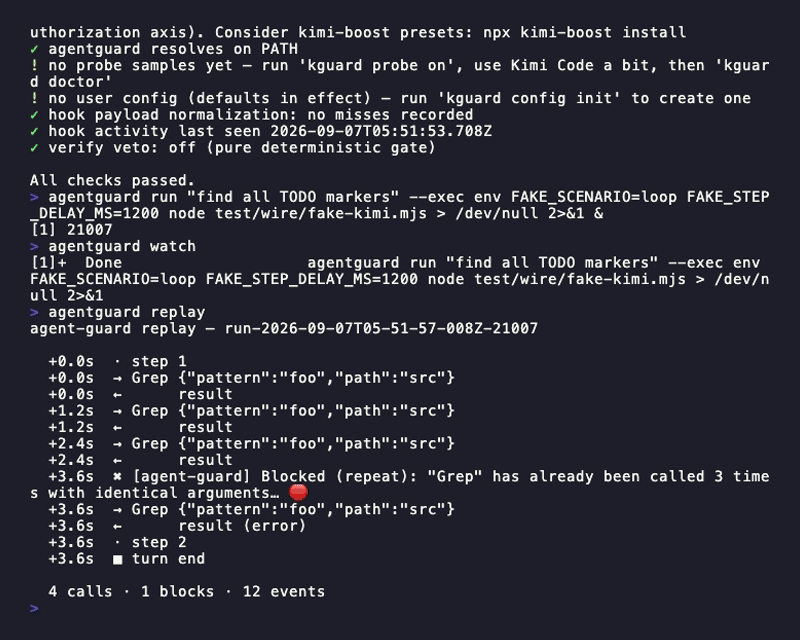
Real terminal session: install → verify → a supervised run where the circuit breaker catches a looping tool call → live status & budget panels. Recorded with vhs from actual commands (demo.tape).
Why
Kimi Code CLI is a great open-source coding agent, but its subagent system has known reliability gaps (see issues #2142, #2368, #2578):
- The model repeats the exact same tool call dozens of times (76×, 112× observed in the wild), silently burning tokens — fatal for headless/CI runs where nobody presses Ctrl+C.
- All subagents share one API key, so a burst of parallel dispatches exhausts TPM/RPM and everything hangs.
- A mid-batch quota error leaves half-written workspaces that poison the whole run.
agent-guard is a local, zero-daemon guard that sits on the CLI's official hooks system and enforces hard caps — no source forking, no proxy, no account access.
Since v0.8 the same engine also guards Claude Code via its hooks system (agentguard install auto-detects installed harnesses). Wire-mode supervision (agentguard run), mid-turn steering and official-API quota metering remain Kimi-exclusive; loop/churn/explore detection, quota gates, the completion gate, kill switch and checkpoints work on both.
Features
agent-guard is not a preset pack — it is a runtime behavior analysis and enforcement engine. Every tool call flows through a normalization layer, a set of pure analyzers, and a policy engine that maps findings to actions (observe / warn / block / full stop).
| Guard | Signal it detects | Action |
|---|---|---|
| 🔁 Repetition | same (tool, args) signature re-run N times (whitespace-tolerant fingerprinting) | block |
| 🔄 Cycle detection | oscillating loops: A→B→A→B… up to period-3, regardless of tool | block |
| 📉 No-information-gain | different arguments, byte-identical output — the model is spinning without new data (the real root cause of upstream #2142 Case B). Fuzzy variant catches near-identical outputs (trigram similarity) | warn → block |
| ✏️ Edit churn | the same file edited over and over without converging ("thrashing") | warn → block |
| 🐢 No-progress stretch | long run of tool calls with no successful edit landing — motion without progress | warn → block |
| 🔭 Exploration drift | long streak of read/search calls with no action in between — exploring without implementing | warn → block |
| 🎯 Goal anchor | re-injects the original task verbatim every N prompts/steps and always after compaction — the two moments a long session drifts off-target | context injection |
| 🚦 Quota gate | request accounting against Kimi Coding Plan windows (5h/weekly) with burn-rate projection; dispatches are blocked before the window is exhausted | warn → block |
| 🔌 Kill switch | after N interventions in a session, block ALL tools and order the model to summarize and end its turn — the fuse for unattended/CI runs | full stop |
| 🧯 Context-fill gate | when the context window crosses the threshold (Wire mode reads StatusUpdate.context_usage), steers a wrap-up warning before compaction hits | mid-turn steer |
| 🧾 Completion gate | deterministic claim-vs-evidence check: "tests pass" claims are matched against the locally recorded command history — an unbacked claim triggers a corrective round (Wire) or blocks the turn end (hooks, opt-in). Optionally an LLM veto vote (self-critic style: the LLM only votes to suppress false positives, never authors a critique) | verify round / block / veto |
| 🧠 Thinking dominance | flags turns that burned ≥20k chars of pure reasoning with ≤10% visible action — fed back as "act more, think less" on the next resume | flag + resume note |
| 🔁 Near-duplicate matching | fuzzy loop detection: arguments differing only in punctuation, case, spacing or order still collapse to one signature | warn → block |
| 💾 Checkpoint / resume | auto-captures an observed "research state" brief (files touched, commands, searches, failed calls) on failure/interrupt/session-end; kguard resume prints a paste-ready context block so a resumed session skips re-exploration | recovery |
| 🎮 kguard run (Wire supervisor) | spawns the agent in Wire mode (JSON-RPC) and supervises it in-process: hook decisions with zero exit-code overhead, mid-turn steering on warn findings, exact per-step token metering from StatusUpdate, retry observability (StepRetry status codes), approval policy for headless runs, hard step/time caps with cancel, auto-resume with checkpoint injection, and a full run report + raw wire log | CI / unattended runs |
Warn-level findings are injected into the model's context (official hooks stdout mechanism) so the agent can correct itself before a block becomes necessary. Blocks feed a structured reason back to the model (official exit-code-2 mechanism).
Everything is fail-open: if agent-guard itself errors, the agent keeps working. It is a safety net, not a single point of failure.
Install
npm i -g @shidesheng0218/agentguard
agentguard install    # writes managed hooks into every detected harness
                      # (Kimi Code: ~/.kimi-code/config.toml · Claude Code: ~/.claude/settings.json)
agentguard canary     # proof-of-life: shows the guard blocking a synthetic repeat, live
agentguard doctor     # verify
canary fires 3 identical calls + 1 proposed repeat through the real hook path (same binary the
agent CLI invokes) and shows the 4th being blocked with the exact reason the model receives — then purges
its synthetic traffic, so your intervention stats stay honest. If it doesn't block, hooks aren't wired
(doctor tells you why).
Requires Node >= 22.13. Restart the agent CLI (or /reload) after installing.
Claude Code users can also install via the plugin channel (this repo is a self-hosted marketplace):
/plugin marketplace add shidesheng0218/kimi-guard
/plugin install agent-guard@agentguard
(The plugin's hooks call the agentguard CLI — install it globally first; without it the hooks fail-open.)
Harness support
| Capability | Kimi Code CLI | Claude Code | Codex CLI | Gemini CLI |
|---|---|---|---|---|
| Loop / churn / explore detection, kill switch | ✅ hooks | ✅ hooks | ✅ hooks (shell + apply_patch; hosted tools like WebSearch are not observable) | ✅ hooks |
| Quota gates | ✅ event-based + official-API precise ([budget] precise) | ✅ event-based estimates | ✅ event-based estimates | ✅ event-based estimates |
| Completion gate (claim vs evidence) | ✅ | ✅ | ✅ | ✅ |
| Checkpoints / resume, feedback loop, reports | ✅ | ✅ | ✅ | ✅ |
| agentguard run supervised headless runs | ✅ Wire protocol | ✅ stream-json supervision | ✅ exec JSON supervision | — |
| Mid-turn steer, exact per-step token metering | ✅ | — | — | — |
Kimi Code (~/.kimi-code/config.toml):
# >>> kimi-guard managed >>> DO NOT EDIT
[[hooks]]
event = "PreToolUse"
command = "agentguard hook PreToolUse"
timeout = 5

[[hooks]]
event = "PostToolUse"
command = "agentguard hook PostToolUse"
timeout = 5

[[hooks]]
event = "PostToolUseFailure"
command = "agentguard hook PostToolUseFailure"
timeout = 5

# + observation hooks: TurnStarted, SubagentStart, StopFailure, Interrupt, SessionEnd
# (these feed the budget metering and auto-checkpointing engines)
# <<< kimi-guard <<<
Claude Code (~/.claude/settings.json):
{
  "hooks": {
    "PreToolUse": [
      { "matcher": "", "hooks": [{ "type": "command", "command": "agentguard hook PreToolUse --harness claude", "timeout": 5 }] }
    ]
  }
}
(+ PostToolUse, PostToolUseFailure, UserPromptSubmit, Stop, SubagentStart, SessionStart/End, PreCompact/PostCompact, StopFailure — the events the guard handles.)
- Analyzers decide which tools to watch internally — the hooks observe everything, so the watch lists stay configurable without reinstalling.
- A backup is created before the first install (
config.toml.kimi-guard.bak/settings.json.agentguard.bak).agentguard uninstallremoves the entries cleanly from both harnesses. The Kimi block coexists with other tools' managed blocks (e.g. kimi-boost). - Legacy compatibility: if your CLI version rejects unknown hook events (older kimi-cli builds), run
agentguard install --compatto write only the 3 universally supported events. You keep loop guarding; you lose auto-checkpointing and event-based metering.
Commands
# binary is `agentguard`; `kguard` / `kimi-guard` remain as aliases — all commands work with either name
kguard install          # add hook rules to detected agent CLIs (idempotent)
kguard uninstall        # remove the managed hook block
kguard status           # calls, interventions, sessions, budget windows + intervention quality
kguard budget           # quota metering snapshot: windows, burn rate, projection
kguard blocks [-n N]    # recent blocks with ids + the exact reason each fired
agentguard canary       # proof-of-life: shows the guard blocking a synthetic repeat, live
agentguard blocks --kind/--session/--fp  # filter the blocks list
agentguard digest --md <file>  # shareable markdown digest
kguard feedback fp|tp <id>  # mark a block false-positive / confirmed — calibrates detectors
kguard report [--json] [--sessions]  # anonymized aggregate (+ cross-session patterns)
agentguard calibrate    # suggest threshold tweaks from your feedback (prints TOML)
kguard checkpoint       # capture a research-state checkpoint now
kguard resume           # print a paste-ready context block from the latest checkpoint
kguard run -- <prompt>  # supervised headless run in Wire mode (see below)
kguard doctor           # verify node/state db/config/PATH/probe
kguard probe on|off|show [−n N]   # capture raw hook payloads
kguard config init|show|get <key> # manage ~/.kimi-guard/config.toml
kguard hook <event>     # (used by the CLI, reads JSON from stdin)
agentguard watch        # live TUI: sessions, interventions and budget across all harnesses
agentguard replay [run] # annotated timeline of a recorded run (blocks highlighted)
agentguard bench        # public benchmark: scripted pathological agents vs the guard, scored
agentguard run — supervised headless runs
This is the tool for CI, cron jobs and unattended agents — the exact scenario where a repeating tool call burns the full timeout (upstream issue #2142 was a headless run).
agentguard run "refactor the auth module and make tests pass" \
  --max-steps 100 --max-minutes 20 --auto-resume 1 --json

# Claude Code headless supervision (stream-json driver):
agentguard run "migrate the test suite to vitest" --harness claude --max-steps 50
What the supervisor does (Kimi, Wire protocol — in-process, no exit codes):
- subscribes to
PreToolUseover the Wire protocol and returnsallow/blockdecisions — the same analyzers, zero-latency - steers the agent mid-turn (
steer) when a warn-level pattern appears, before a hard block is needed - meters exact token usage per step from
StatusUpdate.token_usage - observes retry storms (
StepRetrywith status codes → 429 visibility) - enforces hard caps:
--max-steps(cancel via officialcancelmethod),--max-minutes - kill switch: after N blocks it cancels the turn and checkpoints
- approval policy: default rejects with feedback (headless-safe),
--yoloapproves - writes a run report (
report.json) + raw wire log (wire.jsonl) under~/.agent-guard/runs/ - exit code 0 on clean finish, 2 on any intervention-triggered end — CI-friendly
The Claude driver (--harness claude) spawns claude -p --output-format stream-json and supervises the
event stream: same analyzers and state db (shared with the installed hooks, which do the actual blocking),
hard caps via --max-turns + wall clock, kill switch (SIGINT → SIGKILL), verify rounds and auto-resume
via --resume, exact token metering from result.usage. Mid-turn steer is not available (the stream is
read-only) — blocks still reach the model through the installed hooks in real time.
agentguard watch — live dashboard
A zero-dependency TUI over the local state db: all agent sessions across harnesses, the interventions
feed (blocks light up red as they land), and the quota windows with burn rate. q to quit.

agentguard replay — annotated run timeline
Every supervised run writes a raw log; agentguard replay renders it as a timeline with blocks marked
🔴 — the post-mortem of a runaway run, screenshot-ready.
agentguard bench — the public benchmark
Scripted pathological scenarios (loop storm, no-gain spin, fake completion claims, thinking-dominated
turns, context pressure, step-cap) run against the guard and scored 0–100. Fixture mode is free and
deterministic; --harness claude drives a real CLI (observational). --save keeps scoreboards under
the guard home for a recurring leaderboard. Latest: 100/100 on fixture scenarios
(scoreboard) — the guard passes its own crash tests.
Notifications: desktop + webhook
Opt-in, zero-daemon. Two independent channels:
[notify]                # native notifications on interventions (osascript, fire-and-forget)
enabled = true
onBlock = true          # every block
onKillSwitch = true     # kill switch, with sound
webhookUrl = ""         # POST blocks/kill-switch/digest as JSON — works headless (CI, servers, containers)
The webhook channel is for headless environments where no desktop exists. Each event is a single POST with a 3s timeout (fire-and-forget, never blocks the guard), payload shaped for Slack/Discord/飞书-style bridges:
{ "text": "🛡️ agent-guard — blocked repeat on Grep", "content": "…same as text…",
"event": "block", "kind": "repeat", "tool": "Grep", "session": "…", "ts": 1758300000000 }text/content carry the same string so both Slack-style and Discord-style endpoints accept it. Point it at a
Slack incoming webhook, a Discord webhook, or any tiny bridge.
agentguard digest --notify posts the weekly summary to the same URL.
And a menu-bar plugin for xbar/SwiftBar: agentguard menubar --install
writes a per-minute plugin that shows quota windows and the latest block; agentguard menubar prints the
plugin output directly (that's all the protocol is — a script that prints).
Making the value visible (retention by design)
agentguard digest— weekly summary: calls, interventions by detector, estimated requests saved (heuristic), quota windows, calibration hints.digest --notifyalso sends it as a desktop notification and webhook POST — schedule it from your own cron/launchd and the guard stays daemon-free.agentguard status/report --jsonshow the sameestSavedestimate so every block is a visible win.- Project config: a
.agentguard.tomlat your repo root overrides user config (defaults < profile < user < project) — team-shared rules checked into the repo.agentguard config init --projectscaffolds it. agentguard config export/import <file>— your tuned thresholds and exemptions become a portable, shareable asset (backup before every import).
Use in CI (GitHub Action)
- uses: shidesheng0218/kimi-guard@v0
  with:
    prompt: "refactor the auth module and make tests pass"
    harness: claude            # or kimi
    max-steps: 100
    max-minutes: 20
    profile: strict            # tighter thresholds for unattended runs
  env:
    ANTHROPIC_API_KEY: ${{ secrets.ANTHROPIC_API_KEY }}
The step fails (exit 2) when the guard intervened, and the job summary shows a full report: end reason, blocks by detector, token usage. Individual blocks also appear as PR annotations.
Threshold profiles
profile = "balanced" | "strict" | "chill" in config.toml (or --profile per run, or AGENT_GUARD_PROFILE):
balanced is the shipped default; strict intervenes earlier (headless/CI); chill is maximally hands-off.
Your own config keys always override the profile. agentguard calibrate suggests per-detector tweaks from
your false-positive feedback — it prints TOML, it never edits your config. Hit a false positive anyway?
Report it — one paste
from agentguard blocks is all we need; these reports calibrate the public defaults.
Configuration
~/.kimi-guard/config.toml (see kguard config init; full annotated template included):
[tools]                 # canonical tool-name taxonomy — if your CLI renames tools, fix it HERE
edit = ["WriteFile", "StrReplaceFile", "Edit", "Write", "MultiEdit", "NotebookEdit"]
read = ["ReadFile", "Read"]
search = ["Grep", "Glob"]
shell = ["Shell", "Bash"]     # verify evidence + veto context read this (legacy [verify] shellTools still works)

[repeat]                # exact/near-duplicate repetition
maxRepeats = 3
warnAt = 2              # soft context warning before the hard block
windowMinutes = 30
# exemptPatterns = [...] # regexes over JSON-serialized args; matching calls are never repeat-blocked (polling commands)

[cycle]                 # A->B->A->B oscillation detection
enabled = true

[noGain]                # different args, identical output
warnAt = 3
blockAt = 4

[churn]                 # same-file edit thrashing
warnAt = 5
blockAt = 10

[noProgress]            # long stretch of calls with no landed edit
warnAt = 15
blockAt = 25

[anchor]                # goal anchoring (anti-drift)
everyNPrompts = 5
maxChars = 1000

[context]
warnPercent = 85        # steer a wrap-up warning when the context is this full

[nearRepeat]            # fuzzy near-duplicates (punctuation/case/order differences)
warnAt = 6
blockAt = 10

[explore]               # pure-exploration streak: reads/searches with no action in between
warnAt = 10
blockAt = 15

[verify]                # completion-claim gate
enabled = true
blockOnNoEvidence = false  # hooks path: block Stop when edits landed but nothing was verified
evidenceWindowMinutes = 60

[verify.veto]           # optional false-positive suppression vote (off by default, zero deps when off)
enabled = false         # requires KIMI_GUARD_VETO_API_KEY in the environment (any OpenAI-compatible endpoint)
model = "kimi-k3"       # use a cheap fast model — the vote costs a few hundred tokens
maxCallsPerSession = 3  # the model cannot retry its way out of the gate

[thinking]              # thinking-dominance detection (Wire mode)
minThinkChars = 20000
maxTextRatio = 0.1

[policy]
killSwitch = true       # after maxBlocksPerSession interventions, block ALL tools
maxBlocksPerSession = 5

[budget]                # request accounting for Kimi Coding Plans
plan = "tier1"          # tier1: 1024/week | tier2: 2048 | tier3: 7168 (200 per 5h)
reservePercent = 10     # headroom the agent is never allowed to eat
subagentWeight = 5      # ~requests each dispatched subagent costs
precise = false         # poll the official Kimi usage API for exact windows (needs KIMI_API_KEY, sk-kimi-...)
                        # falls back to event-based estimates on any error — fail-open
How it works
flowchart LR
    subgraph KIMI["Kimi Code CLI"]
        A["tool call"] -->|"hook event / Wire msg"| B
    end
    subgraph GUARD["agent-guard"]
        B["Normalization layer<br/>schema-variant tolerant<br/>+ output hashing"] --> C["Analyzers (pure functions)<br/>repeat · cycle · no-gain · churn<br/>no-progress · near-repeat · explore"]
        M["Budget engine<br/>5h/weekly windows<br/>burn-rate projection"] --> C
        C --> D["Policy engine<br/>findings → action<br/>+ kill switch"]
    end
    D -->|"allow"| E["exit 0"]
    D -->|"warn"| F["context hint (stdout/steer)<br/>agent self-corrects first"]
    D -->|"block"| G["exit 2 / HookRequest<br/>reason fed back to model"]
    D -->|"kill"| H["cancel + checkpoint<br/>summarize and stop"]
The completion gate adds a claim-vs-evidence loop on top:
sequenceDiagram
    participant A as Agent
    participant G as agent-guard
    participant DB as local evidence (state.db)
    A->>A: runs tools (Shell, edits...)
    A->>G: turn ends, claims "all tests pass"
    G->>DB: any successful test/build/lint command?
    alt evidence found
        G->>A: accept ✅
    else no evidence
        opt LLM veto enabled (fail-closed, budget-capped)
            G->>G: one vote: VETO yes/no
        end
        G->>A: corrective round — "actually run verification"
    end
Kimi Code CLI ──hook event──▶ kguard hook <event> (JSON on stdin)
│
┌─────────────▼──────────────┐
│ normalization layer │ schema-variant tolerant payload
│ (src/events.ts) │ → canonical call record + output hash
└─────────────┬──────────────┘
┌─────────────▼──────────────┐
│ analyzers (pure functions) │ repetition · cycles · no-gain · churn
│ (src/analysis.ts) │ + budget gate (src/meter.ts)
└─────────────┬──────────────┘
┌─────────────▼──────────────┐
│ policy engine │ findings → allow / warn / block
│ (src/policy.ts) │ + kill switch
└─────────────┬──────────────┘
│
allow (exit 0) · warn (exit 0 + context hint) · block (exit 2 + reason)
│
~/.kimi-guard/state.db (SQLite via node:sqlite)
checkpoints/<session>/<ts>.mdPreToolUseexit 2 is the official blocking mechanism: the CLI feeds stderr back to the model as a correction.PreToolUsestdout on warn is appended to the model context — a soft nudge before a hard block.TurnStarted/SubagentStart/StopFailure/Interrupt/SessionEndhooks feed the metering and checkpoint engines.
Roadmap
- [ ] v0.7 — per-agent model routing (needs upstream
modelfield on subagent dispatch, #2533); git-worktree partial-work isolation for parallel agents - [x] exact plan-usage windows via the official Kimi usage API (v0.6.2,
[budget] precise = true; event-based estimates remain the fail-open fallback) - [ ] cross-harness adapters — see docs/PORTING.md for the reusable-core checklist
Ecosystem fit
The agent-runtime tooling space is crowded, and pretending every tool competes with every other one helps nobody. agent-guard occupies one specific layer — here is the honest map:
┌────────────────────────────────────────────────────────────────┐
│  your agent (Kimi Code CLI · Claude Code)                      │
│                                                                │
│  built-in loop_control      step/attempt caps + compaction     │
│  ├─ mechanical counter — stops the loop, explains nothing       │
│                                                                │
│  ┌──────────────────────────────────────────────────────────┐  │
│  │  agent-guard (this project) — the enforcement layer      │  │
│  │  semantic loop detection · quota gates · steering ·      │  │
│  │  checkpoints · goal anchoring — the agent cannot bypass  │  │
│  └──────────────────────────────────────────────────────────┘  │
│                                                                │
│  kimi-session-orchestrator  voluntary orchestration layer      │
│  ├─ MCP tools the AGENT chooses to call (grade_step, retire)   │
│  ├─ great when the agent cooperates; has no veto power         │
│                                                                │
│  kimi-boost                  security preset installer         │
│  ├─ dangerous-command guards, branch protection, skills       │
│  ├─ WHAT the agent may do (security) — different axis from    │
│  │  agent-guard's HOW it behaves (runtime loops/budget)       │
│                                                                │
│  cli-agent-runner            lifecycle supervisor              │
│  ├─ 7×24 restart loops, log-level anomaly detection           │
│  ├─ between-rounds layer — complements our within-round layer │
│                                                                │
│  ccusage / kimi-code-usage    read-only usage monitors         │
│  ├─ tell you what happened AFTER — never block anything       │
└────────────────────────────────────────────────────────────────┘
Three lines of positioning:
- Monitors are plentiful, voluntary orchestrators exist — but a non-bypassable enforcement layer, agent-guard is the first in the Kimi ecosystem. (ccusage-family tools are read-only; kimi-session-orchestrator relies on the agent choosing to call it; agent-guard intercepts.)
- Mid-turn steering is an intervention outside the hook-lifecycle boundary — no verified analog does it: external supervisors (e.g. loop-eng/loopguard) can only SIGSTOP-pause the process and post a desktop notification; in-process detector libraries (LoopBuster) need the host app to honor them; security-hook suites (cc-safety-net) act pre-execution only. We do it natively over the official Wire protocol.
- The budget model understands Kimi's subscription semantics: 5h/weekly request windows, reserved headroom, burn-rate projection — USD-billing competitors don't reconcile against plan-based users.
What we deliberately do NOT do (so you know where to look):
- Security scanning / destructive-command guards → use kimi-boost presets (different axis: authorization vs behavior).
kguard doctordetects whether a security layer is present and points you there if not. - Completion verification exists in agent-guard as a deterministic claim-vs-evidence gate (no LLM in the loop), with an opt-in single-vote LLM veto for false positives (
VETO: yes|noprotocol, per-session budget cap, fail-closed on any error). For richer semantic verification (refute-by-default judges, LLM grading), see kimi-session-orchestrator'sgrade_stepor the refute-by-default pattern in multi-runtime governance suites. - Multi-runtime portability: ✅ shipped for Claude Code (v0.8) and Codex CLI (v0.9) — see the harness matrix. Next adapters (Gemini etc.) reuse the pure-function analyzer core (PORTING.md)
- Daemon-style process supervision (SIGSTOP/SIGCONT, systemd) → cli-agent-runner owns that layer; ours is semantic in-harness intervention
Related Kimi-ecosystem projects worth knowing: kimi-session-orchestrator (multi-session orchestration), oh-my-kimi (skill/hook presets), cli-agent-runner (lifecycle supervision with a kimi preset), kimi-code-usage (read-only usage reporting). agent-guard and kimi-boost come from the same author and are designed as a pair: boost covers the authorization axis, guard the behavior axis.
The cross-ecosystem landscape (verified 2026-09)
The behavioral-enforcement niche is not just empty in the Kimi ecosystem — a survey of the wider coding-agent tooling space found no shipped equivalent:
| Tool | Mechanism | What it can/cannot do vs agent-guard | |---|---|---| | cc-safety-net (1.5k★, 13 CLIs incl. Kimi Code) | pre-execution hooks | Blocks dangerous commands/secret access — the authorization axis. No loop detection, no quotas, no steering. Proves multi-runtime hooks appetite. | | ccusage (18k★) | log analytics | Read-only cost/token reports over 18 agent CLIs. Never blocks. The usage-data layer is commoditized; enforcement is the open layer. | | LoopBuster (83★) | in-process library | Detector set nearly identical to ours (fuzzy repeat / cycles / output stagnation) — but inside LangGraph/CrewAI apps, not CLIs. Independent convergent evidence the detector taxonomy is right. | | loop-eng/loopguard (0★) | supervisor daemon (SIGSTOP) | Multi-runtime loop watching with $-caps, but freezes the process and posts a desktop notification — useless headless, no steering, no semantics. | | claudewatch (9★, stalled) | PostToolUse hooks + MCP | Closest prior art for hook-feedback steering ("you're looping, call get_blockers()") — Claude Code only, inactive since 2026-03. | | ralph (9.6k★) | shell wrapper loop | Exit gates and rate limits at iteration boundaries only — works around runaway agents by restarting, doesn't govern them. | | NeMo Guardrails / Guardrails AI / Langfuse / LangSmith / Helicone | content rails / SDK / proxy / SaaS | Structurally cannot intercept a local CLI's tool calls: proxies see only model HTTP traffic, content validators see text, observability is after-the-fact. |
The takeaway: monitors are commoditized, security hooks are crowded, orchestration is well-served — behavioral, semantic, mid-run enforcement of a local coding CLI is the layer nobody else ships. agent-guard's moat is the combination, not any single feature: hook/Wire access point × semantic detectors × subscription-aware budgeting — now running on two harnesses (Kimi Code + Claude Code), with the pure-function analyzer core (PORTING.md) ready for more.
Compatibility
- Kimi Code CLI hooks (Beta) and Claude Code hooks (33 events; we use the 11 the guard handles). Hook payloads are parsed defensively; run
agentguard probe on+agentguard doctorto see the exact fields your CLI version sends. - Config detection:
$KIMI_CONFIG_PATH→~/.kimi-code/config.toml→~/.kimi/config.toml; Claude:$CLAUDE_SETTINGS_PATH→~/.claude/settings.json. - Guard state dir:
$AGENT_GUARD_HOME→$KIMI_GUARD_HOME→~/.agent-guard(existing~/.kimi-guardkeeps working in place).
License
MIT