
@tscaps/engine
v0.5.1
Published
Burn subtitles into video in the browser. CSS-styled captions, frame-accurate export, no server.

Maintainers
 francozanardi
Readme
@tscaps/engine
A TypeScript engine that adds captions to a video and burns them in — all in the browser, no server involved. It sources captions (in-browser Whisper transcription, an existing .srt, or a hand-built Document), lays them out through CSS, and exports the result frame-by-frame to a new video.
Captions are HTML elements styled with CSS. On export, the engine rasterizes that DOM at each frame's timestamp into a bitmap and composites it with the video frame. The browser renders the captions.
See it running: tscaps.io/local is a full caption editor built on this engine, transcription and export included, running entirely in the browser with no account and no upload. It is the fastest way to see what the engine does before writing any code against it.
Install
npm install @tscaps/engineIf you use the built-in transcriber (WhisperTranscriber), you also need onnxruntime-web >= 1.27 as an override. See ONNX runtime version below.
The engine targets modern browsers (Chrome 94+, Edge 94+, Safari 16.4+, Firefox 130+). It requires WebCodecs for encoding and Canvas for rasterization. Audio decoding falls back to Web Audio on browsers that ship WebCodecs without an audio decoder (Safari before 26). Node >= 20 is needed only for development tooling; the engine itself does not run in Node.
ONNX runtime version
onnxruntime-web is a peer dependency. The engine's Whisper integration needs version 1.27+, but @huggingface/[email protected] pins version 1.26, which cannot open the current model files. You need to override it:
// package.json (npm "overrides" or yarn "resolutions")
"overrides": { "onnxruntime-web": "1.27.0" }
Without the override, transcription fails at model loading, after the full download. This is fixed in transformers.js v4.3.0 (#1707); the override can be removed after that.
If you do not use WhisperTranscriber (e.g. you only use SrtTranscriber or PassthroughTranscriber), you do not need onnxruntime-web at all.
Quick start
The minimum-viable consumer: feed a video in, get back a captioned Blob. With no transcriber supplied, the engine downloads a Whisper model on first run (~80MB, cached after) and transcribes the audio itself.
import { RenderPipelineBuilder } from '@tscaps/engine';

const inputVideo: Blob = /* from a file input, fetch, etc. */;

const pipeline = new RenderPipelineBuilder()
  .withInputVideo(inputVideo)
  .build();

const { blob } = await pipeline.run();
// `blob` is a Blob containing the captioned mp4
Examples
The examples below build on each other and share two fixtures so each variation is easy to compare side by side:
The clip — a short demo video the engine renders captions onto:
The SRT — caption text and cue timings used as input to SrtTranscriber throughout:
1
00:00:00,500 --> 00:00:02,500
Welcome to the engine.

2
00:00:02,500 --> 00:00:05,500
Captions burned in the browser.

3
00:00:05,500 --> 00:00:08,000
No server, no editor.
1. From an SRT file
Feed the engine a hand-authored .srt. SrtTranscriber parses cues into a Document and skips the Whisper model entirely. Default styling: bold white text, bottom-center, with a soft shadow.
import { RenderPipelineBuilder, SrtTranscriber } from '@tscaps/engine';

const srt = await (await fetch('/captions.srt')).text();

const pipeline = new RenderPipelineBuilder()
  .withInputVideo(inputVideo)
  .withTranscriber(new SrtTranscriber(srt))
  .build();

const { blob } = await pipeline.run();
2. Custom caption style
Hand the pipeline a CSS string. The default selectors are .segment, .line, and .word; the engine attaches those classes to the rendered DOM. Container units (cqh, cqw) scale sizes against the video frame. -webkit-text-stroke paired with paint-order: stroke fill paints the outline outside the glyph instead of bleeding into it.
const captionCss = `
  .segment {
    font-family: system-ui, -apple-system, sans-serif;
    font-weight: 800;
    font-size: 6cqh;
    color: #ffd400;
    -webkit-text-stroke: 0.06em #000;
    paint-order: stroke fill;
    text-shadow: 0 0.1em 0.3em rgba(0, 0, 0, 0.6);
    text-align: center;
    line-height: 1.2;
  }
  .line { display: block; text-align: center; }
  .word { display: inline-block; margin: 0 0.15em; }
`;

const pipeline = new RenderPipelineBuilder()
  .withInputVideo(inputVideo)
  .withTranscriber(new SrtTranscriber(srt))
  .withCss(captionCss)
  .build();

const { blob } = await pipeline.run();
3. Caption position
Captions default to bottom-center. To move them, pass an AlignmentConfig — fractions of the video's width and height as the anchor point, plus which edge of the caption box lands on that point.
const pipeline = new RenderPipelineBuilder()
  .withInputVideo(inputVideo)
  .withTranscriber(new SrtTranscriber(srt))
  .withCss(captionCss)
  .withAlignment({
    verticalAlign: 'top',
    verticalOffset: 0.12,
    horizontalAlign: 'center',
    horizontalOffset: 0.5,
  })
  .build();

const { blob } = await pipeline.run();
4. One word at a time (splitters)
The engine pipes the Document through a SegmentSplitter and a LineSplitter before rendering. Override them to force exactly one word per segment and one line per segment, then style each word as a large standalone caption.
import {
  RenderPipelineBuilder,
  SrtTranscriber,
  LimitByWordsSegmentSplitter,
} from '@tscaps/engine';

const singleWordCss = `
  .segment {
    font-family: system-ui, -apple-system, sans-serif;
    font-weight: 900;
    font-size: 11cqh;
    color: #ffffff;
    -webkit-text-stroke: 0.05em #000;
    paint-order: stroke fill;
    text-shadow: 0 0.12em 0.3em rgba(0, 0, 0, 0.6);
    text-align: center;
    line-height: 1.1;
  }
  .line { display: block; text-align: center; }
  .word { display: inline-block; }
`;

const pipeline = new RenderPipelineBuilder()
  .withInputVideo(inputVideo)
  .withTranscriber(new SrtTranscriber(srt))
  .withSegmentSplitter(new LimitByWordsSegmentSplitter({ maxWords: 1 }))
  .withDefaultLineSplitterConfig({ maxLines: 1 })
  .withCss(singleWordCss)
  .build();

const { blob } = await pipeline.run();
5. Karaoke highlight (state classes)
Every word carries a state class that reflects the current playback time: word-not-narrated-yet, word-being-narrated, or word-already-narrated. Target those classes in CSS to recolour each word as it plays.
const karaokeCss = `
  .segment {
    font-family: system-ui, -apple-system, sans-serif;
    font-weight: 800;
    font-size: 6cqh;
    -webkit-text-stroke: 0.06em #000;
    paint-order: stroke fill;
    text-shadow: 0 0.1em 0.3em rgba(0, 0, 0, 0.6);
    text-align: center;
    line-height: 1.2;
  }
  .line { display: block; text-align: center; }
  .word {
    display: inline-block;
    margin: 0 0.15em;
    color: #ffffff;
  }
  .word.word-being-narrated  { color: #ffd400; }
  .word.word-already-narrated { color: #b0b0b0; }
`;

const pipeline = new RenderPipelineBuilder()
  .withInputVideo(inputVideo)
  .withTranscriber(new SrtTranscriber(srt))
  .withCss(karaokeCss)
  .build();

const { blob } = await pipeline.run();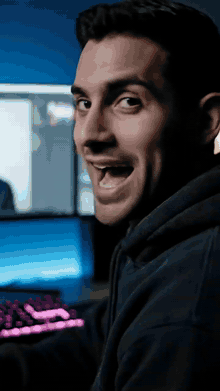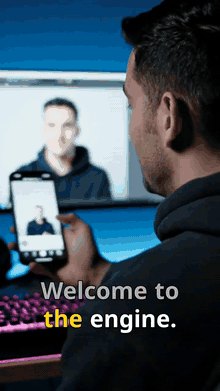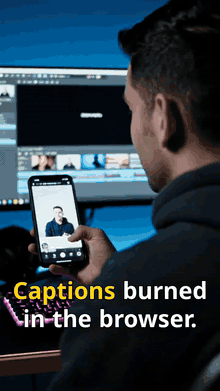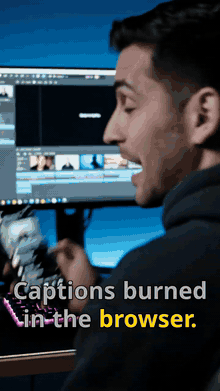
6. Animation driven by playback timing
The engine also exposes CSS custom properties that encode timing relative to the current frame — --on-segment-starts, --on-line-being-narrated-starts, --word-being-narrated-duration, and so on. Use them as animation-delay (or animation-duration) so a single keyframe rule plays in sync with the narration, frame after frame.
const slideInCss = `
  @keyframes segment-slide-in {
    from { transform: translateY(0.5em); opacity: 0; }
    to   { transform: translateY(0); opacity: 1; }
  }
  .segment {
    font-family: system-ui, -apple-system, sans-serif;
    font-weight: 800;
    font-size: 6cqh;
    text-align: center;
    line-height: 1.2;
    padding: 0.2em 0.6em;
    border-radius: 0.25em;
    background: rgba(255, 212, 0, 0.92);
    color: #111;
    animation: segment-slide-in 0.35s var(--on-segment-starts) ease-out both;
  }
  .line { display: block; text-align: center; }
  .word { display: inline-block; margin: 0 0.1em; }
`;

const pipeline = new RenderPipelineBuilder()
  .withInputVideo(inputVideo)
  .withTranscriber(new SrtTranscriber(srt))
  .withCss(slideInCss)
  .build();

const { blob } = await pipeline.run();
Document model
Every transcriber produces a Document whose hierarchy is:
Document
└── Section[]   contiguous run, processed by one splitter + tagger chain
    └── Segment[]   one screen-sized caption block, carries a time range
        └── Line[]   one visible line of text within a segment
            └── Word[]   a word with text, time range, and tag set
The pipeline restructures the same Words into different Segments and Lines through SegmentSplitter and LineSplitter; the underlying word data (text, time, tags) does not change.
The render layer exposes that document to CSS through four surfaces: a flat set of CSS classes per element, a flat set of CSS custom properties per element, a tag system that adds more classes via taggers, and an opt-in data-tscaps-el attribute for reaching one element by id. Everything the examples above target — .word, .word-being-narrated, --on-segment-starts, var(--on-line-being-narrated-starts) — comes from these surfaces.
Section never renders as an element: it is the grouping that decides which splitter and tagger chain a run of segments goes through, and the rendered subtree starts at .segment.
CSS classes the engine emits
Every rendered element carries its element class:
.segment— a caption block, the root of the rendered subtree.line— a visible line within a segment.word— a single word within a line.letter— a single letter within a word, emitted only whenrendering.splitWordsIntoLettersistrue.word-decoration— a decoration attached to a word (an emoji, for instance)
State classes — computed per frame from the current playback time and attached to the matching .word / .line:
word-not-narrated-yet,word-being-narrated,word-already-narratedline-not-narrated-yet,line-being-narrated,line-already-narrated
Positional tags from StructureTagger, assigned once after splitting:
first-word-in-line,last-word-in-linefirst-word-in-segment,last-word-in-segmentfirst-word-in-section,last-word-in-sectionfirst-line-in-segment,last-line-in-segmentfirst-line-in-section,last-line-in-sectionfirst-segment-in-section,last-segment-in-sectionfirst-segment-in-document,last-segment-in-document
Classes on elements the renderer creates rather than on document nodes, collected in the CssClass enum:
behind-actor-active— on.segmentwhile the text-behind-actor effect is active. Set by the consumer throughElementRenderOverrides; the engine publishes the class name inCssClasstscaps-video-frame-layer— the layer holding the video frame, emitted inside.segmentwhenrendering.videoFrame.requiredis setsegment-decorations-above,segment-decorations-below— the containers of decorations lifted out of line flow
Semantic tag classes come from Tagger implementations you add to the pipeline (see Tags and taggers below) and are entirely consumer-defined.
Addressing one element
A class reaches every element of its kind. To reach a single one, name its id in SubtitleStyle.addressableElementIds and the renderer stamps data-tscaps-el="<id>" (DataAttribute.ELEMENT_ID) on it:
.withSubtitleStyles({ default: { ...style, addressableElementIds: new Set([word.id]) } })[data-tscaps-el="<id>"] { color: #ff5c8a; }Any element id qualifies — segment, line, word or decoration. A word the bidirectional algorithm paints in two places gets the attribute on both pieces. The attribute is serialized once per element per rendered tile, so a caption with every word addressed grows the batch by a double-digit percentage; address nothing and it costs nothing.
CSS custom properties
Each rendered element exposes timing values relative to the current frame, so you can drive animation-delay, animation-duration, or any other CSS value from the narration timeline. --on-…-starts and --on-…-ends are seconds until the event; they go negative once the event is in the past. --…-duration is a span.
Segment-level timing:
--on-segment-starts,--on-segment-ends,--segment-duration
Per-state timing, for both .line and .word (substitute <elem> with line or word):
--on-<elem>-not-narrated-yet-starts,--on-<elem>-not-narrated-yet-ends,--<elem>-not-narrated-yet-duration--on-<elem>-being-narrated-starts,--on-<elem>-being-narrated-ends,--<elem>-being-narrated-duration--on-<elem>-already-narrated-starts,--on-<elem>-already-narrated-ends,--<elem>-already-narrated-duration
Letter-level, when splitting into letters:
--letter-index,--letter-count
Structural metadata — unitless integers, so a rule can stagger, scale or branch by an element's position and size without randomness. No on- prefix, because they are not events:
--segment-index— the segment's 0-based position within its section--segment-char-count— character length of the segment's full text, the input for auto-shrink rules--word-index— the word's 0-based position within its line--word-count— on.segmentand on.line; the nearest ancestor wins for a.wordreading it--word-char-count— code-point length of the word's display text--last-word-char-count— on.segmentand on.line; the length of the closing word, without traversing to it--line-char-count— character length of the line's text
Measured widths, as a multiple of the element's own font size. Only set when the stylesheet reads them:
--segment-width-em,--line-width-em,--word-width-em— how wide the element lays out under your stylesheet
Layout and frame:
--subtitle-region-width,--subtitle-region-height,--subtitle-region-x,--subtitle-region-y— the caption region's box, useful when positioning relative to the video frame--segment-anchor-y— where the caption's anchor sits, as a fraction of the frame height--segment-anchor-origin-y— share of the caption's own height above that anchor (0%,50%or100%). The two together let a rule place the caption against the frame instead of against its anchor--video-frame— the underlying video frame asurl("data:image/jpeg;base64,…"), only set whenrendering.videoFrame.requiredistrue(see docs/RENDERING_INTERNALS.md)--segment-padding-top,--segment-padding-bottom— the padding the renderer put on the segment to give a filter room to spread
Read by the engine's own baseline rules, so a stylesheet writes them rather than reading them:
--decoration-font-size-multiplier,--decoration-gap-multiplier— how large a decoration renders next to its word, and how far from it
Tags and taggers
A Tag is a CSS class the engine attaches to an element of the document. The engine recognises three sources:
- Structural tags are assigned by
StructureTagger, which runs once after splitting and encodes each element's positional role within its container (the list above under CSS classes). The structural tagger is part of every default pipeline; you can target these classes without writing any tagger yourself. - Semantic tags are assigned by
Taggerimplementations that pattern-match against word data. Built-ins:RegexTagger(matches a regex against the word text),WordlistTagger(membership in a set of strings),SpanTagger(a contiguous range of words by index). Build your own by extending theTaggerabstract class. Attach them through.addTagger(...)or.withTaggers([...])on the builder. - State tags —
word-being-narrated,line-already-narrated, etc. — are computed at render time from the current playback timestamp. They are never stored on theWordorLine; the engine just derives them per frame.
Tags map one-to-one onto CSS classes through Tag.toCssClass(). Unknown tag classes are silently ignored by CSS, so adding a new tag category is additive — it never breaks existing stylesheets.
What else the engine can do
The examples above cover the common cases. The pipeline exposes more knobs you'll reach for as your needs grow:
- Built-in transcribers:
WhisperTranscriber(the default, in-browser Whisper, with atiny/base/small/mediummodel ladder),SrtTranscriberandVttTranscriber(parse SubRip and WebVTT, reading per-word timings where the file carries them),PassthroughTranscriber(wraps a pre-builtDocument), with per-run options throughwithTranscriberOptions. Or implement your own by satisfying theTranscriberinterface. - Writing subtitle files:
SubtitleFileSerializeris the inverse of the parsers.SrtSubtitleFileSerializer,VttSubtitleFileSerializer,AssSubtitleFileSerializer,SbvSubtitleFileSerializer,TtmlSubtitleFileSerializerandTextSubtitleFileSerializereach declare their own media type and extension, andgranularity: 'word'asks for per-word timing where the format can express it. - Right-to-left and mixed-script text: each line is resolved through the Unicode bidirectional algorithm and its words are emitted in painting order.
RenderingConfig.textDirectionsupplies the paragraph direction,TextDirectionDetectorinfers it from a text, andAlignmentConfig.horizontalAlignadditionally acceptsstart/endso one declaration can follow the reading direction. - Cuts: time ranges declared on a
Documentare removed from the exported video, and captions realign to the shortened timeline. - Segment splitters: the default
CompositeSegmentSplitterchains a sentence-boundary cut with a scaled-character budget. Individual strategies are exposed for custom chains —BoundarySegmentSplitter,LimitByWordsSegmentSplitter,LimitByScaledCharsSegmentSplitter,PauseBasedSegmentSplitter,SpeakerChangeSegmentSplitter. - Line splitters:
BalancedLineSplitter(char-balanced, no measurer needed, with aminCharsPerLinefloor) andBalancedPixelWidthLineSplitter(pixel-balanced, backed by aTextMeasurer—DomProbeCanvasTextMeasureris the default measurer). - Render shape:
withRenderingConfig({ splitWordsIntoLetters, videoFrame, padding, textDirection })— the switches that change the emitted DOM rather than its styling. - Per-element styling:
ElementRenderOverridescarries inline styles, alignment and extra classes for one segment, line, word or decoration;mergedWithlayers a second set over an existing one. - Decoder choice: the default prefers WebCodecs and falls back to a hidden
<video>, asking first throughwithConfirmFallbackDecoder.WebCodecsOnlyVideoFrameDecoderFactoryrefuses that fallback withVideoFrameDecoderSelectionFailedError, andonVideoFrameDecoderSelectedreports which one ran. - Model weights across sessions:
WhisperTranscribertakes aModelFileCache;CacheStorageModelFileCacheis the browser-backed one, and raisesModelFileCacheUnavailableErrorwhen the browser refuses to store them. - Composing a stylesheet from several sources:
CssLayer,CssBlockSealer,CssKeyframeNamespacer,CssFragmentParser, plus scanners that report what a stylesheet defines and reads. - Replace any stage:
withTranscriber,withSegmentSplitter,withLineSplitter,withWordSplitter,withVideoRenderer,withSubtitleFrameRenderer,withOverlayFrameRenderer,withCssResourceEmbedder. Defaults stay in place until explicitly replaced. - Tweak default-stage configs without rebuilding them:
withDefaultSegmentSplitterConfig({ maxChars, minChars, ... }),withDefaultLineSplitterConfig({ maxLines, maxWidthRatio, ... }). - Output control:
withOutputFormat('mp4' | 'webm'),withOutputResolution(width, height),withQuality(...),withOutputStream(...)for streaming the encoded bytes as they're produced.withOverlayHtml(html)draws a self-contained snippet into every frame, andwithOnAudioDiscardedfires when a source's audio cannot be carried over. - Per-step execution:
runTranscriptionStep,runSplittingStep,runStructuralTaggingStep,runSemanticTaggingStep,runEffectsStep,runRenderingStep. Useful when you want to inspect or hand-edit theDocumentbetween stages —getDocument()andsetDocument(doc)give you read/replace access. - Progress reporting:
runaccepts a callback that fires through every pipeline stage — Whisper model download, transcription, splitting, tagging, effects, and per-frame rendering progress. - Effects and semantic taggers: pure document-transforming stages (smart punctuation, lowercase, regex/wordlist taggers, etc.) added via
addEffectandaddTagger, or set wholesale withwithEffectsandwithTaggers. - Multi-style captions:
withSubtitleStyles({ kindA: ..., kindB: ... })for documents with multipleSection.kindgroups, each carrying its own visual rule.withSubtitleStylereplaces the default wholesale;withCss,withAlignment,withInlineStylesandwithRenderingConfiglayer onto it.
Full type definitions and inline JSDoc ship in dist/index.d.ts. Runnable browser and CLI consumers live in examples/ in the source repository.
Going deeper
For the parts of the engine that sit below the public pipeline API — how each output frame is sampled into a bitmap via SVG <foreignObject>, how MediaBunny powers the encode, the browser caveats that come with that approach, how to feed the underlying video frame into your caption styles, and how SVG filters are authored — see docs/RENDERING_INTERNALS.md.
Project status
Pre-1.0. The public API surface is stabilising but may shift between minor versions until 1.0. Pin to an exact version in production and review the changelog before upgrading.
License
MIT — see LICENSE.