
agent-hours
v0.6.0
Published
Billable hours and worklogs from local Claude Code and Codex session logs, with an evidence-based direct interaction / supervised / AI-autonomous split.

Maintainers
 pmochine
Readme
agent-hours
Billable hours from your local coding-agent session logs — with an evidence-based split: direct interaction / supervised / AI-autonomous. Plus an hourly worklog for your invoice attachments.
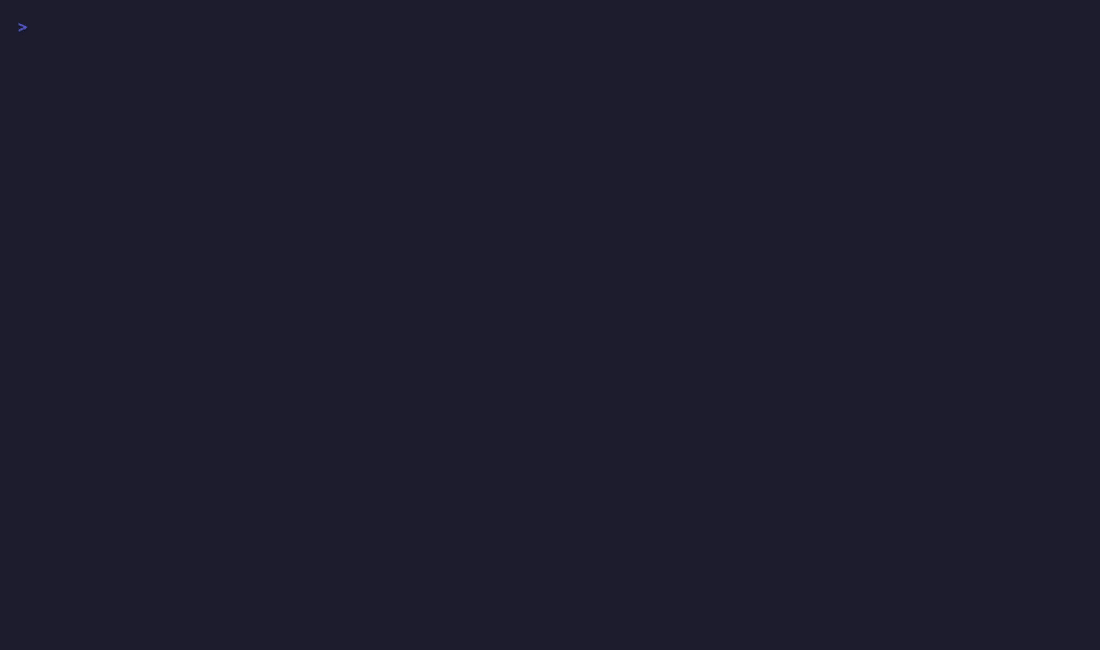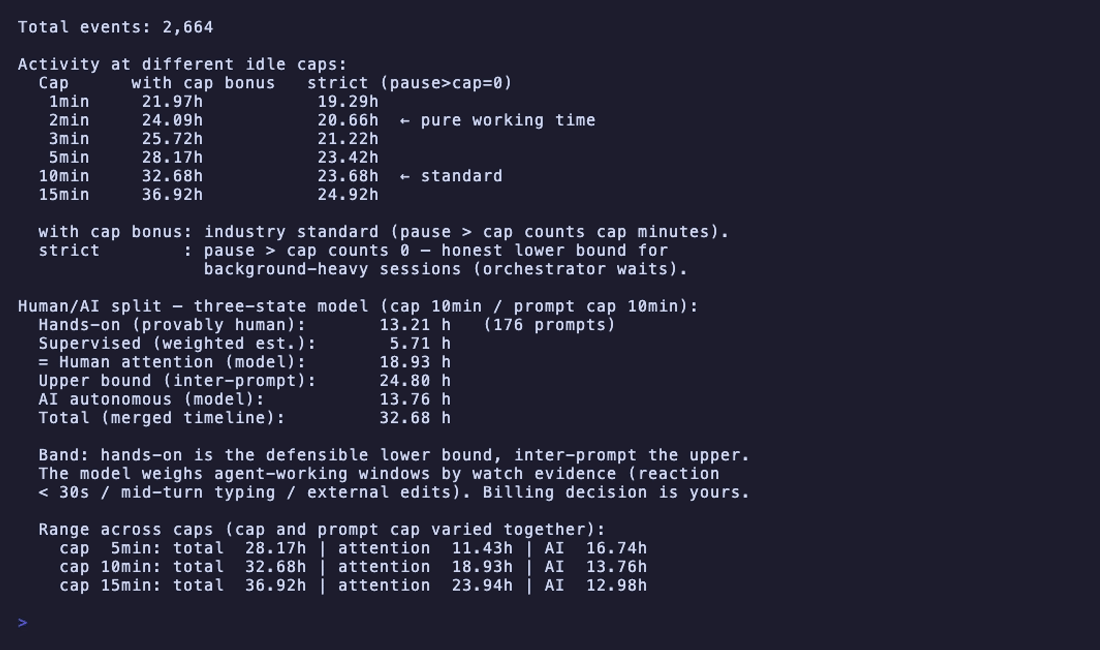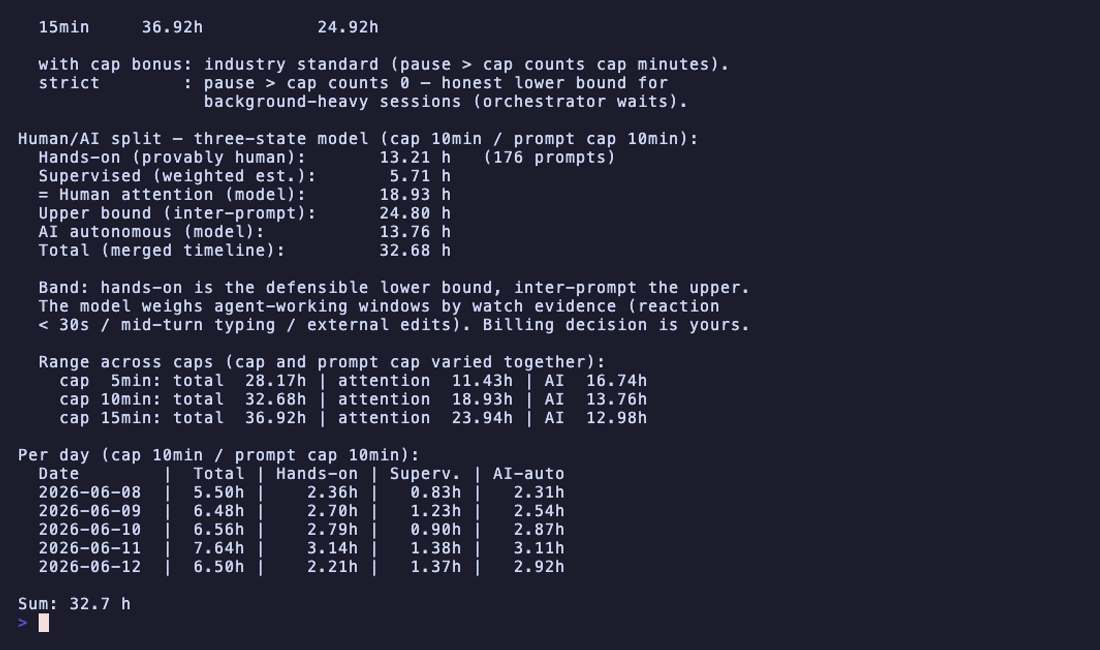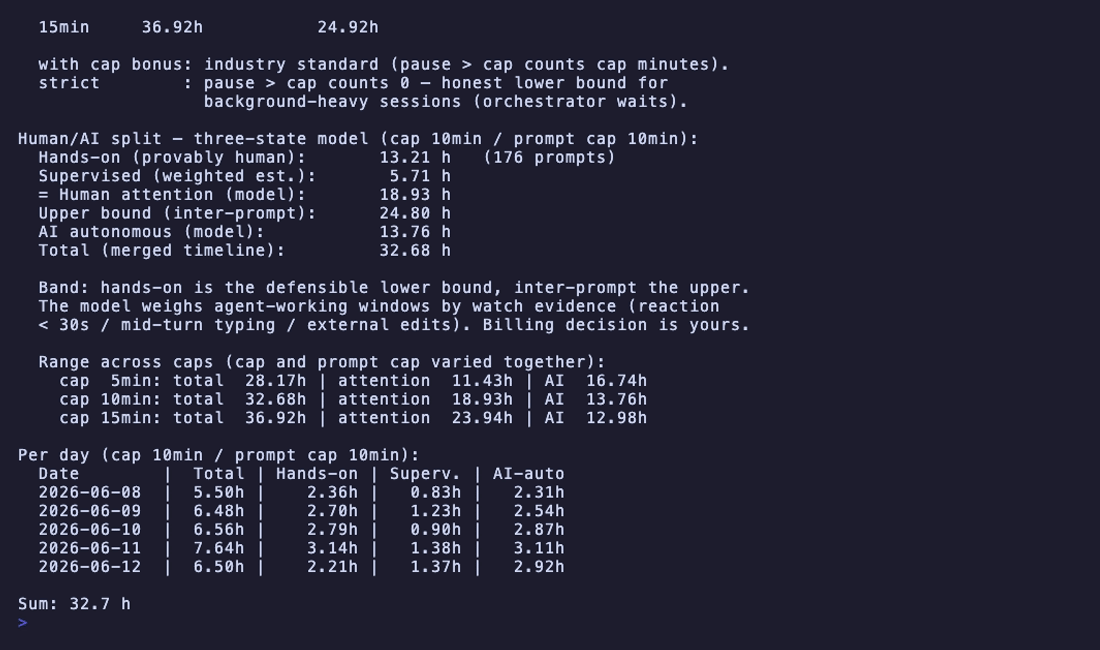
npx agent-hours --splitHuman/AI split — three-state model (cap 10min / prompt cap 10min):
Direct interaction (estimate): 9.26 h (237 prompts)
Supervised (weighted est.): 9.39 h
= Human attention (model): 18.65 h
Upper bound (inter-prompt): 21.44 h
AI autonomous (model): 18.99 h
Total (merged timeline): 37.65 hNo server, no account, no telemetry, no setup. It reads the session logs your agents already write to disk — which means it works retroactively on every project you've ever run an agent in.
Why
If you freelance with AI tooling, you need defensible numbers for every invoice conversation:
- How long did the work take overall? (effort evidence)
- How much of it were you, actively driving or supervising — vs. the agent grinding alone while you made coffee?
- What was actually done, hour by hour? (the attachment your client never questions)
Existing tools don't answer this:
| Tool | What it gives you | What it can't do |
|---|---|---|
| WakaTime agent plugins | coding activity dashboards | no billing split, not retroactive, cloud service |
| Claude Code OpenTelemetry | active_time metrics | needs Prometheus/Grafana, only logs from activation onward |
| ccusage | tokens & API cost | no hours at all |
| Estela | billable hours from Claude Code, Codex and Copilot logs, clients, rates, PDF | no human/AI split, gap-based blocks only |
agent-hours is local, retroactive, billing-oriented — and it refuses to pretend one fake-precise number is the truth.
Features
- Three-state human/AI split — direct interaction (capped reaction-time estimate), supervised (evidence-weighted), and AI-autonomous; the full attention budget for each prompt window is shown as an upper estimate, so you get a transparent band rather than fake precision.
- Multi-agent, one timeline — Claude Code and Codex CLI sessions merge into a single timeline. Parallel agents never double-count wall-clock time; an agent launched by another agent counts as AI runtime, not as you.
- Hourly worklog — what was done per hour: your prompts, edited files (incl. subagents), commands, commit messages, and the away-summaries the agent itself wrote.
- Descriptions with or without AI — rule-based summaries are the default (deterministic, free, reproducible).
--summarizeoptionally refines them viaclaude -p— the only feature that costs API money, strictly opt-in. It is also the only feature that sends data off the machine: prompt excerpts, file paths and commit messages go to Claude viaclaude -p. Or pipe--worklog-jsoninto the AI chat you're already paying for. - Exports — CSV (hours/days, with description column and project total row; English headers by default,
--lang defor German headers), JSON, markdown worklog. - Regression-tested timekeeping core — merged-timeline idle-cap math, parallel-session detection, pause analysis, cap-bonus vs. strict columns, per-session breakdown.
- All projects at a glance —
--all-projectsranks everything on your machine.
Install (pick your comfort level)
Level 0 — just ask your agent. Paste this into Claude Code or Codex:
Install agent-hours (
npx agent-hours install) and then tell me how many hours I worked on this project this month and what I did.
Level 1 — one command, then talk naturally:
npx agent-hours install        # drops a skill into ~/.claude and $CODEX_HOME
                               # (default: ~/.codex),
                               # and offers to raise Claude's log retention
From then on, questions like "What did I work on this week?" or "Export a CSV of my June hours for the invoice" just work — your agent runs the CLI and interprets the band for you. The installer also checks that Claude Code keeps logs long enough to bill against (see retention).
Level 2 — Claude Code plugin (this repo doubles as one):
/plugin marketplace add pmochine/agent-hours
/plugin install agent-hours
Level 3 — raw CLI, no agent involved — see Usage below.
Usage
npx agent-hours install [claude|codex|all] # install the skill for selected agents
npx agent-hours doctor             # check sources, retention, and schema
npx agent-hours doctor --json      # the same diagnostics as JSON
npx agent-hours                    # current project, hours at several idle caps
npx agent-hours --split            # direct interaction / supervised / AI-autonomous
npx agent-hours --by-day --split   # per-day table with split

# worklog: what was done, hour by hour
npx agent-hours --worklog                  # markdown, rule-based descriptions
npx agent-hours --worklog --summarize      # + AI-refined lines (claude -p, paid)
npx agent-hours --worklog --csv            # hourly CSV incl. description column
npx agent-hours --worklog --csv --by-day   # daily CSV incl. descriptions
npx agent-hours --worklog-json             # structured + LLM prompt template

# exports & scope
npx agent-hours --csv > hours.csv          # plain per-day CSV (invoice tools)
npx agent-hours --csv --lang de            # German CSV headers
npx agent-hours --json                     # machine-readable, full split
npx agent-hours --since 2026-06-08 --until 2026-06-12
npx agent-hours --project <path|hash>      # project path or Claude project hash
npx agent-hours --source claude|codex|auto # default auto: merge all agents
npx agent-hours --all-projects --source auto --split

# tuning & debugging
npx agent-hours --cap 10 --prompt-cap 10 --timezone Europe/Berlin
npx agent-hours --tz-offset 2                 # fixed-offset compatibility mode
npx agent-hours --by-session               # parallel sessions, per-file
npx agent-hours --pauses                   # longest gaps > cap
npx agent-hours --pauses --top-pauses <n>  # number of pauses to list
When hours look wrong or after an agent update, run agent-hours doctor. It reports source sizes, retention risk, unfamiliar record kinds, and possible passive records without printing prompts, log content, or project paths. The read-only canary checks files modified in the last 14 days, stops at 400 MB, and exits successfully even with warnings.
Methodology
Idle-cap timing sums the gaps between consecutive events and caps each gap at a configurable limit. This is a common activity-log technique, but it is still a model rather than a stopwatch. The output shows several caps (1/2/3/5/10/15) plus a strict column (pause > cap counts zero), so you can see the sensitivity of the result.
Credited time is placed immediately after the earlier event, up to the next event or the cap. Date ranges and hourly buckets clip those intervals; adjacent ranges add up to the whole period. --since is inclusive; --until with a time is exclusive, while a date-only --until includes the whole local day. The repeated daylight-saving hour is shown separately as HH:00 (repeated). Hourly worklog CSV minutes have one decimal.
The three-state split answers the question a binary human/AI split gets wrong — was the human actually there while the agent worked?
- Direct interaction — capped reaction tails between the latest assistant output in the same session and your next prompt. If two prompts arrive without an answer between them, the earlier prompt is the fallback anchor. This estimates time spent reading, thinking, or typing; it does not prove continuous work throughout the tail.
- Supervised — the agent-working part of each prompt window, weighted by same-session watch evidence: you reacted within 30 s afterwards (you were watching) ⇒ 100 %, within 5 min ⇒ 50 %, slower ⇒ 0 %. Hard presence proof in that session — you typed a queued message mid-turn, or an external file change was noticed while the agent ran — forces 100 %. An edited-file notice only qualifies if no other session (including a subagent) edited the same normalized path in the preceding 30 minutes.
- AI autonomous — the rest of agent runtime.
What you bill is your decision; the tool gives you the evidence and the band.
Classification details verified against current and legacy logs: scheduled-task, SDK, hook, command-envelope, and task-notification records are filtered out; queued messages are credited at the moment you typed them; compact-continuation summaries don't count; and Claude/Codex subagent plus Codex exec and mcp sessions count entirely as machine work. Multipart Codex messages keep their human text while dropping injected context blocks. Codex voice input and question replies, plus Claude AskUserQuestion answers, count as human input. Claude away_summary and Codex thread_settings_applied are excluded from timing: they can arrive after departure and pad pauses. Away summaries remain available as worklog evidence.
Sources
| Agent | Status | Logs read from |
|---|---|---|
| Claude Code | ✅ | ~/.claude/projects/<hash>/*.jsonl + <session>/subagents/ |
| Codex CLI | ✅ | $CODEX_HOME/sessions/**.jsonl + $CODEX_HOME/archived_sessions/**.jsonl (default home: ~/.codex, matched via cwd, deduplicated by session ID and continuation segment) |
| Gemini CLI, opencode, Cursor, Aider | planned | see adapter notes below |
Adapter contract: {ts, kind: prompt|work, presence, reactionAnchor, editedPath?, agentEdits?} events in src/sources/, plus worklog extraction in src/worklog.ts and wiring in src/cli.ts. The Claude Code adapter currently lives in src/core.ts; adapters return events inside NamedSession[], and merging attaches session identity. PRs welcome.
Sessions started in subdirectories of the project are included for both Claude and Codex. --all-projects groups Claude files by their own canonical cwd, with subagents following their parent; files without cwd are grouped under their log directory. Claude workflow subagents below subagents/workflows/wf_*/ count as machine work. Codex long threads can span continuation files (history_base); unique segments merge using the base thread’s classification, and archived copies count once.
Logs are read as streams, so large transcripts do not need to fit in memory. --since skips event bodies in files whose modification times predate its context window, speeding up recent reports; old Codex base metadata is still read to classify continuations. After pruning, the first loaded prompt gets a window from the first loaded event: the direct-interaction tail and reaction weight remain exact, while the proportional supervised share of a window that began in a pruned file can differ. Doctor flags schema drift and unreadable or unsupported files before you rely on a report.
Retroactive use & log retention
Everything works retroactively — as long as the logs are still on disk:
- Claude Code prunes old transcripts after
cleanupPeriodDays(default: 30 days). For billing you almost certainly want more.npx agent-hours installchecks this for you and offers to raise it to 365 days (or set it yourself in~/.claude/settings.json:{"cleanupPeriodDays": 365}). Do it before you need last quarter's hours — once a transcript is pruned, it's gone. - Codex CLI sessions can be active or archived.
agent-hoursreads both locations as long as the JSONL files are still present on disk.
The install command never changes your settings silently: in an interactive terminal it asks first; when an agent runs it, it only prints the recommendation. Use --set-retention to apply it non-interactively or --no-retention to skip the check.
Rule of thumb: run exports when you invoice and archive the CSV/JSON next to the invoice. That preserves the report, while the underlying logs remain the detailed evidence.
Honest caveats
- The logs only see the agent CLI. Time in the browser, on calls, reading docs, or in another editor is invisible (external file edits show up only as presence signals). Reconcile that time separately from calendar or other records; the logs do not justify a universal percentage markup.
- "Supervised" is a weighted estimate, not a stopwatch. A fast reaction proves presence at the end of a window, not throughout — which is exactly why supervision is capped per prompt window.
- Agent activity after a session's final human prompt has no later reaction signal, so the model conservatively leaves it in AI-autonomous time.
- If cap bonus and strict columns diverge a lot, your sessions had many long waits — quote the strict number to be conservative.
Roadmap
- Manual entries — calls and research that agent logs cannot see.
- Client profiles — several repositories under one rate.
--rate— money columns for invoice exports.--by-week/--by-month— grouping for retainer billing.- “Billed until” cutoff — start the next invoice where the previous one ended.
- Reproducible invoice snapshot — version, parameters, and input fingerprints.
- HTML report — one printable file as the invoice attachment.
- More agents — Gemini CLI, opencode, Cursor, Aider.
- Git triangulation —
--git: inter-commit hours as a cross-check column. - Optional live precision — opt-in macOS idle-time sampler to separate "watching" from "AFK" with hardware truth.
Verification
The test suite has direct regression coverage for the current three-state model, current Claude/Codex schemas, archives, subagents, source filtering, cap invariants, project matching, and daylight-saving behavior (npm test).
License
MIT