
claude-code-ledger
v0.4.0
Published
Local-first cost & tool-call audit for Claude Code (plus Codex / Gemini CLI / Cursor logs): per-tool context cost, waste detection, CLAUDE.md suggestions, budget statusline, before/after compare, HTML report. Never reads your message content.

Maintainers
 caiqianha
Readme
ccledger


Local-first cost & tool-call audit for Claude Code — with readers for Codex CLI, Gemini CLI and Cursor logs (--agent).
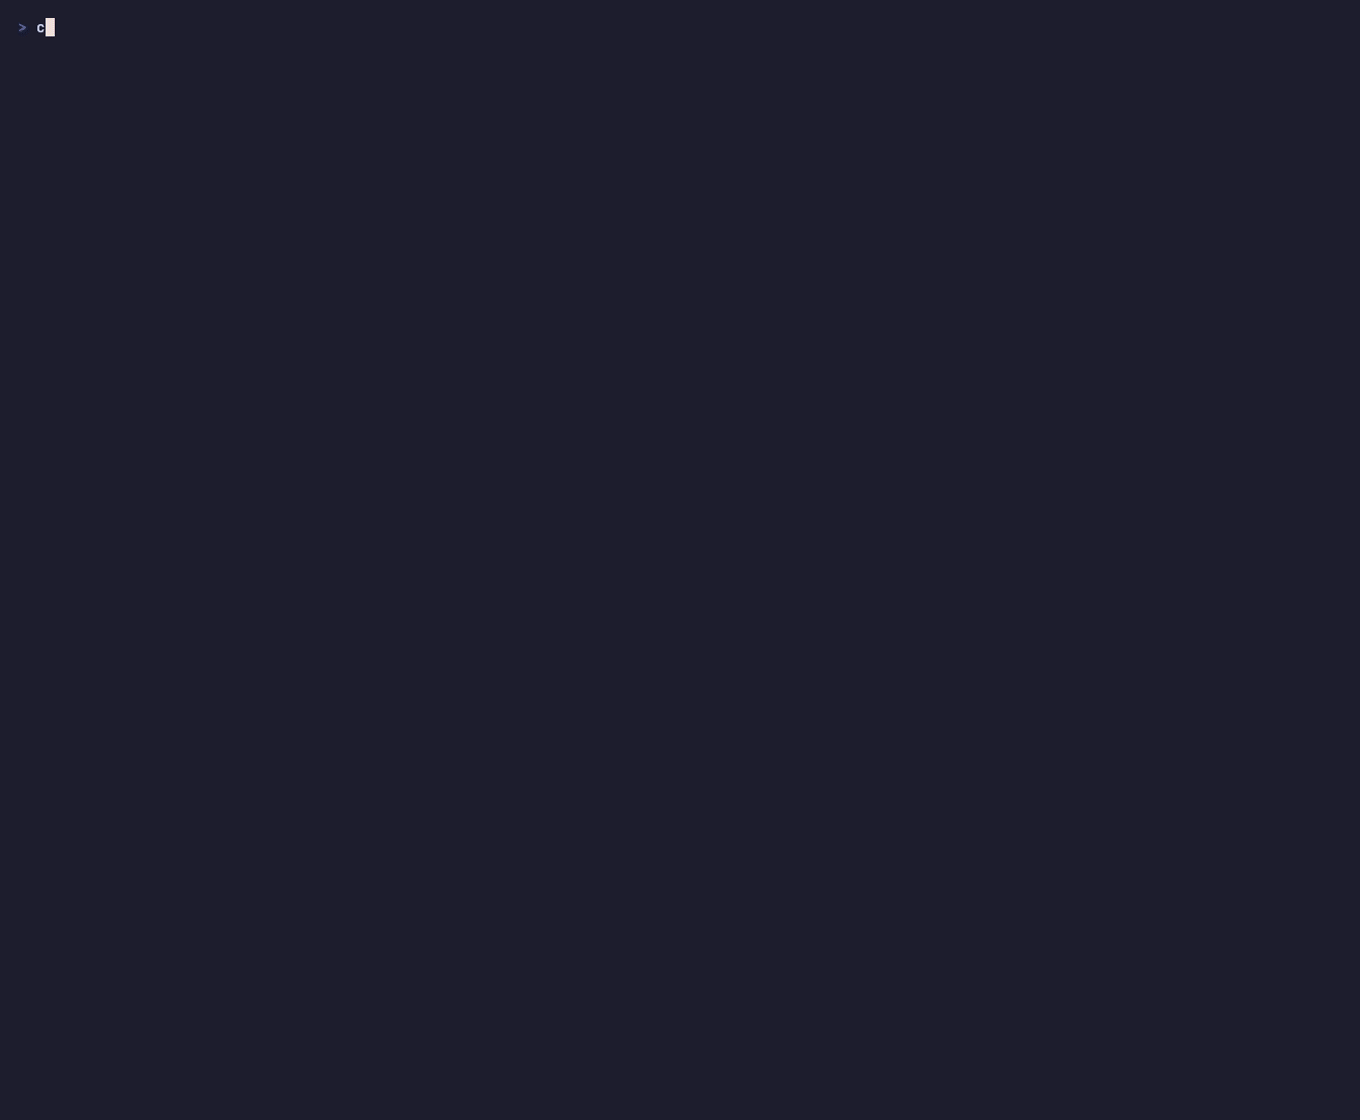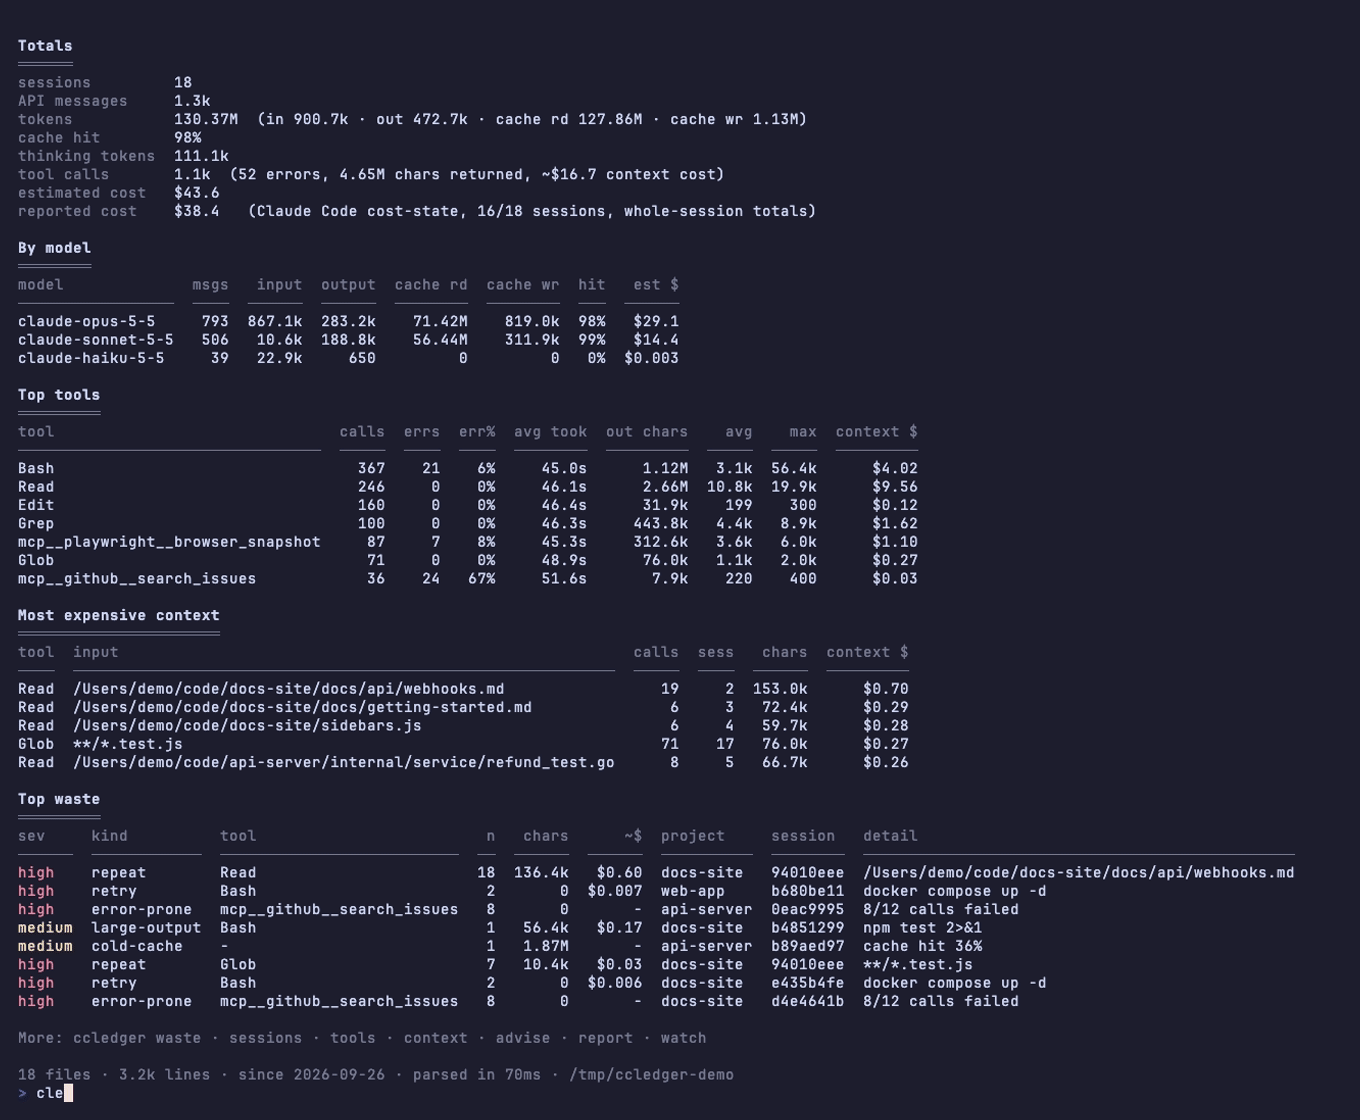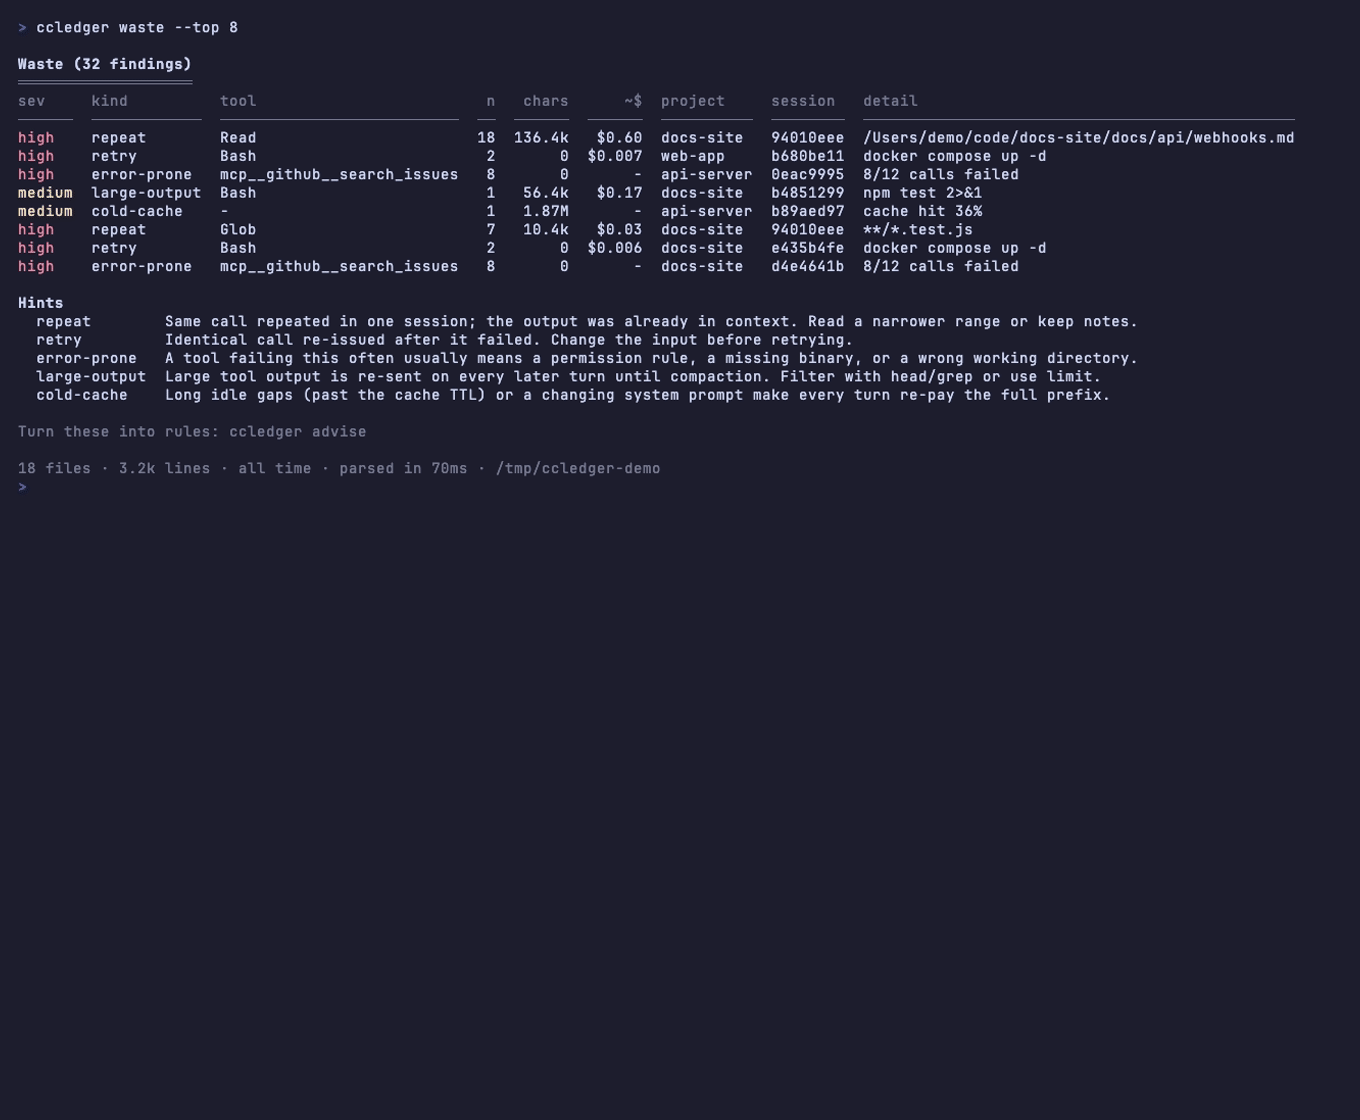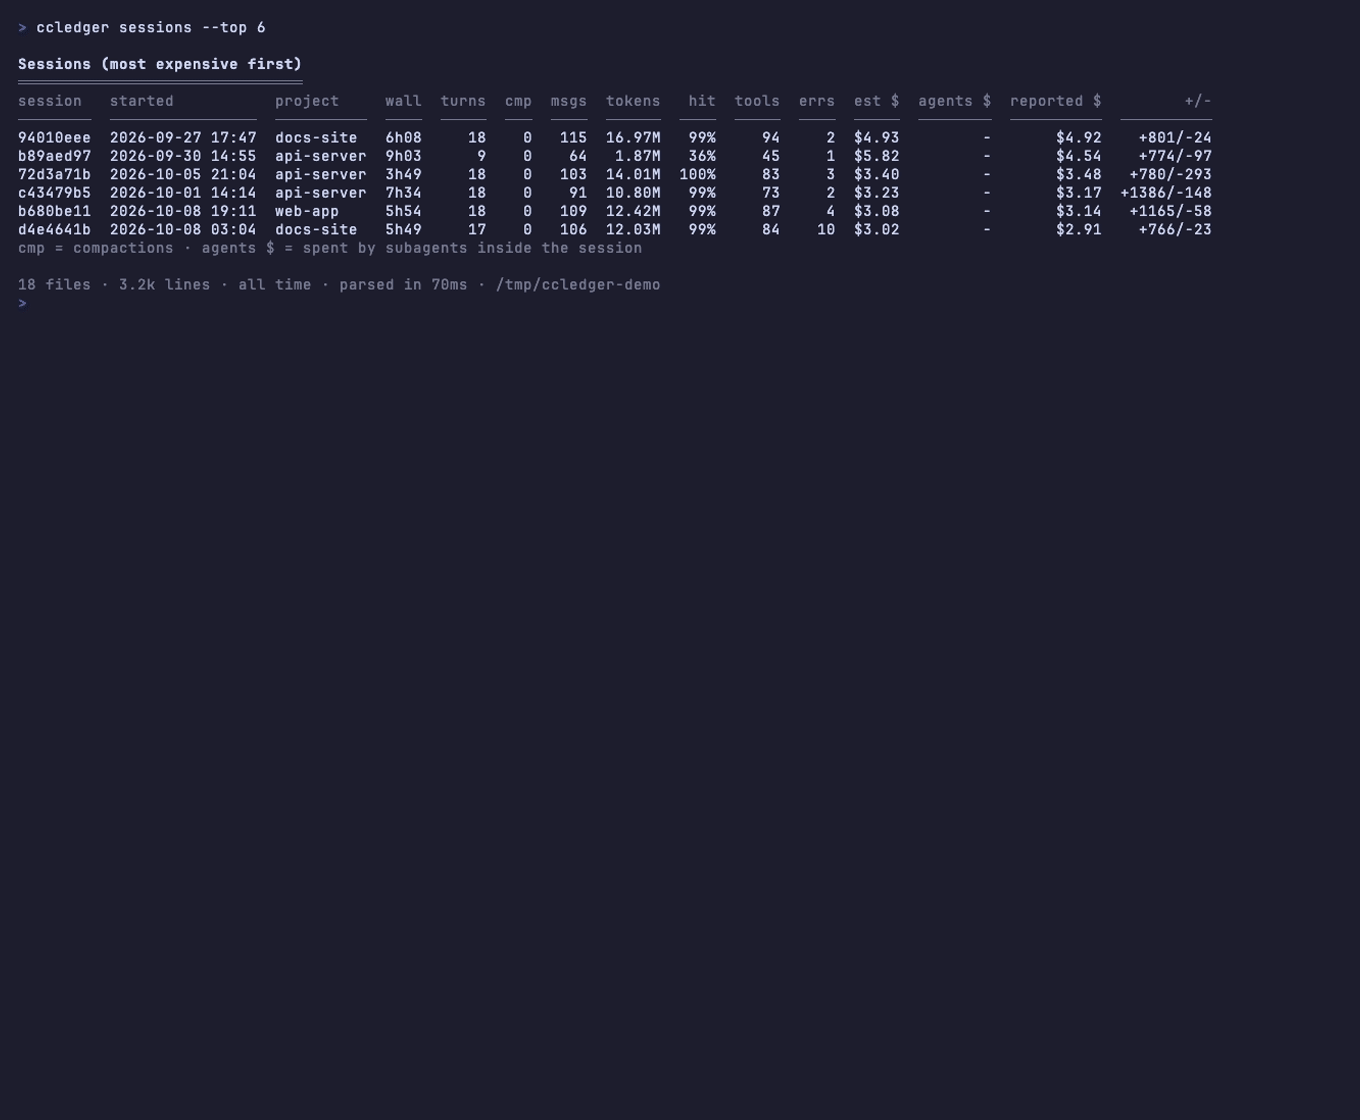
Open the demo HTML report · Demo recorded on synthetic data from scripts/demo-data.mjs. No real session appears anywhere in this repo.
Reads the session logs Claude Code already writes to ~/.claude/projects/, and tells you where the tokens went: per day, per project, per session, per model, per tool, plus the call patterns that burn context for nothing. The same report runs over Codex CLI rollouts, Gemini CLI chat recordings and Cursor's chat database (see Other agents).
Why
Token dashboards tell you how much you spent. ccledger also tells you on what, at the tool-call level:
- which tool is called most, fails most, and returns the most bytes into your context
- the same file read 8 times in one session
- an identical command re-run right after it failed
- a 60 KB tool output that gets re-sent on every following turn
- long sessions whose cache hit rate collapsed
- what each tool result actually cost once it sat in the context window for the rest of the session
Each finding comes with a one-line hint, ccledger advise --claude-md turns the patterns into CLAUDE.md rules with the evidence behind each one, and ccledger compare --mark tells you afterwards whether the rules helped.
Install
npm install -g claude-code-ledger   # installs the `ccledger` command
npx claude-code-ledger              # or run it once without installing
Node 18+. Zero runtime dependencies. The npm package is claude-code-ledger; the CLI is ccledger.
Usage
ccledger [command] [options]

Reports
  summary          Totals, per-model split, top tools, top context, top waste (default)
  daily            One row per day (est + apportioned reported cost)
  projects         One row per project
  sessions         Most expensive sessions (with subagent share)
  tools            Calls / errors / latency / output size / context cost per tool
  context          Most expensive tool results by file / command / query
  waste            Wasteful call patterns with hints
  models           Token split per model
  today            Today's spend, tokens and waste; shows the daily budget when one is set
  compare          Before/after table: waste rate, tokens & cost per session, cache hit, verdict
  advise           Paste-ready CLAUDE.md block (--claude-md: rules + the evidence that triggered them)
  report           Single-file HTML report (--out report.html)

Live & integration
  watch            Live view of the current session (--session <id-prefix>)
  hook             One-line session summary for a Claude Code Stop hook
  statusline       Status bar line for Claude Code's statusLine setting (with --budget)
  merge <a.json..> Combine several --json exports (e.g. a team) into one report

Pricing
  calibrate        Compare estimates with Claude Code's own cost-state (--write to apply)
  update-pricing   Download the latest pricing table into ~/.config/ccledger/pricing.json

Options
  --agent <a>      claude (default) | codex | gemini | cursor | all | comma list
  --since <v>      7d | 24h | today | yesterday | YYYY-MM-DD   (default: all; compare: 7d)
  --until <v>      YYYY-MM-DD (inclusive)
  --project <s>    Substring match on project name / path
  --dir <path>     Log directory, repeatable (default: $CCLEDGER_DIR or ~/.claude/projects;
                   with a single --agent it points at that agent's directory)
  --top <n>        Rows to show in ranked tables (default: 15)
  --large <chars>  "Large output" threshold in characters (default: 30000)
  --kind <k>       waste only: repeat | retry | large-output | error-prone | cold-cache
  --budget <usd>   Daily budget for statusline / today (or "budget" in ~/.config/ccledger/config.json)
  --claude-md      advise: suggested rules with evidence (--out CLAUDE.suggestions.md to write a file)
  --baseline <v>   compare: "30d" or "20 sessions" (default: same length as the --since window)
  --mark [label]   compare: store a marker now (with label) / compare before vs after the last marker
  --json           Print the aggregate as JSON
  --no-color       Disable ANSI colors (also honours NO_COLOR)
Examples:
ccledger daily --since 7d
ccledger sessions --project my-app --top 5
ccledger context --since 30d          # which files / commands cost the most to keep in context
ccledger advise --since 14d >> CLAUDE.md
ccledger report --since 30d --out report.html
ccledger watch                        # leave it open in a split pane while you work
ccledger advise --claude-md --out CLAUDE.suggestions.md   # rules + evidence, ready to paste
ccledger compare                      # last 7 days vs the 7 days before
ccledger today --budget 20            # today's spend against a daily budget
ccledger --agent codex                # same report over Codex CLI rollouts
ccledger sessions --agent all         # Claude Code + Codex + Gemini CLI + Cursor in one table
No logs of your own yet? Try it on synthetic data:
npm run demo # generates /tmp/ccledger-demo and prints a summaryStop hook: a cost line after every session
Add to ~/.claude/settings.json (or a project's .claude/settings.json):
{
  "hooks": {
    "Stop": [{ "hooks": [{ "type": "command", "command": "ccledger hook" }] }]
  }
}
Claude Code pipes the session id and transcript path to the hook; ccledger hook prints the session's cost, cache hit rate, tool calls and its single worst waste finding.
Status line: cost, budget and context in the Claude Code status bar
{
  "statusLine": { "type": "command", "command": "ccledger statusline --budget 20" }
}
Claude Code runs the command after every assistant message and pipes it the session JSON. ccledger statusline prints one line:
Opus · $1.94 · today $12.40/$20 62% · ctx 62.3k 31% · 51 calls · cache 99% · 5.75M tok · ⚠ repeat Glob **/*.test.js ×4Cost and context come from Claude Code itself, tool counts and the top waste flag from the transcript. The transcript is tailed incrementally (byte offset cached under the OS temp dir), so each refresh parses only the new lines. Segments are dropped from the right when the terminal is narrow; --no-cache forces a full re-parse.
Daily budget
--budget <usd> (or "budget": 20 in ~/.config/ccledger/config.json, or $CCLEDGER_BUDGET) adds today's estimated spend across every session touched today. The segment turns yellow with a ⚠ at 80% and red with ⚠ over at 100%; with NO_COLOR, --no-color or a non-TTY the markers stay and only the colors go. ccledger today prints the same number with today's sessions, tokens and top waste finding. Today's spend is the per-message estimate (list prices), not Claude Code's whole-session cost-state, so it can be summed per day and across agents.
CLAUDE.md suggestions with evidence
ccledger advise --claude-md --since 30d                       # print
ccledger advise --claude-md --since 30d --out CLAUDE.suggestions.md
Emits a Markdown block of rules, each only when its pattern crossed a threshold, each followed by the evidence that triggered it:
## Working rules (suggested by ccledger)

How to apply: paste this section into CLAUDE.md, delete the rules that do not fit ...

- Before reading a file, check whether it is already in context from an earlier Read; re-read only the part you need with `offset`/`limit`.
  - evidence: 18% of file reads (54 of 300) re-read a file that was already in context in the last 30 sessions; most repeated: `src/api/order.js` ×12.
- When a command or tool call fails, do not re-run it unchanged. ...
  - evidence: 7 identical retries right after a failure in the last 30 sessions (e.g. `npm test` ×4).
| rule | fires when (defaults in CLAUDE_MD_THRESHOLDS, src/advise.js) |
| --- | --- |
| check context before Read | ≥10% of file reads re-read a file already in context (≥10 reads) |
| do not repeat a search | ≥15% of Grep/Glob calls repeat an identical query (≥10 searches) |
| do not re-run read-only commands | ≥15% of shell commands are exact repeats (≥10 commands) |
| change something before retrying | ≥2 identical re-runs right after a failure |
| keep tool output short | ≥2 results over the --large threshold |
| fix an error-prone tool | a tool fails ≥25% of the time over ≥10 calls |
| one task per session | ≥1 long session with cache hit under 50% |
The classic ccledger advise (file- and command-specific rules) is unchanged.
Before/after: did the change help?
ccledger compare                              # last 7 days vs the 7 days before
ccledger compare --since 14d --baseline 30d   # last 14 days vs the 30 days before that
ccledger compare --since 7d --baseline "20 sessions"
ccledger compare --mark "claude.md rules"     # store a marker now (in ~/.config/ccledger/state.json)
ccledger compare --mark                       # ...later: before the marker vs after it
metric before after delta
waste rate (wasteful calls / tool calls) 19% 6% -13 pts
avg tokens / session 2.41M 1.62M -33%
cache hit rate 84% 93% +9 pts
est cost / session $4.10 $2.35 -43%
...
Better: waste rate -13 pts, avg tokens / session -33%, cache hit rate +9 pts, est cost / session -43% (15 vs 12 sessions).Waste rate counts tool calls that repeat an identical read within one compaction window, identical retries after a failure, and results over the large-output threshold. Deltas are relative for averages and percentage points for rates; the verdict weighs waste rate, tokens and cost per session and cache hit rate, and says "Not enough data" when either window has no sessions.
Other agents: Codex CLI, Gemini CLI, Cursor
--agent codex|gemini|cursor runs every report over another agent's local logs; --agent all merges all of them (an agent column and a "By agent" table appear). Every reader maps its format onto the same normalized model (sessions → turns → tool calls with input key / output size, tokens, model, timestamps, project), so repeat / retry / large-output detection and context-cost attribution work the same way. Readers skip malformed lines and ignore unknown fields.
| agent | reads | available | not available / caveats |
| --- | --- | --- | --- |
| Claude Code (default) | ~/.claude/projects/**/*.jsonl | everything above | — |
| Codex CLI | ~/.codex/sessions/YYYY/MM/DD/rollout-*.jsonl ($CODEX_HOME) | tokens from token_count events (cumulative deltas, cached tokens split out; sessions without them fall back to a ~ estimate from message length), model from turn_context, function_call / local_shell_call / custom_tool_call + outputs joined by call_id, compactions, exit-code based errors, cost from the OpenAI price table | no reported cost; no cache-write tokens. Format observed with Codex CLI 0.115 (2026-10) and cross-checked against codex-rs/protocol. |
| Gemini CLI | ~/.gemini/tmp/<project-hash>/chats/session-*.jsonl (.json legacy; subagents in a subfolder) | tokens recorded per gemini message (input/output/cached/thoughts), model, toolCalls with status and result size, $patch updates | messages without tokens are estimated from text length (chars/4) and shown with ~; no compaction events. Based on gemini-cli 0.65 (main, 2026-10) chatRecordingTypes.ts; not verified against a live install. |
| Cursor (best effort) | ~/Library/Application Support/Cursor/User/globalStorage/state.vscdb (+ workspaceStorage/*/state.vscdb; Linux ~/.config/Cursor/User, $CURSOR_USER_DIR) via the sqlite3 CLI | composers → sessions, bubbles → turns, tool name / status / params path / result size, sparse tokenCount, model name, workspace folder | no cost (Cursor bills per request, shown as n/a); tokens mostly estimated (~); no cache or compaction data; legacy aichat.chatdata tabs read on a best-effort, unverified basis. Needs sqlite3 on PATH (ships with macOS); otherwise a message is printed and Cursor is skipped. Only projected columns are selected (json_extract), never message text. |
watch, hook and statusline stay Claude Code only. Prices for OpenAI (gpt-5 family, o-series, gpt-4.1/4o) and Gemini (2.5 / 3.x) are in pricing.json as list prices as of 2026-10; the same override file (~/.config/ccledger/pricing.json) applies.
Team view
Everyone runs ccledger --json --since 30d > me.json; collect the files and run ccledger merge *.json. Exports contain no message content, only the aggregates you see in the tables.
How costs are computed
Two numbers are shown and they are intentionally different:
| column | source | notes |
| --- | --- | --- |
| reported $ | Claude Code's own cost-state records | What Claude Code itself believes the session cost. Whole-session totals, so they ignore --since. Treat this as the truth when present. |
| est $ | usage on every API message × pricing.json | Works per day / per model / per project. List prices for the first-party API (Anthropic, OpenAI and Gemini tables, snapshot 2026-10); edit the file if your rates differ. Unknown models show $…+ and are flagged; agents without per-token billing (Cursor) show n/a; token counts estimated from text length are prefixed ~. |
A third number, context $, is attributed to tool results: a result enters the prompt once (cache write) and is re-read on every later API message in the session until the next compaction, so cost ≈ tokens × (cache_write + cache_read × later_messages). It is an estimate, but a consistent one, so files, commands and tools rank fairly against each other.
Streaming splits one API message across several log lines that repeat the same usage; ccledger de-duplicates by message id, so tokens are counted once. Subagent (sidechain) messages are included in totals and shown separately as agents $ in sessions and summary.
Privacy
ccledger never prints or stores message text, thinking, or tool output. It reads:
- token counts and model ids
- tool names, file paths and the first 80 characters of a command or query (for the
detailcolumn) - the size of tool results, not their content
Everything runs locally. There is no network access of any kind.
Waste detectors
| kind | fires when | typical fix |
| --- | --- | --- |
| repeat | the same read-like call (Read / Grep / Bash / MCP…) appears ≥4× within one compaction window of a session | read a narrower range, keep notes, add a CLAUDE.md rule |
| retry | an identical call is re-issued right after it failed | change the input before retrying |
| large-output | a single tool result ≥ 30 000 chars | pipe through head / grep, use limit |
| error-prone | a tool fails ≥25 % of the time in a session (≥5 calls) | permission rule, missing binary, wrong cwd |
| cold-cache | ≥500k tokens in a session with cache hit <50 % | avoid long idle gaps, keep the system prompt stable |
Thresholds live in src/analyze.js; --large overrides the output threshold from the CLI.
Roadmap
- [x] per-tool / per-file context cost attribution
- [x]
advise: export findings as a CLAUDE.md block - [x]
watchmode, Stop hook and status line - [x] HTML report, team
merge - [x] subagent breakdown, compaction-aware detectors, calibration against cost-state
- [x] loaders for other agent CLIs' logs (Codex CLI, Gemini CLI, Cursor)
- [x] CLAUDE.md suggestions with evidence, daily budget, before/after compare
- [ ] per-turn timeline view
Development
npm test              # node:test, no extra deps
npm run demo          # synthetic data + summary
npm run demo:gif      # re-render assets/demo.gif (needs vhs)
See CONTRIBUTING.md before opening a PR.
Contributions welcome. Run npm test before opening a PR.
中文说明
ccledger 是一个本地运行的 Claude Code 账单与工具调用审计工具。它读取 ~/.claude/projects/ 下已有的会话日志,按天、项目、会话、模型、工具统计 token 与花费,并找出浪费上下文的调用模式:同一文件反复读取、失败后原样重试、超大工具输出、缓存命中率崩掉的长会话。
- 不联网,不读取也不输出任何消息正文,只看 token 数、工具名、文件路径和输出大小。
reported $来自 Claude Code 自己记录的cost-state,是整个会话的真实花费;est $按pricing.json估算,可以按天 / 按模型拆分,价格表可自行修改。- 每条浪费项附带一句建议,可直接写进
CLAUDE.md或做成 hook;advise --claude-md只输出越过阈值的规则,并给出触发它的证据。 --agent codex|gemini|cursor|all可以读取 Codex CLI(~/.codex/sessions)、Gemini CLI(~/.gemini/tmp/<hash>/chats)和 Cursor(state.vscdb,通过sqlite3命令行读取,尽力而为)的本地日志,用同一套报表和浪费检测。Cursor 无法计费(显示n/a),Gemini / Cursor 缺少 token 记录时按字符数 /4 估算并以~标出。--budget 20在状态栏显示今日花费与日预算,80% 变黄、100% 变红;ccledger today打印同样的数字。ccledger compare对比前后两段时间(默认近 7 天 vs 之前 7 天)的浪费率、每会话 token、缓存命中率、每会话花费;compare --mark "改了 CLAUDE.md"先打标记,之后compare --mark看改动前后的差别。
npm i -g claude-code-ledger   # 安装后命令是 ccledger
ccledger                      # 总览
ccledger context              # 哪些文件 / 命令占着上下文最烧钱
ccledger advise >> CLAUDE.md  # 把发现变成规则
ccledger watch                # 开在旁边实时看当前会话
ccledger report               # 单文件 HTML 报告
ccledger advise --claude-md --out CLAUDE.suggestions.md   # 带证据的规则建议
ccledger compare --mark "规则上线"                          # 打标记,之后 compare --mark 看前后对比
ccledger today --budget 20    # 今日花费 vs 日预算
ccledger sessions --agent all # Claude Code + Codex + Gemini CLI + Cursor 一张表
context $ 是工具结果的上下文成本:一条结果进入上下文后,会话里之后每一次 API 调用都要为它付一次缓存读取,直到压缩为止。calibrate 用 Claude Code 自己记录的花费校准估算单价。Stop hook 配置见上文 Stop hook 一节。
License
MIT