
claude-dev-workflow
v1.22.0
Published
Per-project installer for the ticket-driven dev workflow — /dev-task, /dev-bug, /dev-done as Claude Code skills, against YouTrack or GitHub Issues.

Maintainers
 ayhid
Readme
dev-workflow
Ticket-driven development for Claude Code, for teams and solo developers who already run their work through an issue tracker. Installed per project, tracker-agnostic (YouTrack or GitHub Issues), with no global state.




Ticket-driven development against your issue tracker, YouTrack or GitHub Issues, as fifteen Claude Code skills. It installs per project: no skill is registered globally, so they exist only in repos that use a tracker.
| Skill | What it does |
| ------------- | ------------ |
| /dev-init | Probes the repo, asks what it cannot infer, verifies the credentials, writes .dev-workflow.json. |
| /dev-task | The front door. Takes an issue ID or a plain sentence and routes to the step the work is at: /dev-file when there is no issue, /dev-plan when there is no plan, /dev-split when the plan has independent parts, /dev-build to build. |
| /dev-file | Turns a sentence into a filed issue of any configured type: orients in the code, asks for what is missing in rounds you can stop after any of, checks for duplicates, drafts in the project's language with falsifiable acceptance criteria, files on approval. Ends at the ID; starts nothing. |
| /dev-plan | Agrees what done means and how to get there: restates the criteria against a stated bar, picks the repo, proposes the approach with its independent parts named, and posts the plan on the ticket, where the next session reads it back. Edits no file, creates no branch. |
| /dev-split | Turns a plan's independent parts into work units filed as sub-issues of the ticket, each with its own criteria and a Depends on: line, in the order they can be built. Starts nothing. |
| /dev-build | Builds it: moves the ticket, checks it out in a worktree, and dispatches a builder subagent in the background to implement against the agreed criteria — the session orchestrates, verifies with evidence, and delivers the way the project delivers; it never builds. A split ticket has its ready units built in parallel, one builder per unit in its own worktree, landed a wave at a time; auto chains the waves under direct delivery on one approval. |
| /dev-tdd | The red/green/refactor loop /dev-build hands off to at implementation: one agreed criterion at a time, a test confirmed to fail for the intended reason before any production code, then a refactor while green. On by default, tdd.enabled: false to switch it off. |
| /dev-bug | The front door for something broken: parses the symptom, investigates the likely code path to a suspected area, and hands it to /dev-file to file as the project's defect type. Never fixes. |
| /dev-done | Re-reads the ticket, verifies each criterion with evidence, runs the checks, then lands the work the way the project delivers: pull request, or straight onto the base branch. |
| /dev-review | Three adversarial passes over the branch diff, each with a different payload: one blind pass that never sees the ticket, one hunting the input that breaks it, one auditing code against intent and intent against itself. Findings sorted into fix-the-code, fix-the-spec, out-of-scope. Never edits, never lands. Findings contract → |
| /dev-lint-rules | Turns the conventions a project only states — in CLAUDE.md, CONTRIBUTING.md, the docs ledger — into rules its own linter can decide, each presented with the count of existing violations it would flag. What no rule can decide it reports separately, as a hook, a claim, or noise. Writes nothing without approval of the batch. Why not a document → |
| /dev-standup | Everything in flight across every configured repo: what merged — or, on a repo delivering without pull requests, what landed on the base branch — what is checked out, what has stopped moving, what is still open on the tracker, and the one thing waiting on you. Phrased per repo in the delivery mode it actually uses. Never writes. |
| /dev-ingest-docs | Reads a brownfield project's existing documentation into a verified map: every claim anchored to the code that proves it, contradictions found, and the questions only a person can settle put to you. Runs in steps across sessions. Never rewrites your docs. |
| /dev-docs-init | Gives a greenfield project the documents it does not have yet — context, architecture, domain, api, ux, operations, testing, security — filled a claim at a time, every line carrying the anchor or the attribution that would show it false. Writes no prose of its own. Reference → |
| /dev-adr | Records an architecture decision while the rejected alternatives are still known, then freezes it. An accepted record is superseded, never edited — a hook enforces it. Reference → |
Nothing installed is project-specific: instance, project, ticket language, repo layout, state
ladder, branch naming, isolation mode and commit convention all come from one
.dev-workflow.json per project.
Documentation site → — a one-page quick start, a use case per situation, recipes, and a reference with real output for every command.
Contents Quick start · How a ticket flows · What the skills refuse to do · Install · Updating · Configuration · Scripts · Keeping states honest · Joining an existing codebase · Measuring what happened
Quick start
Node ≥ 22, and the project you want to set up. jq is needed by the commit hook, and the
GitHub CLI by dev.mjs sync and by every GitHub Issues project. The
1Password CLI (op) is optional.
Install the tool once, then initialise it in any project. One command for either tracker: the first question is which one you use, and that answer decides every question after it.
brew tap ayhid/claude-dev-workflow https://github.com/ayhid/claude-dev-workflow
brew trust --formula ayhid/claude-dev-workflow/claude-dev-workflow   # Homebrew ≥ 6: trust this one formula
brew install claude-dev-workflow           # or: npm install -g claude-dev-workflow

cd your-project
dw init                                    # dw is claude-dev-workflow, for short
Or run it without installing anything: npx claude-dev-workflow@latest, in the project.
GitHub Issues needs no token — gh carries the authentication. The wizard proposes the
repository from your origin remote, checks that gh can write to it, and maps each rung of your
state ladder onto a label the repository really has. It never creates a label: anything missing is
printed as the exact gh label create command to run.
YouTrack needs an instance URL and a token: Profile → Account Security → Authentication → New
token, YouTrack scope. Export it as $YOUTRACK_TOKEN, or give the wizard a 1Password reference.
It then reads the project's real state, type and priority values off the API rather than proposing
names your instance may not have.
[!TIP] The wizard never needs a token pasted into a file: give it a 1Password reference such as
op://Private/youtrack/credentialand it resolves through theopCLI at run time. It also works offline. If the API is unreachable it says so and falls back to typed answers.
To amend an existing config later, or to talk it through rather than click, run /dev-init in
Claude Code instead.
Either way you now have the fifteen skills. Start work:
/dev-task ABC-42
/dev-task the CSV export times out on big accounts     # no issue yet, it files one first
/dev-task agrees the acceptance criteria with you and waits for your approval on a plan before it
edits anything.
How a ticket flows
flowchart TD
    A["/dev-task ABC-42<br/>or a plain sentence"] -. "no issue yet" .-> A1["/dev-file<br/>issue filed"]
    A1 --> B
    A --> B["/dev-plan<br/>criteria agreed, plan<br/>posted on the ticket"]
    B -. "independent parts" .-> S["/dev-split<br/>units filed as sub-issues"]
    S --> S1["/dev-build<br/>one builder per ready unit,<br/>landed a wave at a time"]
    S1 --> E
    B --> C["/dev-build → dev.mjs start<br/>worktree or branch<br/>ticket → In Progress"]
    C --> D["commits carrying<br/>the issue ID"]
    D --> E["/dev-done<br/>verify criteria, run checks"]
    E --> F{"delivery.mode"}
    F -- "pr" --> G["pull request opened<br/>ticket → In Review"]
    G -- "merged" --> H["dev.mjs sync<br/>ticket → Done"]
    F -- "direct" --> I["rebase, fast-forward, push<br/>worktree removed<br/>ticket → Done"]
    C -. "session ends" .-> J["dev.mjs resume<br/>worktree back, ticket caught up"]
    J -.-> D
    C -. "giving up" .-> K["dev.mjs abandon<br/>reason recorded<br/>ticket → states.abandon"]
Each ticket is checked out in its own git worktree by default, so starting one never disturbs whatever is already in the tree.
Not every ticket finishes, and not every session does either. dev.mjs resume puts a missing
worktree back and prints what the last session had actually left there — the uncommitted files by
name and the commits already made — then catches a ticket up to the start rung if it is behind.
dev.mjs abandon is the other way out: it records why on the ticket, moves it to states.abandon,
and takes the worktree and branch down. It refuses while there is anything to lose, so the reason
you gave is never the last trace of work you meant to keep.
[!IMPORTANT] Whether finished work goes through a pull request or lands straight on the target branch is configuration, not a decision the model makes. A solo project sets
delivery.modetodirectonce and is never asked again.
Where it lands is configuration too. delivery.base is the branch work is delivered onto, and
branch.base the branch it is forked from; set the first only when they differ, and a project
can fork every ticket from main while merging into develop or a release branch.
What the skills refuse to do
These are deliberate, and worth preserving in any fork.
| Guarantee | Enforced by |
| --- | --- |
| /dev-file and /dev-bug file and stop. They never start the work, edit a file or switch branch, because the session may be mid-task on something else. | The /dev-file skill contract; /dev-bug hands off to it |
| /dev-plan and /dev-split end on the tracker — a plan comment, a set of sub-issues — and touch nothing on disk. Only /dev-build creates a branch, and it does not touch a file before the plan is agreed or close a ticket unasked. | The /dev-plan, /dev-split and /dev-build skill contracts |
| A builder subagent works only in its own worktree: no push, no fetch, no stash, no rebase, no hook bypass, and no command that moves a ticket. The coordinator lands each wave and reconciles once. | agents/dev-builder.md; the commit hook refuses --no-verify; dev.mjs build --land is the one writer |
| /dev-done refuses to close a ticket whose acceptance criteria are unmet or whose suite fails, and reports the gap instead. | The /dev-done skill contract |
| The transition log never leaves your machine, and never fails a ticket transition. | dev.mjs appends one JSON line locally; a log it cannot write produces a line on stderr and the ticket still moves. |
| /dev-standup reports and never writes — not even the sync --apply it suggests. A command run first thing in the morning must be safe to run without thinking. | dev.mjs standup has no write path at all; every fix it names is a command for you to approve. |
| /dev-lint-rules never edits a linter config or a CLAUDE.md without approval of the whole batch, and never invents a linter: a project with no lint setup is told so and told what the standard tool for its language is. | The skill contract, and dev.mjs rules reports what is configured rather than proposing one — a rule that will never run is worse than an absent one, because it looks like coverage. |
| /dev-ingest-docs never rewrites your documentation. It writes only under _dev-workflow/artifacts/ — the survey, and the reorganised draft as a staged tree beside it; applying that draft to your docs is ordinary work you approve file by file. | Neither the survey nor reorg rewrite has a write path outside the payload root, the staged tree says it is generated, and a staged file edited by hand is refused rather than overwritten. |
| /dev-docs-init writes no prose of its own, and never overwrites a document you already have. A generated document it cannot recognise as its own is left alone rather than re-rendered. | renderDocument takes claims and has no parameter a paragraph could be passed through; docs render compares the file against the hash it wrote. |
| An observable claim with no evidence anchor is refused, not stored. An anchor naming a file that is not in the repo is refused too. | lib/ingest.mjs — an unanchored claim is a guess in the voice of a fact, and a map of those reads exactly like one that was checked. |
| dev.mjs abandon refuses while the branch has uncommitted changes or commits the base has not seen, and names each one. --force is the only thing that discards them. | The check runs before the first write, so a refusal really does leave everything as it was found. |
| Nothing bypasses git hooks. No --no-verify, no HUSKY=0. | lib/vcs.mjs refuses to build the argv, so it holds for code added later too. |
| Nothing force-resolves a merge conflict. -X theirs and checkout --theirs discard one side silently. | A rebase conflict aborts, leaves the branch untouched, and says which commits clashed. |
| The installer writes nothing outside _dev-workflow/, .claude/skills/dev-* and .claude/agents/dev-*.md, and merges rather than rewrites the one shared file, .claude/settings.json. That includes your .gitignore. | isOwnedPath in the installer; worktree mode prints the line to add rather than adding it. |
Install
Three routes to the same installer. It lands the workflow in the project every time — the
runtime under _dev-workflow/, the skills under .claude/skills/dev-*, the subagents under
.claude/agents/dev-*.md, the hooks in .claude/settings.json — which is what the project
commits and what its hooks run from. A global binary only puts it there.
| Route | Install once | Then, in each project |
|---|---|---|
| Homebrew | brew tap ayhid/claude-dev-workflow https://github.com/ayhid/claude-dev-workflow, brew trust --formula ayhid/claude-dev-workflow/claude-dev-workflow, brew install claude-dev-workflow | dw init |
| npm | npm install -g claude-dev-workflow | dw init |
| nothing | — | npx claude-dev-workflow@latest |
The formula lives in this repository, so brew upgrade follows every release; brew trust is
Homebrew 6's one-time question for anything outside homebrew-core — scoped to this one formula, not the whole tap. Both installs put two names on
PATH, claude-dev-workflow and dw, for one binary; dw help lists the subcommands: init,
update, update --reconfigure, version.
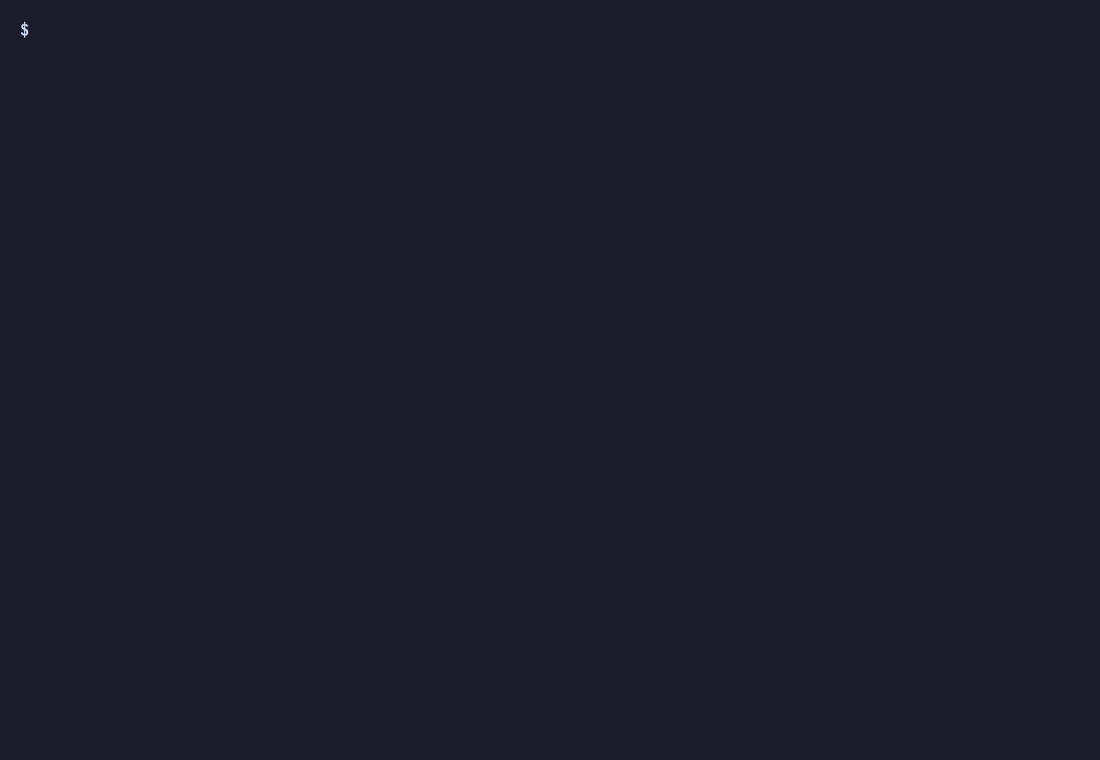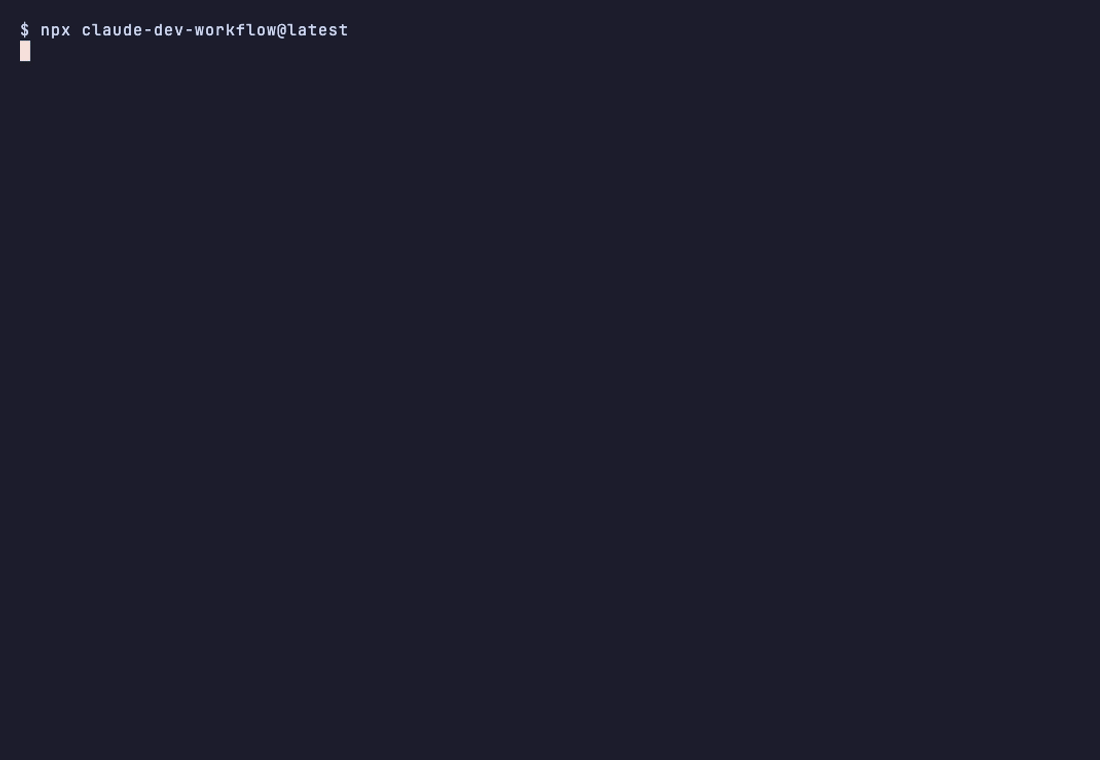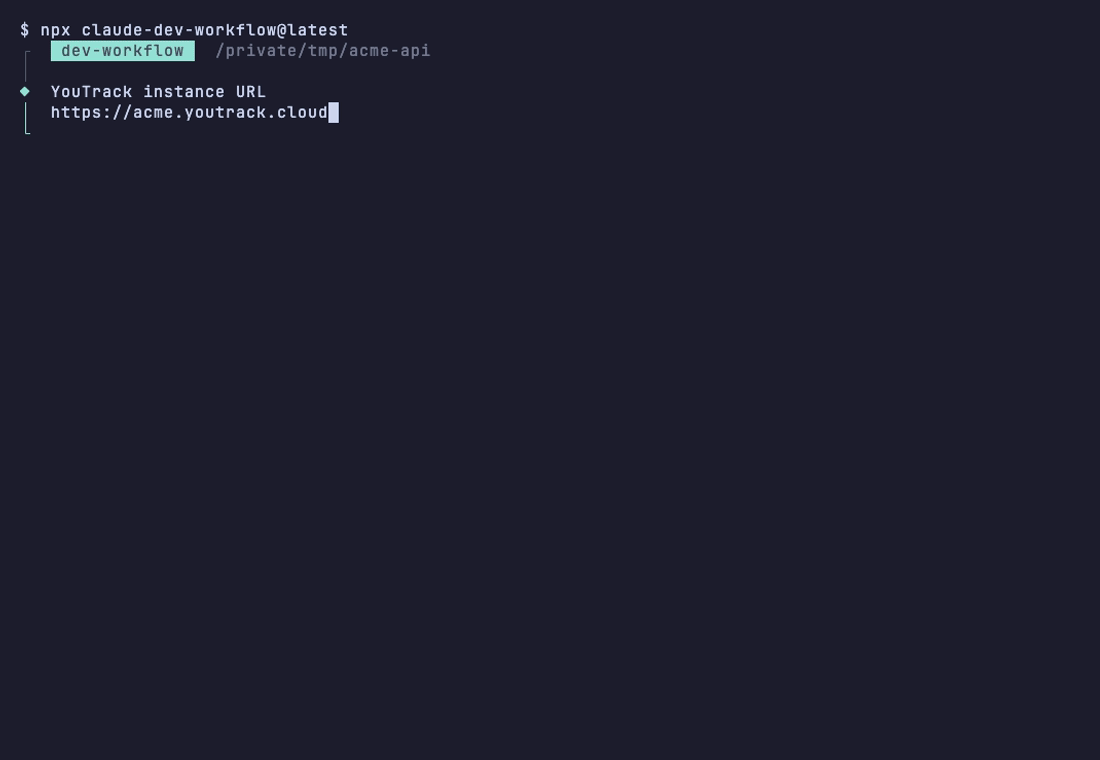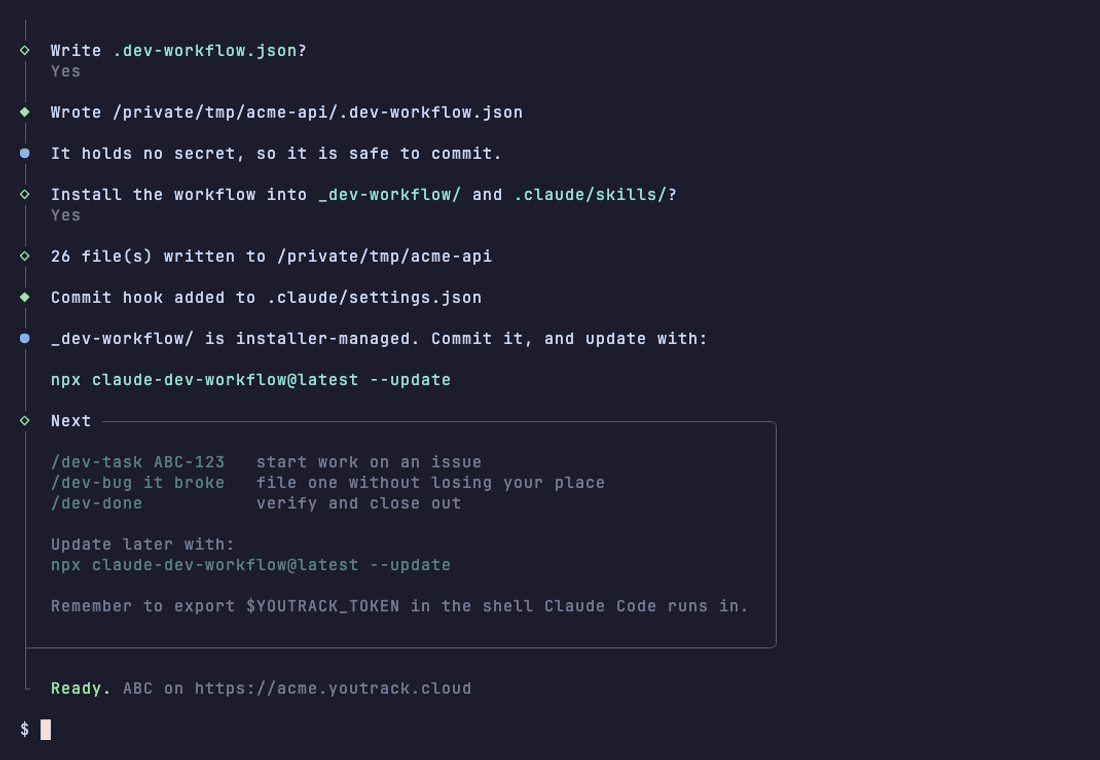
claude-dev-workflow init runs an interactive wizard
(@clack/prompts) that:
- asks which issue tracker the project uses, first, because that answer decides every question
after it — proposing GitHub Issues when
originpoints at github.com; - asks what that tracker needs and verifies it before writing anything: an instance URL and a
token (
$YOUTRACK_TOKENor a 1Password reference) for YouTrack, a repositoryghcan write to for GitHub; - fills the rest from the tracker itself rather than proposing names it may not have — YouTrack's real State / Type / Priority values off the API, or the labels your GitHub repository really carries, mapped onto the rungs of your state ladder;
- scans the working tree for repos, package managers, test and lint scripts, commitlint types and scopes, runtime pins and git remotes, and shows them for confirmation;
- infers whether issue IDs go at the prefix or suffix of a commit subject from the last 50 commits, in whichever ID shape that tracker uses;
- writes
.dev-workflow.jsonand installs the workflow into the project.
It never writes to your issue tracker. A GitHub ladder needs a label per rung, and any your
repository does not have yet are printed as the gh label create commands to run — adding a label
is a visible, permanent change to a repository, and not the installer's to make.
claude-dev-workflow init --dir ../other-project   # target somewhere else
claude-dev-workflow init --print                  # show the config, write nothing
claude-dev-workflow init --force                  # overwrite files you have edited
Every line here also reads as npx claude-dev-workflow@latest <the same flags>: the subcommands
and the flags are two spellings of one path, and neither is going away.
npx github:ayhid/claude-dev-workflow installs from main, one release ahead of npm and slower,
because npm builds the repo's dev toolchain first. Prefer the registry unless you want unreleased
work. Cloned locally, node bin/install.mjs is the same thing again. Released versions are listed
under Releases.
[!WARNING] Always write
@latest. A barenpx claude-dev-workflowre-runs whatever version it first cached, indefinitely, and thegithub:form reuses its cached clone forever.
npx keys its cache on the literal spec string and, on a re-run, only checks whether the tree it
already cached satisfies the range it recorded (2.0.0 satisfies the ^2.0.0 it wrote), so a bare
npx claude-dev-workflow keeps re-running whatever version it saw first, indefinitely. latest is
a dist-tag, so it is re-resolved every time. The github: form is worse still: a git spec carries
no version to compare, so the cached clone is reused forever. Bust it by changing the spec,
npx github:ayhid/claude-dev-workflow#v2.1.0 or a commit sha, rather than by clearing the cache.
(npx --ignore-existing was removed in npm 7.)
What lands in the project
your-project/
  .dev-workflow.json              # your config, edit this
  _dev-workflow/                  # installer-managed runtime; commit it, do not edit
    scripts/  lib/  hooks/
    _config/manifest.json         # version + a sha256 per installed file
  .claude/
    skills/dev-task, dev-file, dev-plan, dev-split, dev-build, dev-tdd, dev-bug,
           dev-done, dev-init, dev-standup, dev-ingest-docs, dev-docs-init,
           dev-adr, dev-review, dev-lint-rules
    agents/dev-reader.md          # the subagents the skills dispatch, one file each
           dev-review-blind.md, dev-review-edge.md, dev-review-audit.md
           dev-builder.md
    settings.json                 # the four hooks, merged in alongside your own
[!IMPORTANT] Commit
_dev-workflow/, and never edit it. Committing it is how your teammates get the same workflow without installing anything. Editing it makes the manifest treat the file as yours, so the next update silently skips it. The installed runtime has no dependencies of its own: there is nonode_modulesunder it, so it works in a Python, Rust or Go project just as well.
Updating
Updating has two modes. Both refresh the files; they differ in what happens to your config.
dw update                 # express: refresh the files, keep your config
dw update --reconfigure   # change config: refresh, then the wizard
dw update --print         # show what would change, write nothing
dw update --force         # and overwrite files you have edited
update installs the version the binary carries and says so — Project v1.18.2 → v1.19.0 — and
it refuses to move a project backwards when the binary is older than the project's copy, naming
the upgrade command for the binary instead. --force downgrades anyway. It also asks the npm
registry whether the binary itself is current: a binary behind the latest release still installs,
but warns and names the newer version rather than reporting the project up to date.
With no global install, each is npx claude-dev-workflow@latest --update … — and that is also the
spelling dev.mjs version prints, since it works on every machine. A global binary updates a
project to its own version, so keep it current (brew upgrade claude-dev-workflow or
npm update -g claude-dev-workflow); dev.mjs version --upgrade only uses the global binary when
it already reports the latest release, and falls back to npx …@latest otherwise.
Express — --update — skips the wizard: it touches _dev-workflow/, .claude/skills/dev-*,
.claude/agents/dev-*.md and the hook entries in .claude/settings.json, and leaves every value
you have answered exactly as it is. It asks one kind of question and no other: a setting this version has that your config
does not. That one was never answered, so it is asked — labelled as new, on its own, with a
default — and appended. Nothing already in .dev-workflow.json is rewritten, reordered or removed,
so a config that has every setting comes out byte-identical.
Where there is no terminal to ask on — CI, a container, a pipe, dev.mjs version --upgrade — it
asks nothing at all: each new setting gets its default and the run prints which keys it added and
with what value, so the choice is in the log rather than lost. Express never blocks on a prompt.
Change config — --update --reconfigure — does the same refresh and then runs the whole
wizard, with your current config as the initial answer to every question. It is the way to update
and change a value in one go.
Re-running init on a configured project does not start the wizard on its own. It looks at what
is there and asks, with the recommendation first: Express when your config already has every
setting this version knows about; Keep the config and add the new settings when it predates
some, naming them; then Change config (the wizard, current values as defaults), Replace the
config (the wizard from scratch — files you edited stay protected unless --force) and
Cancel. With no terminal to ask on, the recommended path is what happens, so a bare init
from a pipe updates the project rather than hanging. A config that is not a JSON object cannot be
kept or diffed: the installer says so and the wizard starts from scratch. Two flags answer the
question on the command line and skip it: --force runs the wizard with your current values as
defaults and overwrites files you edited, and --print prints the config the wizard would write.
Every run ends on one line saying what became of the files and of the config —
Files updated: 27 written. Config: retained., Config: 2 settings added., Config: replaced.
The installer compares each file against the hash recorded at install time: untouched files are
replaced, files you have edited are reported and left alone, and files a newer version no longer
ships are removed. --force overrides that. Your .claude/settings.json is merged, never
overwritten: hooks you added yourself survive, and the entry is not duplicated on a re-run.
Every write is atomic, and an install that fails partway — a permission error, a full disk — puts
back every file it had written or removed before reporting the error, so the manifest it never
reached is still true and the next run is an ordinary update rather than one stuck behind
--force. There is no backup directory: _dev-workflow/ is meant to be committed, and git is
the backup.
Checking a version from inside a project
node _dev-workflow/scripts/dev.mjs version      # installed vs latest, plus files you have edited
node _dev-workflow/scripts/dev.mjs version --upgrade
version is read-only and exits 0 even with no network: it prints unknown rather than failing.
--upgrade runs the npx line above for you, and refuses if _dev-workflow/ or .claude/skills/
has uncommitted changes, because an update rewrites those files and you need the diff to be legible.
Configuration
The wizard writes .dev-workflow.json at the repo root; /dev-init writes the same file from
inside a session.
[!IMPORTANT]
.dev-workflow.jsonholds no secret.tokenOpRefis a 1Password reference, not a credential, so the file is meant to be committed.
YouTrack needs baseUrl and project; everything else has a working default. On a
localised instance, name the state and assignee fields — they are read by display name, and
État is not State.
{
  "provider": "youtrack",
  "baseUrl": "https://acme.youtrack.cloud",
  "project": "ABC",
  "tokenOpRef": "op://Private/youtrack/credential",
  "youtrack": { "stateField": "État", "assigneeField": "Responsable" },
  "states": { "start": "In Progress", "review": "In Review", "done": "Done" }
}
GitHub Issues has no state field, so the ladder is modelled with labels, which means the label
mapping and an explicit states.ladder are both required. Authentication is the GitHub CLI you
already have.
{
  "provider": "github",
  "github": {
    "repo": "acme/api",
    "labels": {
      "In Progress": "status: in progress",
      "In Review": "status: review",
      "Done": "status: done"
    }
  },
  "states": {
    "ladder": ["Backlog", "In Progress", "In Review", "Done"],
    "start": "In Progress", "review": "In Review", "done": "Done"
  }
}
Full configuration reference → covers every field, grouped by config
block: branch naming and worktrees, the commit convention the hook enforces, delivery modes,
multi-repo routing, credentials and environment overrides. Two worked examples live in
examples/.
Scripts
They are ordinary CLI tools; the skills just call them. The three you will reach for by hand:
node _dev-workflow/scripts/dev.mjs standup                     # the whole board, in standup order
node _dev-workflow/scripts/dev.mjs start ABC-22                # branch or worktree, ticket to in progress
node _dev-workflow/scripts/dev.mjs sync                        # dry run: report state drift
[!TIP] Nothing writes until you ask it to.
landandsyncare dry runs unless given--apply,start --printshows the branch name and path without creating anything, and the installer's
Each command below is prefixed with node _dev-workflow/scripts/dev.mjs.
| Command | What it does | Needs |
| --- | --- | --- |
| config [--json] | prints the effective config | HTTP only |
| rules [--json] | linters configured, languages nothing lints, conventions only written down | nothing |
| fetch ABC-22 | the issue as markdown, comments included | HTTP only |
| update ABC-22 state start | moves it along the ladder | HTTP only |
| update ABC-22 state done @/tmp/c.md | moves it, with a comment (literal or @file) | HTTP only |
| update ABC-22 comment "note" | comment only | HTTP only |
| update ABC-22 raw "Type Bug Priority Major" | a backend-native command, YouTrack only | HTTP only |
| create --dup-check "slug 500 router" | open issues matching keywords; reports only, never files (exits 1 only when the search itself cannot run) | HTTP only |
| create "Summary" @/tmp/body.md Bug Major | scans open issues for a duplicate first, then files the issue and prints the new ID on stdout | HTTP only |
| create "Summary" @/tmp/body.md --allow-duplicate | files even though the scan matched, and says what it matched | HTTP only |
| create "Summary" @/tmp/body.md Bug --template bug_report.md | names which of several repo templates the body must satisfy | HTTP only |
| create --templates | the repository's issue templates, filename and name | HTTP only |
| create --template bug_report.md | --template Bug | prints a repo template verbatim, or the shipped default for a configured issue type | HTTP only |
| start ABC-22 [--type T] [--mode worktree\|branch] [--repo PATH] | branch or worktree, ticket to in progress | HTTP + git |
| start ABC-22 --print | just shows the name and path | git |
| resume [ABC-22] | worktree back, uncommitted files and commits so far, ticket caught up | HTTP + git |
| resume ABC-22 --print | the same report, repairing nothing | git |
| abandon ABC-22 "why" | records the reason, walks the ticket back, removes the worktree and branch | HTTP + git |
| abandon ABC-22 "why" --force | the same, discarding uncommitted changes and unmerged commits | HTTP + git |
| land | dry run: how this work would reach the base branch | git + GitHub CLI |
| land --apply | opens the PR, or rebase + fast-forward + push | git + GitHub CLI |
| land --apply --criteria first-pass | the same, recording whether the criteria passed first time | git + GitHub CLI |
| assess | greenfield or brownfield, decided by what code and docs exist | git |
| ingest scan | next | read | record | answer | emit | absorb existing documentation, one step at a time | git |
| reorg triage | classify | shortlist | detect | resolve | map | rewrite | adrs | which documents are records of a moment (by rule, before they are read), what each document still is, which two overlap, what only a person can settle, the reorganised draft as a staged tree, and the intent claims as proposed decision records | git |
| standup [--since 3d] [--stale 7d] | what merged (or landed, on a direct repo), what is in flight, what is stale, what is next | HTTP + git + GitHub CLI |
| sync | dry run: report state drift and stranded labels | git + GitHub CLI |
| sync --apply --since 14d | applies it, over a 14-day window | HTTP + git + GitHub CLI |
| sync --deep | also reads commit subjects | git + GitHub CLI |
| status | this checkout: branch, ticket, state, PR, dirty files, next step | git + GitHub CLI |
| status --all | every worktree and ticket in flight, across configured repos | git + GitHub CLI |
| note "what you learned" | appends it to the project's notes file, tagged with the current ticket | nothing |
| note @/tmp/longer.md | the same, from a file | nothing |
| note | where notes live and how many there are | nothing |
| version | installed vs latest, and files you have edited | HTTP only |
| version --upgrade | brings the payload up to date | git |
create runs the duplicate scan itself, on every file: when an open issue matches the summary's
keywords it prints the candidates, exits 2 and files nothing, and --allow-duplicate is the one
flag that overrides it. A backend that cannot search, or a search that fails, warns and files — the
check is never a new way for filing to fail.
create also respects the repository's issue template, which piping a body into gh issue create
otherwise bypasses. It reads .github/ISSUE_TEMPLATE/ from the checkout, falls back to the
tracker's API when the checkout has none, and to a shipped default per issue type when the
repository has none — and says which on stderr every time. A body missing a repo template's
section is refused with the section named and nothing filed; there is no bypass flag, because a
template that does not fit is a template to fix. The shipped defaults require only
## Acceptance criteria, non-empty, and warn about the rest. With several repo templates,
--template <name> picks one — it is never inferred from the type. The template's labels: are
applied on top of the type label and its title: prefixes the summary.
config, fetch, update and create are plain HTTP. start, resume, abandon, land,
standup and sync additionally drive git, and land, standup and sync the GitHub CLI —
standup degrading to the git half rather than refusing when it is missing.
None of them depend on anything outside Node's standard library,
which is what lets _dev-workflow/ sit in a project of any language with nothing to install.
update names the rung, not the state. state start, state review, state done,
state abandon: the same
line works whether the backend moves a State field or swaps a label, so no session ever has to guess
a state name. An explicit ladder state is accepted too, and rejected before anything is sent if it
is not on the ladder. update writes to the issue tracker; version reports on, and optionally
updates, the workflow's own files. They are named a word apart on purpose: upgrade would have sat
one letter from update in the same command table, and a mistyped verb that rewrites 25 files
instead of moving a ticket is not a mistake worth making possible.
update … raw (YouTrack only)
update ABC-22 raw "Type Bug Priority Major" sends a backend-native command. It is gated on the
provider's capabilities, so a GitHub project gets a usable error rather than a mystery.
[!CAUTION] Two behaviours worth knowing, both learned the hard way against the real API:
- The commands API returns 200 for commands it did not apply.
dev.mjs updatealways reads the state back afterwards and prints what it actually found. Trust that line, not the exit code.- Braces mark where a multi-word value ends, they are not general quoting, so only a multi-word value with another field/value pair after it takes them. Both directions bite:
Type {Bug} Priority {X}parses as the single value{Bug} Priorityand 400s, andState {Staging}is rejected outright withexpected: {Staging}. Instances disagree about the last pair in a command — some applyState In Reviewand rejectState {In Review}, some the reverse — sodev.mjs updatetries both and keeps whichever actually moved the ticket. You do not need to know which kind yours is.
Keeping states honest
Transitions rot. A PR merges on a Friday, nobody is in a session, and the ticket sits in review until someone notices. The usual fix is a webhook that fires on merge, but an event that fires while the runner is down is simply lost, and the ticket is wrong forever.
dev.mjs sync reconciles instead of reacting. It asks given what has been pushed right now, where
should each ticket be? and advances whatever has fallen behind:
| Evidence | Target |
| --- | --- |
| an open PR references the issue | states.review |
| a merged PR references the issue | states.done |
| a commit on the base branch references the issue | states.done |
That third row is what makes the reconciler work on a project that does not open pull requests at
all. delivery.mode: direct is the recommended mode for a solo project, and PR evidence about one
does not exist and never will — so before it existed, sync reported "everything is in sync" about
a board where nothing had moved since the day it was filed. A commit reachable from the base branch
has landed, which is the same fact a merged PR carries. On a pr project it covers everything that
bypasses land: a hand-pushed fix, a hotfix, a rebase landing three commits at once, work done
outside a session.
stateDiagram-v2
    state "In Progress" as inprog
    state "In Review" as inreview
    state "Done" as finished
    state "Blocked / Won't Fix" as offladder

    [*] --> Backlog
    Backlog --> inprog: /dev-task
    inprog --> inreview: land --apply opens a PR
    inreview --> finished: sync sees the PR merged
    inprog --> finished: land --apply, delivery.mode direct
    inprog --> finished: sync sees the commit on the base branch
    inprog --> offladder: moved by hand
    offladder --> inprog: moved by hand
    inprog --> Backlog: dev.mjs abandon
The reconciler is what makes that one-way. abandon is the only thing in the tool that walks a
ticket back, which is why the state it walks back to is required configuration
(states.abandon) rather than a guess: nothing else will notice a wrong one. It does not touch
pull requests either — an open PR still referencing the ticket will pull it forward to the review
rung on the next run, so close the PR too, or the walk-back does not stick.
It only ever moves forward along states.ladder, and never touches a state off the ladder: a
ticket parked in Blocked or Won't Fix was put there on purpose, and no reconciler should
second-guess that. Running it twice is a no-op, so it is safe from a hook, a cron, or the top of
/dev-task. Missing a week costs latency, nothing else.
It also repairs the case that looks like nothing. On GitHub the ladder is modelled with labels,
so an issue has two copies of its state — and they come apart: a PR body saying Closes #12 makes
GitHub close the issue at merge, before anything relabels it, leaving status: in review on a
ticket that reads as done. Forward-only movement is the right answer about its state and the reason
nothing was ever fixed. sync now reports that separately and puts the label right:
ISSUE        CURRENT          SHOULD BE        WHY
#12          Done             relabel          labelled "status: in review", but the issue is Done
The repair only ever rewrites labels — it never opens or closes an issue, so it cannot move a ticket by accident. An issue closed as not planned is off the ladder and left alone, and one carrying no ladder label is never backfilled: it never entered the ladder, and labelling it would invent history it does not have. On a tracker that owns its own states there is only one copy and nothing to repair, so this costs a YouTrack project nothing.
It matches PRs to issues through the branch name and PR title, and landed work through the
commit subject, which is where a type(scope): description (ABC-1) convention puts the ID. The
commits it reads are those on delivery.base (falling back to branch.base) — preferring the
upstream then origin copy of that branch over the local one, because a local branch can be
stale, or hold commits nobody has pushed, and neither of those has landed. Merge commits are
skipped: GitHub titles its own Merge pull request #38 from …, and that number is a pull request's,
not an issue's. This scan is local, costs no API call, and is always on.
--deep is the other half and reaches somewhere different: it reads the commit subjects of each PR
whose branch and title named nothing, which finds an unmerged PR on a freehand branch. That
costs one extra API call per PR. What it does not reach is a commit belonging to no PR — no amount
of PR scanning can see one — which is what the base-branch scan is for.
Coverage is bounded by the convention, not the tool: work that names no issue in a branch, a title or a commit subject is invisible to it. If a run reports far fewer issues than you expect, that is the finding. The branch naming has drifted, and the commit hook is what pulls it back.
Requires the GitHub CLI, authenticated. The repo is taken from
repos[].github when set, otherwise from the upstream then origin remote. Set it explicitly
when branches live on a fork but PRs are opened against the parent.
Joining a codebase that already exists
Most projects are not greenfield. There are years of decisions in them, some written down, and some of those no longer true — and the expensive failure is a session confidently reimplementing something that is already there.
node _dev-workflow/scripts/dev.mjs assess # greenfield or brownfield, with every signal shownWhat makes a project brownfield is that there is already something here — code, or
documentation describing it. So the source files, their size and the documentation decide it, and
the history only corroborates. That order is the whole rule: git init on a codebase somebody has
built for years gives one commit, one author and an age of zero, and a verdict that counted those
would call four hundred source files greenfield. History is evidence of activity, never of code.
It proposes and never decides; you confirm, and the answer is recorded as stage.
On a brownfield project, /dev-ingest-docs then reads the existing documentation into something a
later session can trust. The unit is a claim, not a document, and every claim carries its
evidence:
observable— checkable against the tree, and required to carry an anchor (file:line, or the command that shows it). Two of these disagreeing is a contradiction you can locate.intent— why something is the way it is. No amount of reading settles a disagreement between two of these, so those are the questions that get put to you.
That split is what keeps arbitration small enough to survive: the tool asks about what evidence genuinely cannot settle, and nothing else. It runs in steps across sessions — every claim, question and answer is persisted, so a survey can be picked up next week, and a colleague who pulls gets the decisions and not just the map.
It writes to _dev-workflow/artifacts/documentation/ and nowhere else. Reorganising your own docs
is a proposal it hands you, not an edit it makes.
On a greenfield project there is nothing to read, so /dev-docs-init points the same machinery
the other way: it scaffolds architecture, domain, operations, testing and security, and
fills them from the same ledger, one claim at a time. Ingest turns documents into claims; this turns
claims into documents.
The renderer takes claims and nothing else — there is no parameter a paragraph could be passed
through — so a sentence nobody can check is not discouraged, it is unrepresentable. On a two-week-old
project most of what you record will be intent, attributed to whoever said it, and that is the
correct output: six months later a reader can tell which sentences were ever checkable and which
were one person's belief on a Tuesday. dev.mjs docs check is the CI gate once they are real.
Measuring what actually happened
Nothing in a workflow like this remembers. A ticket takes three days or three weeks, gets restarted twice, closes with its criteria met on the first pass or the fourth — and none of it survives the session that did the work.
So every transition to start, done or abandon appends one JSON line to
.dev-workflow.metrics.jsonl, beside your config:
{"at":"2026-08-29T16:20:11.412Z","event":"done","id":"#28","state":"Done","provider":"github","elapsedMs":198011412,"starts":2,"criteria":"first-pass"}It is local: no network, no telemetry, nothing sent anywhere, and it holds no secret.
"metrics": false turns it off. Abandoned tickets are recorded like finished ones, because a log
that counts only successes answers a question nobody asked, and starts is named after what it can
actually see — restarts, not test runs.
Two properties are deliberate. It hangs off one wrapper around setState, so every command that
moves a ticket is instrumented and none of them knows the log exists. And it can never fail a
command: an unwritable or half-written log produces a line on stderr and the ticket still moves.
Format and fields ·
Add it to your .gitignore — every developer appends to it, so a shared copy conflicts on every
merge. The workflow says so the first time it writes the file rather than editing your .gitignore.
Changing this repo? See CONTRIBUTING.md for how to verify a write path, and
CLAUDE.md for the architecture.