
dsh-docintel
v0.3.0
Published
Personal document knowledge base for DeepSeek Harness: add any PDF/Markdown/text file into a local SQLite FTS5 store with page-level locators, search it with Chinese-friendly retrieval, and get page-cited answers from the agent. Web drawer included (v0.2)

Maintainers
 ll-cmyk-so
Readme
dsh-docintel
个人文档知识库插件 for DeepSeek Harness(dsh)。
把工作区里的 PDF / Markdown / 文本文件解析进一个本地 SQLite FTS5 知识库(带页码定位),agent 通过三个工具随时检索、并带页码引用地回答基于你私人资料的问题。
- 零 Python、零外部服务、零配置:
node:sqlite+pdfjs-dist(纯 JS) - 页码级定位:PDF 逐页提取保留真实页码(与 PyMuPDF 对比 ~99% 字符一致),回答可回溯原文
- 中文友好检索:FTS5 trigram(≥3 字词,BM25 排序)+ LIKE 兜底(≤2 字词)双通道
- 开放格式:知识库就是普通 SQLite 文件,任何脚本 / 工具可直接
SELECT读取 - Web 面板(v0.2):侧边栏「知识库」按钮 → 抽屉:搜索 / 结果 / 拖拽上传 / 文档列表
安装
# 在 profile 里加一行依赖(link 到本地目录):
#   "dsh-docintel": "link:/path/to/dsh-docintel"
# 然后:
dsh plugin --profile web add dsh-docintel   # 或直接编辑 package.json + pnpm install
使用
对话中(agent 工具)
| 工具 | 作用 |
|---|---|
| doc_add | 把文件/目录加入知识库(自动解析、分块、去重;内容变化自动更新) |
| doc_search | 检索知识库,返回带文件名+页码/段号+章节+高亮摘要的 top-k 片段 |
| doc_status | 列出已入库文档与知识库位置 |
| doc_delete | 从知识库删除文档(按 id 或文件名;上传的副本一并删除) |
用户:把这份文档入库
agent:→ doc_add path=2025年年度报告.PDF
      → doc_status
用户:这份报告里的现金流情况如何?
agent:→ doc_search query=现金流
      → 「据《2025年年度报告.PDF》第42页:经营现金流为负…」
Web 面板(v0.2)
侧边栏底部「📚 知识库」按钮 → 抽屉:搜索 / 结果 / 拖拽上传 / 文档列表:
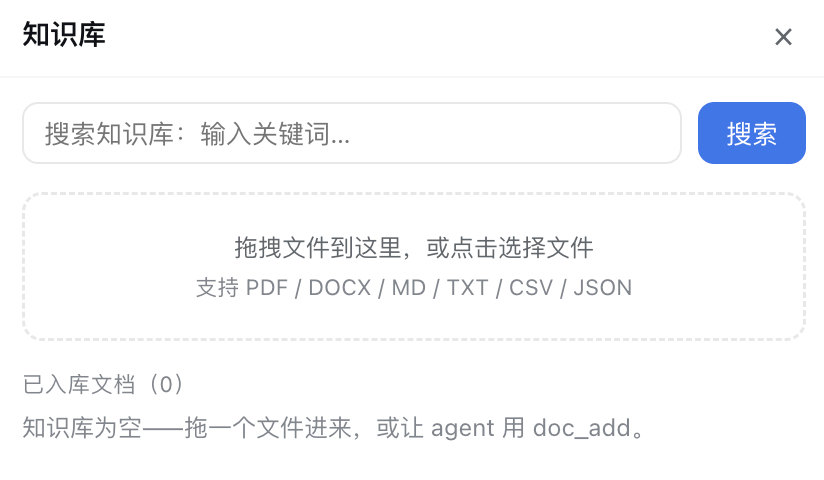
拖文件进去即入库(自动去重/更新);搜索框即查即得(带页码可复制引用);文档按 PDF / 文本分组、可折叠、可过滤,每行 hover 出 🗑 两段式确认删除。
支持的文件
| 类型 | 定位方式 |
|---|---|
| .pdf(文本版) | 真实页码 + 书签切章(扫描版会明确报错,v0.4 支持 OCR) |
| .docx | 标题层级 → 章节路径;段落 → 段号 |
| .md / .markdown | 标题层级 → 章节路径;空行分段 → 段号 |
| .txt / .text / .csv | 段号 |
| .json | 格式化后段号 |
知识库位置与格式
默认 <workspace>/.dsh-docintel/kb.sqlite(可通过配置 storageDir / workspaceRoot 调整)。
-- 其他插件可以直接读:
SELECT d.name, d.kind, d.pages, COUNT(c.rowid) AS chunks
FROM docs d JOIN chunks c ON c.doc_id = d.id
GROUP BY d.id;
中文检索为什么是双通道
SQLite FTS5 的 trigram tokenizer 没有 1–2 字符的索引项(实测两个字的词零命中)。因此:
- 查询含 ≥3 字词 → FTS5
MATCH+bm25()排序(相关度好) - 查询全部为 ≤2 字词 →
LIKE兜底(参数化 + 转义,安全)
两者都是确定性、离线、可解释的——不需要 embedding、不需要向量服务。
架构
┌─ client(v0.2)───────────── Web 面板(React,官方 UI primitives)
├─ host(Node,本插件)──────── doc_add / doc_search / doc_status 工具
│                              + /api/docintel/* loopback REST 路由(v0.2)
├─ store.js ────────────────── SQLite FTS5(docs + chunks 两表)
├─ parser.js ───────────────── pdfjs-dist 逐页页码提取 + 文本快速路径
└─ chunker.js ──────────────── 按字符预算分块,chunk 携带 (page/para/section)
测试
node --test                # 17 个单元测试:解析/入库/检索/去重/更新/删除
npm run e2e                # 真实年度报告 PDF 端到端(解析→入库→中文检索)
npm run test:api           # 面板 API 冒烟(docs/search/upload/delete,起真实 HTTP server)
node scripts/verify-pdfjs.mjs <file.pdf>   # pdfjs 提取质量对比基准
开发备忘:DSH 工具注册的三个坑(已踩平)
给想给 DSH 写工具插件的作者:
ctx.tools.register要求强制性的output声明——缺output整个注册静默失败(工具不会出现在 agent 列表,且无报错)。每个工具必须带output: { schema, render }。- output.schema 必须是标准 JSON Schema 子集:属性内
required: true不被支持(要用对象级required: [...]数组);type只接受单字符串(不支持["integer","null"]数组);nullable 用{ oneOf: [{ type: "integer" }, { type: "null" }] }。 - Node 24 的
node:sqlite的DatabaseSync没有filename属性——要报告库路径请在打开时自己保存。
已知边界(Known Limitations)
诚实声明当前版本的边界,避免预期错位:
- 扫描版/图片版 PDF 暂不支持:会明确报错提示(v0.4 规划 OCR)。只支持有文字层的 PDF。
- 检索是关键词检索(BM25 + trigram),不是语义检索:同义词、语义联想、概念推理做不到;对个人 / 中小体量知识库(数千块级)效果足够且结果可解释。语义检索(向量)在路线图中为可选项。
- 定位为个人 / 团队知识库,不是海量文档系统:短词兜底(LIKE)在文档量极大时(十万级块)检索会变慢。
- 复杂表格提取有限:PDF 表格数字可能混排,DOCX 表格转纯文本保留内容、丢失结构。
- 依赖 DSH 生态:DSH 仍是早期框架,API 可能存在破坏性变更;插件保持零
@deepseek-ai/*运行时依赖以对冲兼容风险。
路线图
- v0.1(已完成):文档入库(PDF/MD/TXT/CSV/JSON)+ 检索 + 状态,页码级定位,中文双通道
- v0.2(已完成):Web 面板——搜索 / 拖拽上传 / 分组列表 / 删除
- v0.3(已完成):DOCX 支持、agent 删除工具、分块优化
- v0.4:扫描件与复杂表格(可选 OCR 档位)
- v0.5:更多格式(EPUB / Excel)与知识导出
- 可选:语义检索增强(向量)
License
MIT