
hekireki
v0.39.0
Published
Hekireki is a code generator from Prisma schema to validation schemas, ORM models and ER diagrams, with a Studio for your schema and its data

Maintainers
 n_akita
Readme
Hekireki
Hekireki reads a Prisma schema and writes what the rest of the project needs from it: validation schemas, ORM models for nine languages, an ER diagram, and seed data. It also comes with a Studio for the schema and its database.
Installation
npm install -D hekirekiQuick start
Add a generator block to schema.prisma and run npx prisma generate. output is required.
generator Hekireki-Zod {
    provider = "hekireki-zod"
    output   = "./zod"
    type     = true  // Export TypeScript types
}
Every generator reads the tables and columns Prisma creates: a model or field without @map
keeps the name it has in the schema ("Todo", "authorId"), and each ORM is told so where its
own convention would say otherwise.
A /// comment on a field can carry a line for one of the validation generators, which uses it
as it is. The prefix says which: @z. for Zod, @v. Valibot, @a. ArkType, @e. Effect
Schema, @t. TypeBox, @j. AJV, @p. Pydantic, @ar. Active Record and @ecto. Ecto.
model User {
    /// @z.email()
    /// @v.pipe(v.string(), v.email())
    email String @unique
}
Generators
The provider of the generator block picks the output. The options are optional unless a
section below says otherwise.
Validation schemas
hekireki-zodwrites Zod schemas.typealso exports the TypeScript type of each schema,relationadds a schema for each relation, andzodpicks the flavour:"v4"(the default),"mini"or"@hono/zod-openapi".hekireki-valibot,hekireki-arktype,hekireki-effect,hekireki-typeboxandhekireki-ajvwrite Valibot, ArkType, Effect Schema, TypeBox and AJV schemas, with the sametypeandrelationoptions.hekireki-pydanticwrites Pydantic models, withrelation.
ORM models
Every ORM generator stores a DateTime as Prisma Client stores it, so that the ORM and Prisma
read each other's rows alike. What that takes differs per ORM, and the sections further down say
what each one does and what is left to the caller.
hekireki-drizzlewrites Drizzle tables. See Drizzle.hekireki-kyselywrites theDBinterface for Kysely. See Kysely.hekireki-sqlalchemywrites SQLAlchemy models.hekireki-djangowrites Django models. See Django.hekireki-activerecordwrites Rails models.localesnames the directory for translated messages. See Active Record.hekireki-gormwrites GORM structs.packageis the Go package name,modelby default.hekireki-sea-ormwrites SeaORM entities.renameAllis serde'srename_allfor the entities and enums ("camelCase", for one). See SeaORM.hekireki-ectowrites Ecto schemas.appis the application module the schemas live under,MyAppby default. See Ecto.hekireki-eloquentwrites Eloquent models.namespaceis the PHP namespace,App\Modelsby default.hekireki-efcorewrites EF Core entities and aDbContext, on PostgreSQL, MySQL and SQLite.namespaceis the C# namespace,Modelsby default, andcontextthe name of the context,AppDbContextby default. See EF Core.hekireki-exposedwrites Exposed tables, on PostgreSQL.packageis the Kotlin package,modelsby default, anddaowrites the DAO classes beside the tables unless set tofalse. See Exposed.
Database and diagrams
hekireki-atlaswrites the schema as Atlas HCL.schemaNameis the schema the tables go in. See Atlas.hekireki-erdraws the ER diagram.outputslists the files to write, one rendering per extension (.md,.dbml,.png,.svg), andthemeislightordark.hekireki-seedwrites the schema module thathekireki.config.tsis typed against. See Seed.
Drizzle
On MySQL, hekireki-drizzle reads and writes a @db.Timestamp column as UTC, and MySQL converts
a TIMESTAMP through the connection's time_zone. Set it to '+00:00' on drizzle's connection,
as Prisma's adapter does on its own, or the two see times that differ by the offset.
On CockroachDB it writes the PostgreSQL schema, for node-postgres, and an Int key with
@default(sequence()) is an identity column, as Prisma makes it. Keep the session's TimeZone at
UTC there, as on PostgreSQL, for a dbgenerated("CURRENT_TIMESTAMP") default to be UTC.
Kysely
hekireki-kysely writes one DB interface, each column typed as the driver of the datasource
reads and binds it: better-sqlite3 on SQLite, pg on PostgreSQL, mysql2 on MySQL. Kysely converts
nothing and runs no hook, so what the types cannot say is the caller's:
- On SQLite a
DateTimeis text, compared as text: write it as Prisma does,date.toISOString().replace('Z', '+00:00'), or=,@uniqueand@@iddo not meet Prisma's rows. ADateTimewithnow()or a literal default is asked for on insert there, as Prisma Client writes it itself: SQLite's own default is other text (CURRENT_TIMESTAMPsorts before Prisma's rows, and Prisma reads the literal as an Invalid Date). - pg and mysql2 read a column without a zone in the process's zone, Prisma in UTC: set pg's type
parsers 1114, 1082, 1115 and 1182 to UTC with
pg.defaults.parseInputDatesAsUTC = true, and give mysql2timezone: 'Z'. MySQL refuses ISO text with aZ; write aDateor MySQL's2030-01-02 03:04:05.678901. @db.Timeand@db.Timetzarestring, the time of day the drivers read.@updatedAtis asked for on insert, optional or not, and must be set on every update.
examples/kysely in the repository runs a schema against Kysely on SQLite.
Django
hekireki-django keeps a DateTime as Prisma Client keeps it:
- A column without a zone is declared with the
UtcDateTimeFieldwritten intomodels.py. It stores the UTC instant (on SQLite Prisma's text,2030-01-02T03:04:05.678+00:00) and reads it back as UTC, aware underUSE_TZ = Trueand inTIME_ZONEunderFalse. A@db.Timestamptzis Django's own field. now()is filled in by the model, in UTC (the UTC date or time on@db.Dateand@db.Time), and a literal default on a date or time column is its UTC date or time.- An
@updatedAton a date or time column stamps the UTC date or time (UtcDateField,UtcTimeField) where Django'sauto_nowwould take the local one. A model with@updatedAtis managed byAutoNowQuerySet, soQuerySet.update()bumps it asupdateManydoes.
Keep USE_TZ = True, Django's default: with False, Django sets a PostgreSQL session to
TIME_ZONE, and a dbgenerated() default such as CURRENT_TIMESTAMP is evaluated in that zone.
Active Record
hekireki-activerecord writes app/models from the schema: application_record.rb and one model
per Prisma model, as a Rails developer would write them (and prisma_date_time.rb where a column
needs it). What Rails works out on its own (table_name, class_name, foreign_key,
inverse_of where the names follow its conventions) is left unsaid; what the schema promises is
written: attribute defaults, enum, timestamps, associations with dependent: from onDelete,
and validations from the columns (presence, uniqueness, length).
A /// @ar. line on a field is a validator (presence, length(maximum: 255)) added to that
field's validates; on a model it is a Ruby line written into the class as it is
(has_secure_password, has_many :tags, through: :post_tags, scope ...). A message or name
given per locale, message: { ja: "...", en: "..." } or @ar.name(ja: "..."), goes to
config/locales/models/<model>/<locale>.yml under the key Rails reads. From app/models that
directory is the application's own; from anywhere else, locales has to name it, relative to
output.
generator Hekireki-ActiveRecord {
    provider = "hekireki-activerecord"
    output   = "../app/models"
}

/// @ar.name(ja: "やること", en: "Todo")
model Todo {
  id        Int      @id @default(autoincrement())
  /// @ar.name(ja: "タイトル", en: "Title")
  /// @ar.presence(message: { ja: "を入力してください", en: "is required" })
  /// @ar.length(maximum: 255, too_long: { ja: "%{count}文字以内で入力してください", en: "must be %{count} characters or less" })
  title     String   @db.VarChar(255)
  completed Boolean  @default(false)
  createdAt DateTime @default(now()) @map("created_at")
  updatedAt DateTime @updatedAt @map("updated_at")

  @@map("todos")
}
# app/models/todo.rb
class Todo < ApplicationRecord
attribute :completed, default: false
validates :title, presence: true, length: { maximum: 255 }
end# config/locales/models/todo/ja.yml
ja:
activerecord:
models:
todo: 'やること'
attributes:
todo:
title: 'タイトル'
errors:
models:
todo:
attributes:
title:
blank: 'を入力してください'
too_long: '%{count}文字以内で入力してください'The tables stay Prisma's to create, so set config.active_record.migration_error = false and
create the test database with prisma migrate deploy.
A DateTime is stored as Prisma Client stores it:
- Every
@updatedAtcolumn is bumped, not only the one aliased toupdated_at. - A column holding fewer than three digits of a second (
@db.Timestamp(0), MySQL's bare@db.DateTime) is sent Prisma's milliseconds for the database to round (precision: 3), where Active Record would cut them off first. - A
@db.Timetzcolumn is read as a time, not a String. Active Record still warnsunknown OID 1266once as it reads the table's columns, before the declared type takes over. - On SQLite every
DateTimecolumn is declared withPrismaDateTime, which writes Prisma's text (2030-01-02T03:04:05.678+00:00) so that comparisons, unique indexes and ordering see both clients' rows alike. On SQL Server a@db.DateTimeor@db.SmallDateTimecolumn is too: it sends milliseconds for the server to round to 1/300 s or to the minute as Prisma's are, where the adapter would round or cut them first. The type is generated intoprisma_date_time.rbbeside the models, so Zeitwerk loads it from wherever it loads them, whateveroutputis. - On SQLite and SQL Server, whose
CURRENT_TIMESTAMPis text of another shape or the server's local time,now()is filled in by the model.
Keep config.active_record.default_timezone at :utc, Rails' default: with :local, a
timestamp column is written in the process's zone and Prisma reads it as UTC.
examples/active-record in the repository runs a fuller schema against Active Record on SQLite,
and is the place to read what each thing becomes.
Ecto
hekireki-ecto writes one Ecto.Schema module per model. A model with a /// @ecto line on it
or on one of its fields also gets a changeset/2:
castof every field it can write;validate_requiredof the required fields Prisma gives no default;- a
unique_constraintfor each@uniqueand@@unique; - a
foreign_key_constraintfor each foreign key; - a
no_assoc_constraintfor eachhas_oneorhas_manywhose rows the database will not let go of (RestrictorNoActionon delete, which Prisma makes of a required relation that names neither), so a refused delete is an error on the association.
Each constraint is named as the database reports it: Prisma's <table>_<columns>_key and
_fkey, cut to the database's limit in bytes as Prisma cuts them, or the map: given. On SQLite
a unique key takes the name Ecto derives itself, and a foreign key gets no constraint, since
SQLite names none when it refuses a row; with relationMode = "prisma" there is no foreign key in
the database to report.
A /// @ecto. line on a field is an Ecto.Changeset function that takes the field first, written
without the field: validate_length(max: 50), or validate_required(message: "...") for a
message of the field's own. unique_constraint(message: "...") on a @unique field and
foreign_key_constraint(message: "...") on a foreign key give the constraint its message. On a
relation field, assoc_constraint (the side with the key) puts a missing row's error on the
association, and no_assoc_constraint(message: "...") on a has_one or has_many gives a refused
delete its message (or asks for one where the database cascades).
On a model, a line is a step of the pipeline written as it is (validate_confirmation(:password));
unique_constraint([:a, :b], message: "...") on the fields of a @@unique gives that constraint
its message; cast(empty_values: []) hands its options to the changeset's cast; and a bare
/// @ecto asks for the changeset with nothing added. With empty values of the model's own, ""
is a value, as it is to the column, so the required fields are checked by a validate_not_null
written into the module, which counts only nil as missing (validate_required would count ""
too); a field's own validate_required line keeps Ecto's meaning. Ecto has no association for a
foreign key of several columns, so the constraints of one are foreign_key_constraints with the
error on the relation's name.
model User {
  id    Int     @id @default(autoincrement())
  /// @ecto.validate_required(message: "名前を入力してください")
  /// @ecto.validate_length(max: 50, message: "%{count}文字以内で入力してください")
  name  String
  age   Int?
  email String? @unique
}
def changeset(user, attrs) do
user
|> cast(attrs, [:name, :age, :email])
|> validate_required([:name], message: "名前を入力してください")
|> validate_length(:name, max: 50, message: "%{count}文字以内で入力してください")
|> unique_constraint(:email, name: "User_email_key")
endA DateTime is kept as Prisma Client keeps it, through modules written alongside the schemas:
PrismaDateTime holds the instant in UTC in milliseconds (on SQLite the text Prisma writes,
2030-01-01T09:00:00.000+00:00, so an equality or a range finds Prisma's rows), PrismaDate a
@db.Date and PrismaTime a @db.Time or @db.Timetz. now() and @updatedAt are
timestamps() calls of those types. An optional @updatedAt is stored as null on insert only when
given by Ecto.Changeset.force_change/3, as a struct's nil is no change. On PostgreSQL and MySQL
the module's documentation names the session time zone a @db.Timestamptz, @db.Timetz or
TIMESTAMP column needs.
examples/ecto in the repository runs a schema against Ecto on SQLite.
Exposed
hekireki-exposed keeps a DateTime as Prisma Client keeps it, with no conversion through the
JVM's zone: an Instant bound and read as the UTC instant, to the millisecond (a finer value is
truncated, as a JavaScript Date holds it, in every native type), the UTC date of a @db.Date, the
UTC time of a @db.Time, and a @db.Timetz at offset zero.
now(), literal defaults and every @updatedAt are filled in by the client on a DAO or DSL
insert, and the DAO bumps @updatedAt on update. A DSL Table.update has no such hook, so set it
there yourself: it[updatedAt] = Instant.now().
pgjdbc sets the session to the JVM's zone, so open the connection in UTC, as Prisma's is, for a
dbgenerated("CURRENT_TIMESTAMP") default or now() in SQL:
Database.connect(url, setupConnection = { it.createStatement().use { s -> s.execute("SET TIME ZONE 'UTC'") } })EF Core
hekireki-efcore stores a DateTime as Prisma Client does, whatever its DateTimeKind: the UTC
instant (a Local value converted), read back as Utc, in Prisma's text form on SQLite, and
now() filled in by EF Core rather than by the database's clock. It takes Npgsql's legacy
timestamp behaviour to be off.
On MySQL, compare a @db.Time column with a parameter rather than a constant:
MySql.EntityFrameworkCore writes a constant TimeSpan as TIME '03:04:05', without its fraction.
SeaORM
hekireki-sea-orm writes one entity per model into a directory, with a mod.rs and a
prelude.rs. A DateTime is kept as Prisma Client keeps it:
now(),@updatedAtand a literal default are filled byActiveModelBehavior::before_save, in UTC with milliseconds, so the crate needschronoandasync-traitbesidesea-orm.- On SQLite every
DateTimeis aPrismaDateTime(written intoprisma_date_time.rs), which binds Prisma's text,2030-01-02T03:04:05.000+00:00: filter withColumn::At.eq(PrismaDateTime(instant)), not a bareDateTimeUtc, which sqlx writes without the.000of a whole second. - On PostgreSQL and MySQL a
DateTimeis aNaiveDateTimein UTC,@db.TimestamptzaDateTimeWithTimeZone, a MySQL@db.TimestampaDateTimeUtc.@db.Timetzis refused: sqlx has no type to read it into.
examples/sea-orm in the repository runs a schema against SeaORM on SQLite, PostgreSQL and MySQL.
Atlas
hekireki-atlas writes the tables as Prisma Migrate makes them, so that atlas schema diff
against a database Prisma made has nothing to change. Its schemaName is public unless given
(main on SQLite): on MySQL, where the schema is the database, give the database's name.
Studio
npx hekireki studio
npx hekireki studio --url file:./dev.db
Your schema and database in the browser, on SQLite, PostgreSQL and MySQL. Without flags, Studio
reads the schema of prisma.config.ts, else ./prisma/schema.prisma or ./schema.prisma, and
listens on port 5555.
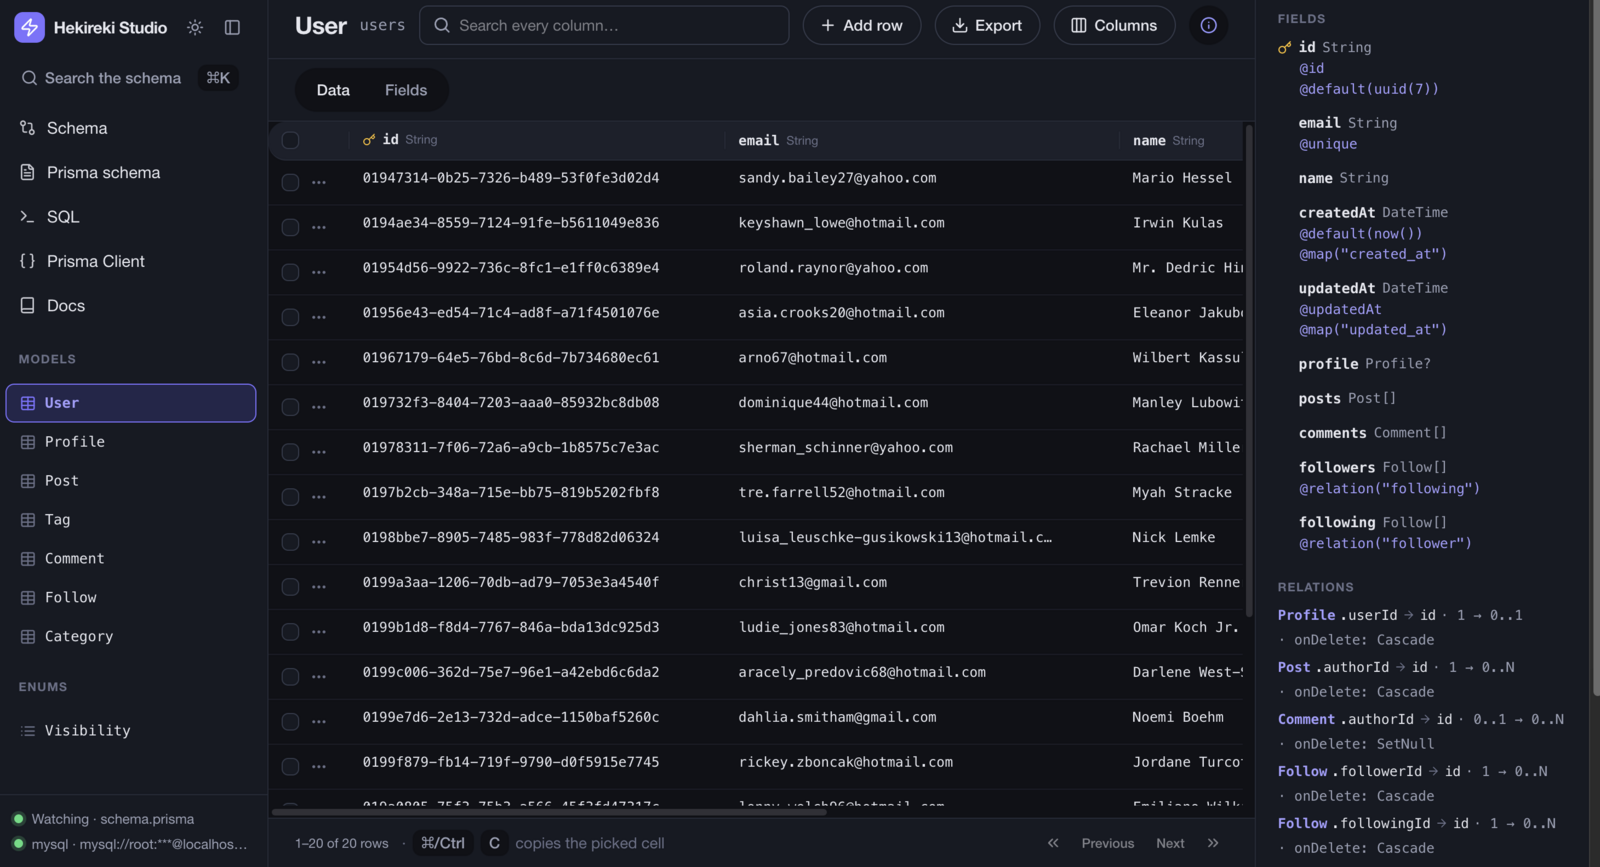
Browse the rows of each model: search, add, edit and export them.
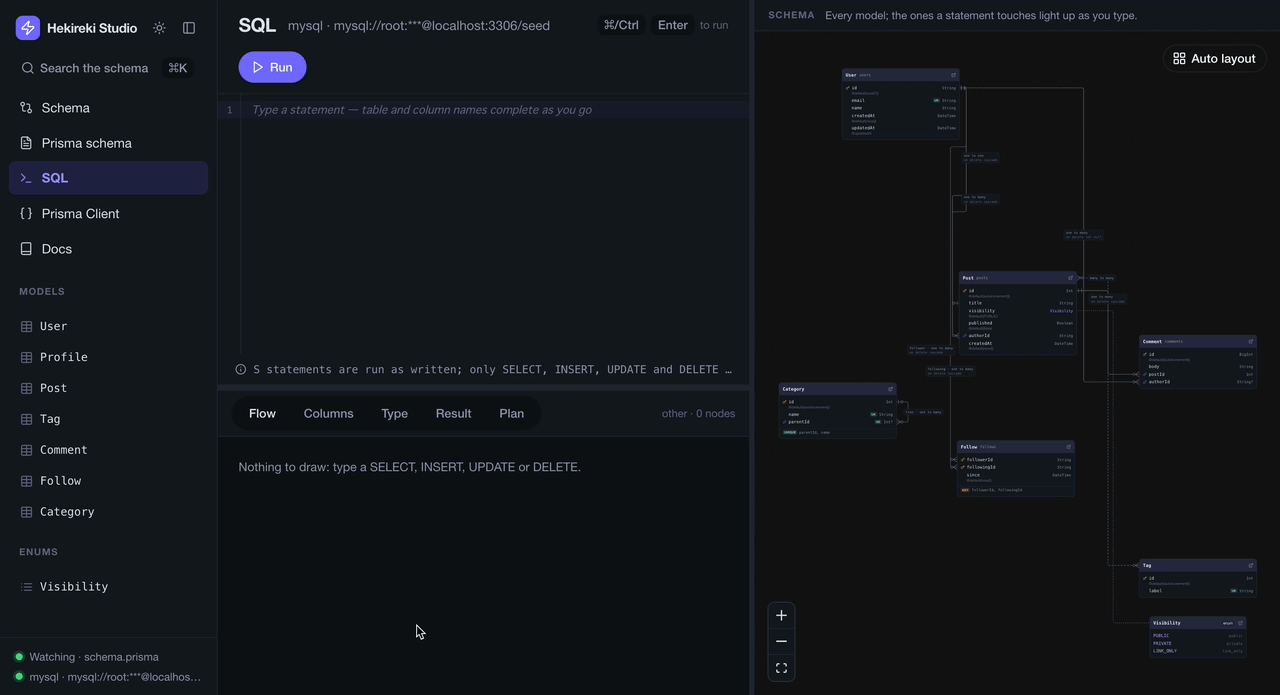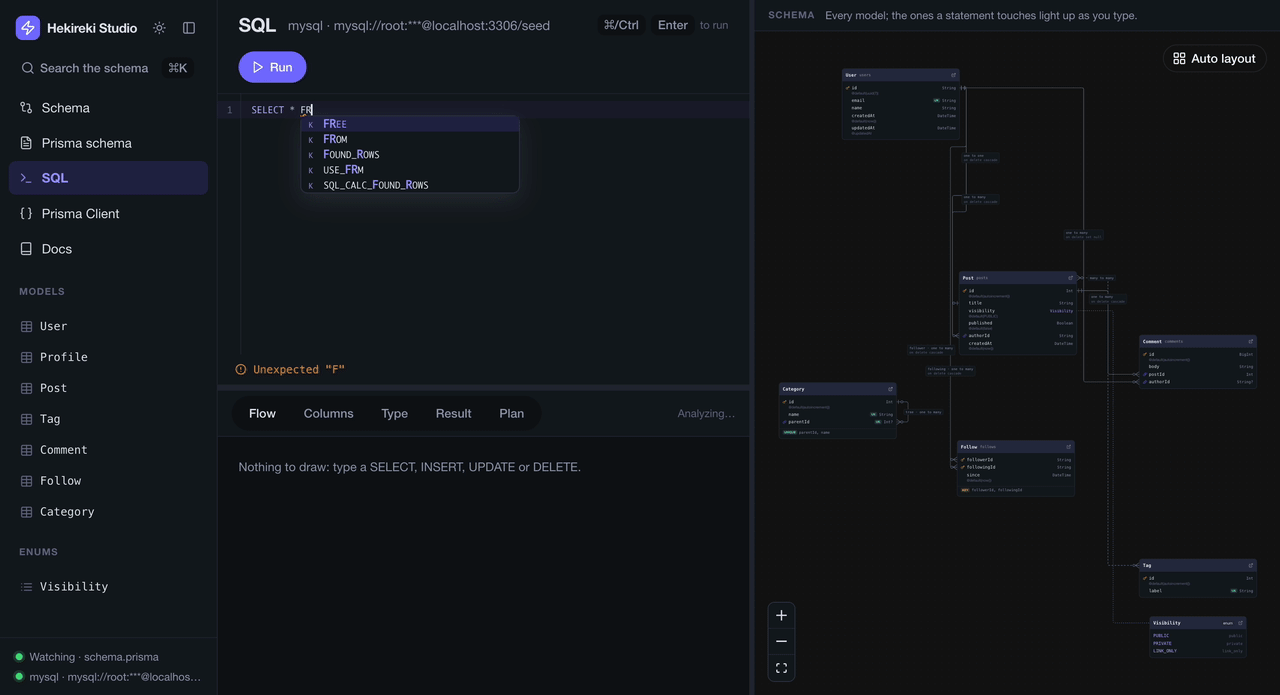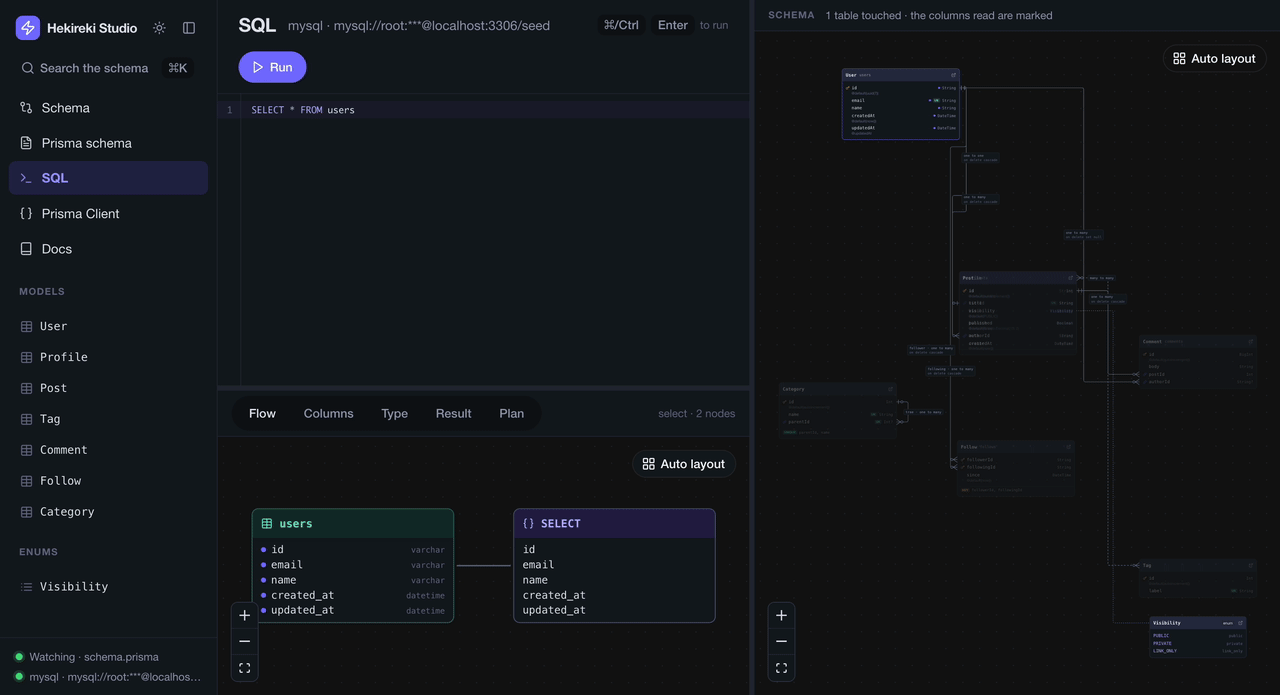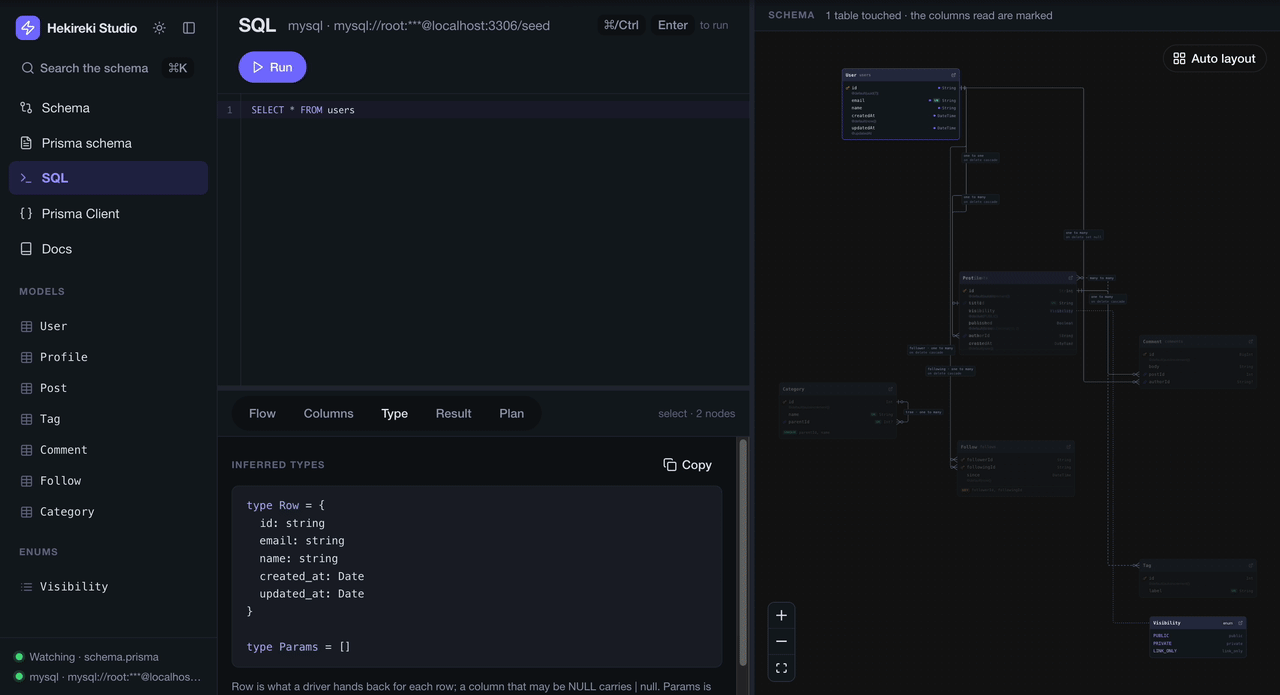
Run SQL with completion from the schema. The ER diagram marks the tables a statement reads, and the result comes with the TypeScript types of its rows.
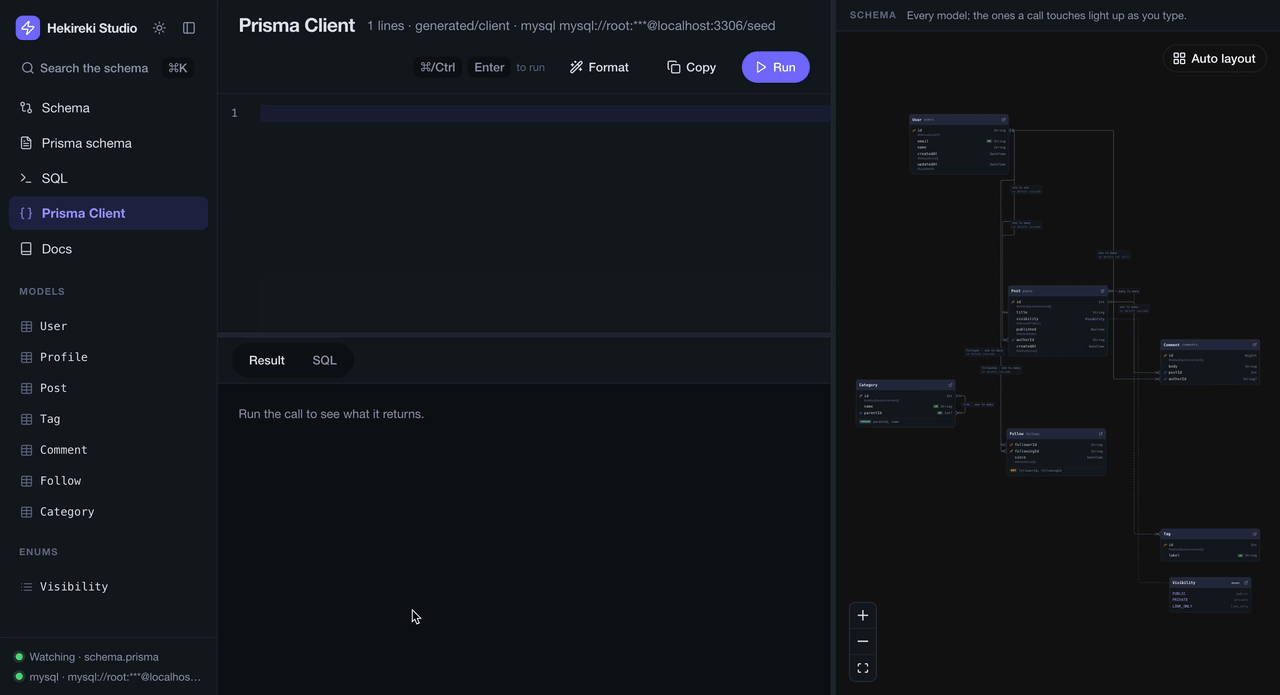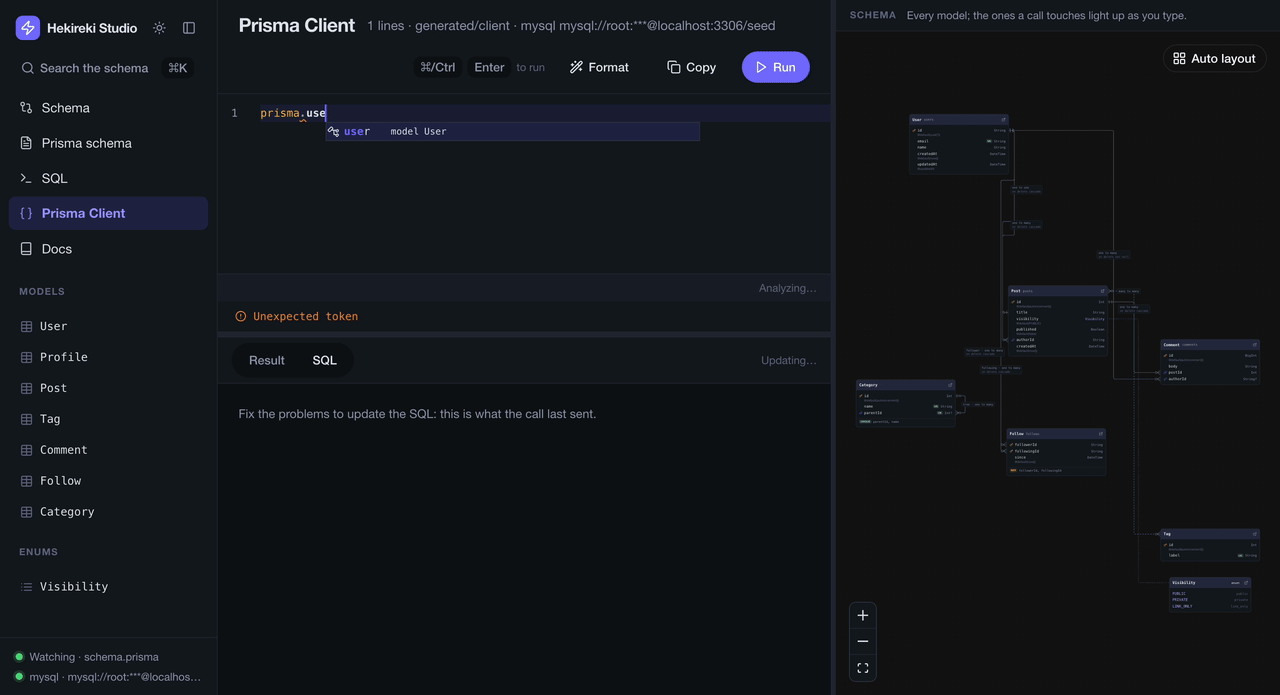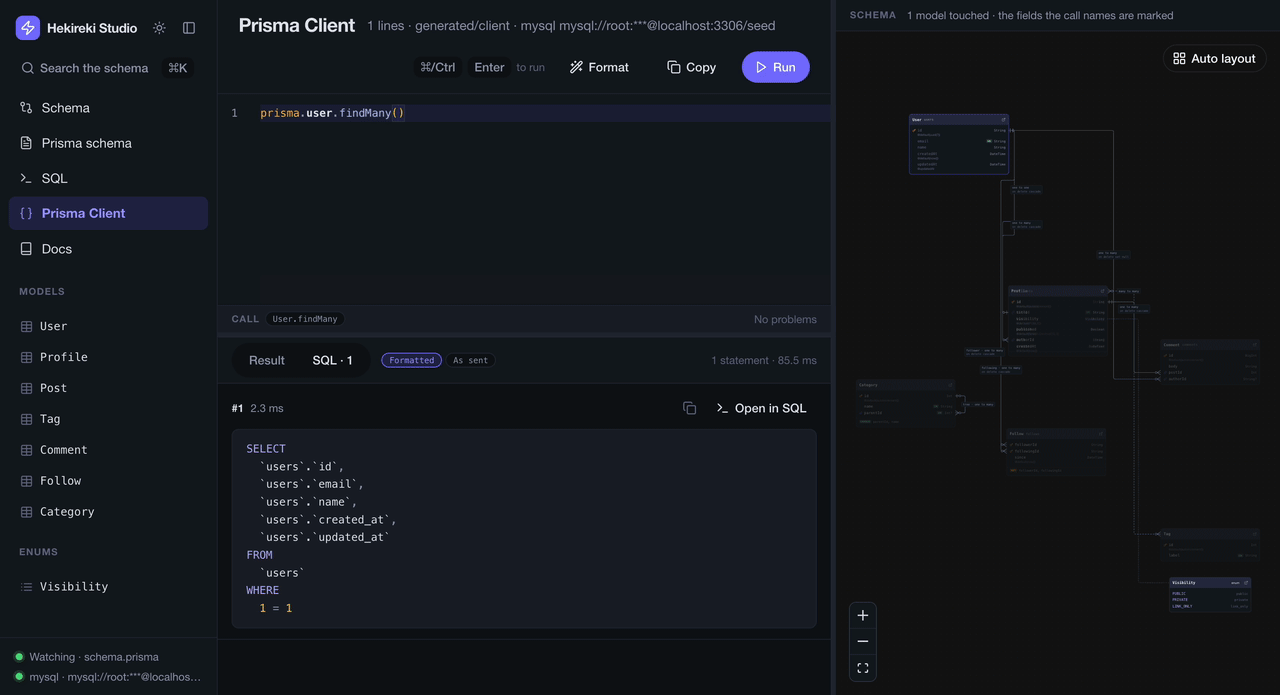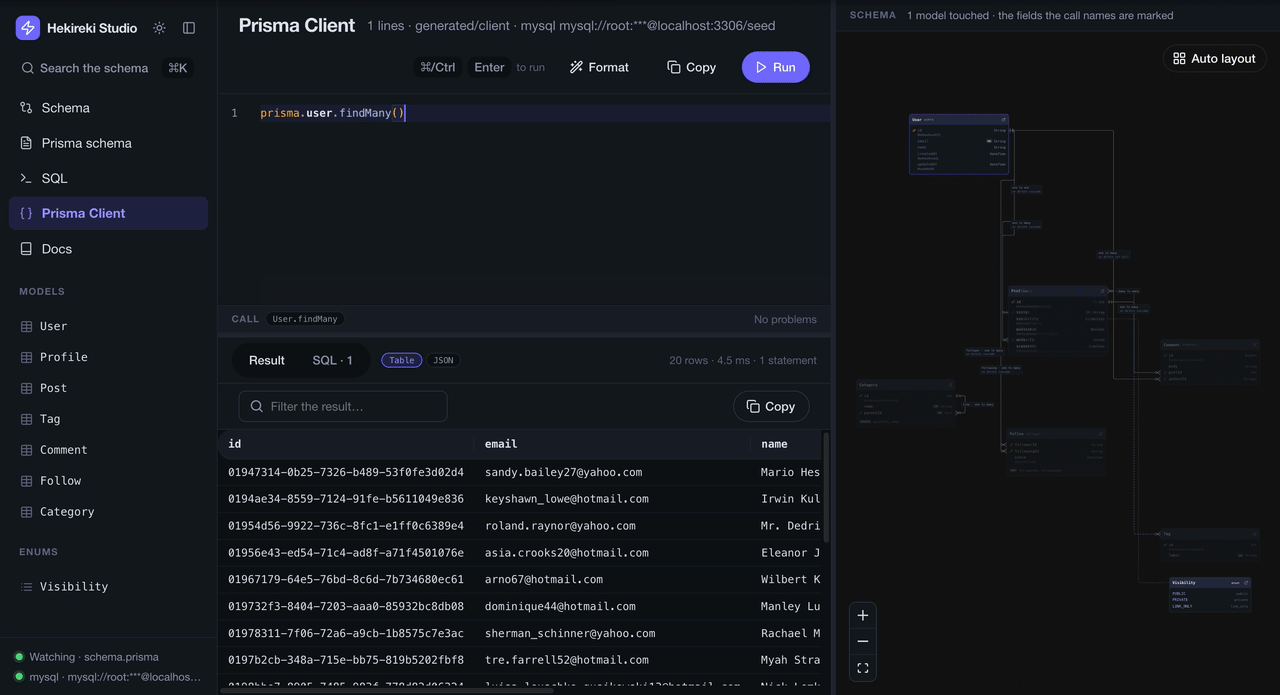
Try Prisma Client calls and see the SQL each one sends.
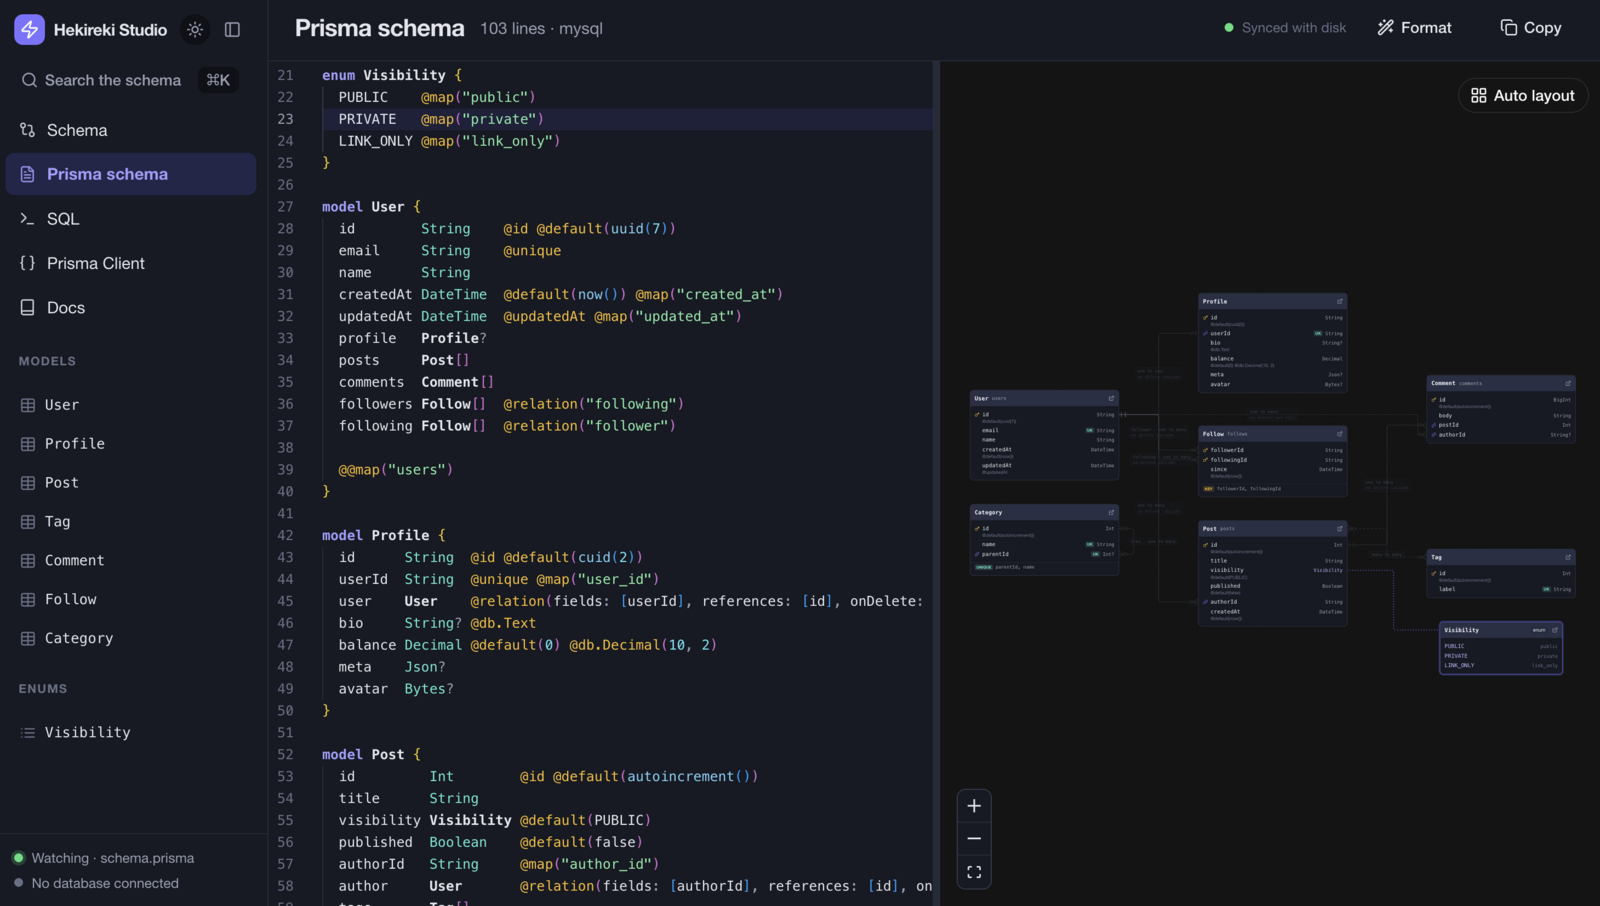
Edit the schema beside its ER diagram, which follows the file as it changes.
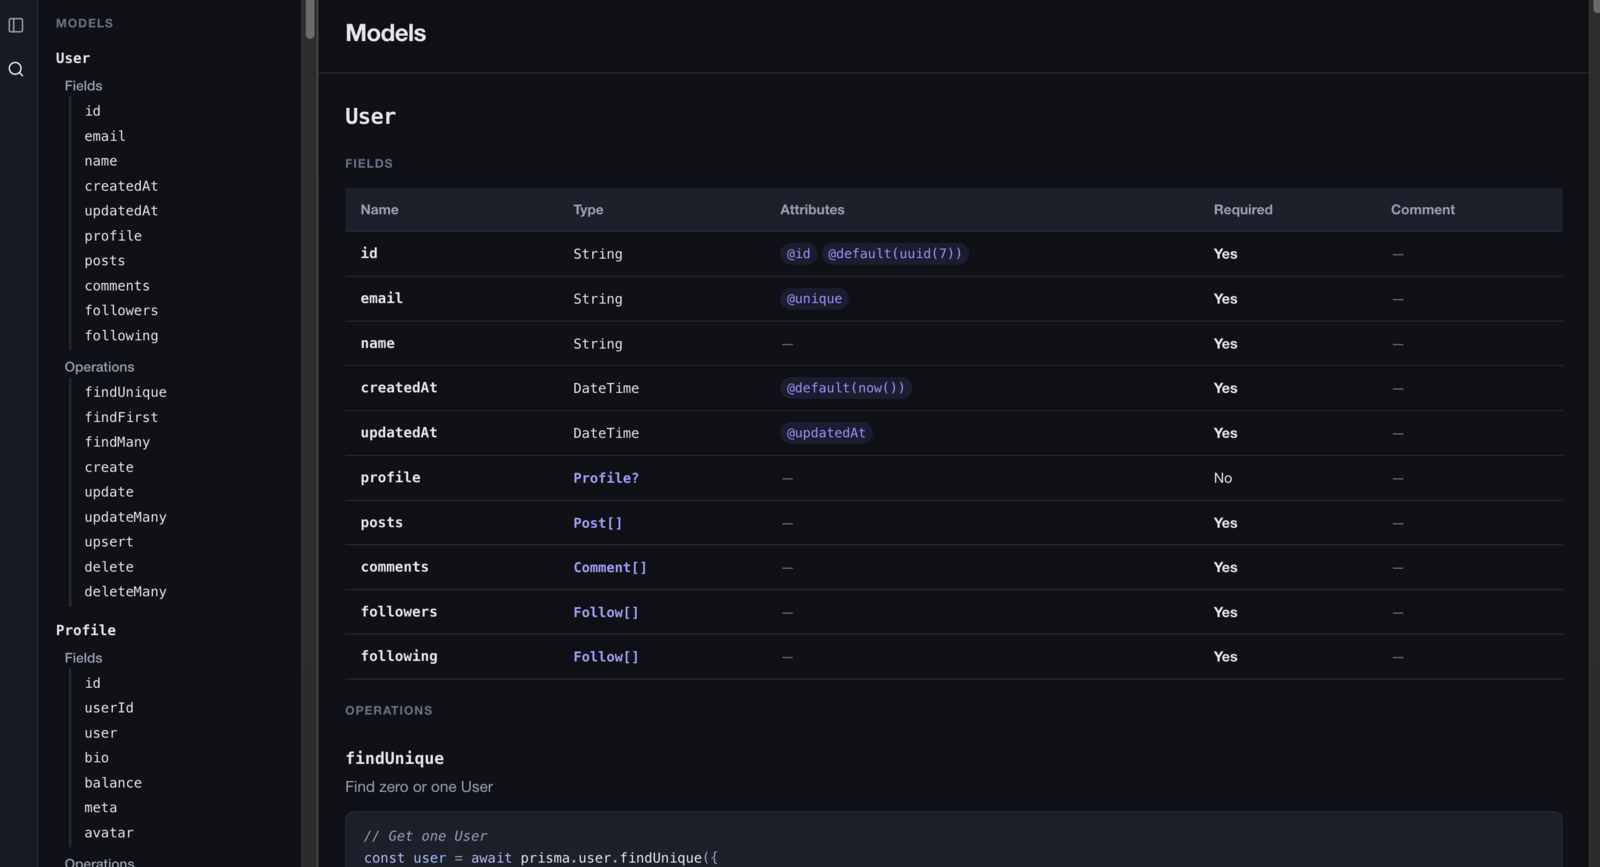
Read the docs of every model: its fields, and an example of each operation.
Seed
npx hekireki seed                    # Through the project's Prisma Client
npx hekireki seed --sql seed.sql     # Or as a SQL script
The hekireki-seed generator writes a schema module; hekireki.config.ts imports it and is typed
against it, so each model's fields are known as the config is written.
// hekireki.config.ts
import { defineConfig } from 'hekireki'

import { schema } from './prisma/seed/schema' // written by the hekireki-seed generator

export default defineConfig(schema, {
  seed: 42,
  models: {
    User: { count: 100, fields: { age: { min: 18, max: 65 } } },
    Tag: { data: [{ label: 'prisma' }, { label: 'effect' }] },
  },
})
Every foreign key, unique constraint and enum is respected.
License
MIT. See LICENSE.