
hippocamp
v0.2.15
Published
Local Git-backed memory for AI agents.

Maintainers
 guillaumegay
Readme
Hippocamp


Agent memory, made simple.
Plain Markdown in your own Git repo, shared by all your coding agents, like Claude Code and Codex. One command to install. No API key, no database, no server to run.
Every session starts by waking up from it, and every decision an agent records is a commit you can read, diff, and revert. Open source (MIT).
npx hippocamp@latest installThis installs Hippocamp into every supported agent it finds and creates your memory repo, ~/.lagoon. Restart your agent and it starts each task by waking up from memory.
Build and own your agents' memory
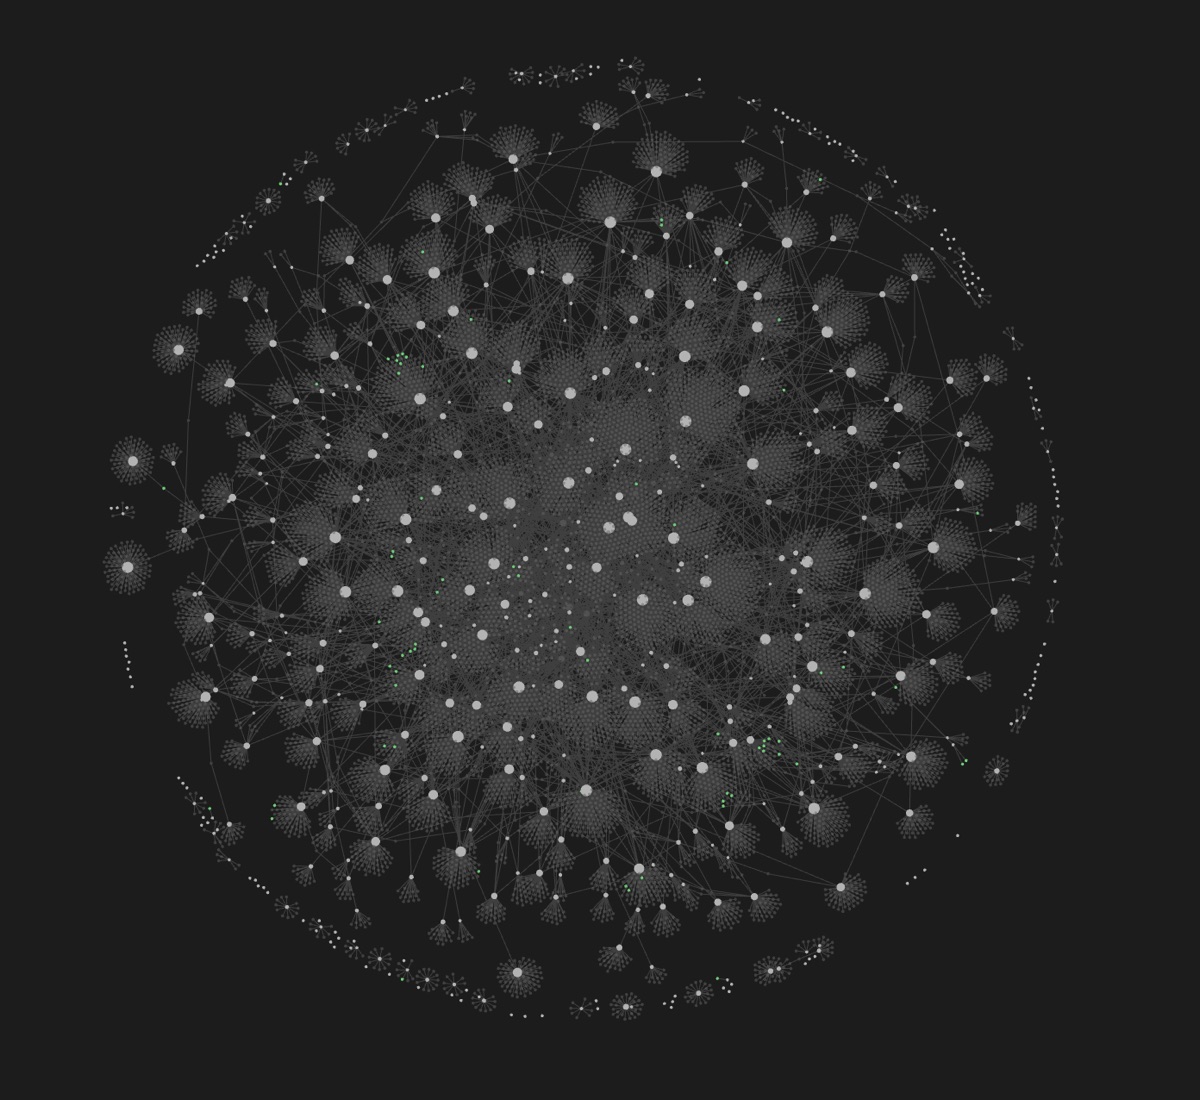
A real ~/.lagoon opened in Obsidian. Every dot is a Markdown note your agents wrote, linked by keywords. It's plain files in your own Git repo, so you can open them in any editor.
Why Hippocamp?
- Written by the agent itself. The agent doing the work records what is worth keeping, in its own words. Events stay as written. Optional Dream reviews recent events to update and compact the two summary files, promoting supported lessons through a pull request you review.
- One memory for every agent. Claude Code, Codex, and your other agents share the same repo. Built-in memory, like Claude Code's or Codex's, stays inside one tool.
- History you can audit. Every memory is a Git commit. Roll back a bad memory like bad code.
- Files you own. Plain Markdown, readable without any UI, synced across machines with your normal Git credentials.
- Nothing to sign up for. No vendor that can change terms or shut down.
Compared with other memory tools
| | Hippocamp | Mem0 | Zep | Graphiti | Letta Code | Basic Memory | Claude Code / Codex built-in | | --- | :---: | :---: | :---: | :---: | :---: | :---: | :---: | | Agent agnostic (MCP server) | ✅ | ✅ | ✅ | ✅ | ❌ | ✅ | ❌ | | Plain files you own | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | | Auditable history | ✅ | ✅ | ❌ | ❌ | ✅ | ❌ | ❌ | | No extra account, API key, or model | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | | Syncs through your own Git | ✅ | ❌ | ❌ | ❌ | ✅ | ❌ | ❌ | | Always free | ✅ | ❌ | ❌ | ❌ | ✅ | ✅ | ✅ | | Open source | ✅ | ✅ | ❌ | ✅ | ✅ | ✅ | ❌ |
Results
Reproducible with the scripts in this repo.
| | Hippocamp | Reference | | --- | ---: | ---: | | Right memory in top 5, LongMemEval-S (470 questions) | 90.5% | BM25: 91.4% | | Text returned per search | 5.9k chars | Whole sessions: 65.5k | | Answer accuracy, Claude Sonnet 5, top 10 results | 77% | Correct sessions given directly: 90% | | Unrelated questions that return nothing (our own test set) | 10 / 10 | | | Work continuity, 21 real Claude Code sessions, checks passed | 100% (20 / 20) | Claude Code native memory: 96% (25 / 26) | | Work continuity, same 21 sessions in Codex, checks passed | 86% (24 / 28) | Codex native memory: 86% (24 / 28) |
Work continuity tests memory on real engineering work, not chat questions. A real Claude Code or Codex agent works through 21 coding sessions on two small projects. Early sessions establish facts, such as a rejected library, a pinned Node version, a blocked vendor, a parked branch or a user preference. Later tickets only go well if the agent remembers them, and the prompts never mention memory. A blind judge grades 28 checks from the diff and the tool calls. Each arm is installed the way a developer has it.
The same Hippocamp server, plugged into either agent with no changes, keeps up with that agent's own memory. In Codex, whose built-in memory stored almost nothing, Hippocamp's memory covered 57% of the planted facts against 4%. Hippocamp uses about 25–45% more tokens per session. This is one run per arm, so the differences are within noise. Every grade, diff and judge prompt is published in docs/results.
Full tables, method, and limits: docs/results.md.
Docs
- Setup: install options, the Lagoon repo, a private remote, configuration
- How it works: memory layout, MCP tools, memory rules
- Dream: optional overnight memory updates and compaction as a reviewed pull request
- Results: evals and how to rerun them
- Development: commands and releases
License
MIT