
multi-tasks
v4.0.1
Published
Multi-process task scheduling based on Node.js cluster, with crash resume and failed-task restart support

Maintainers
 zhanglei923
Readme
multi-tasks
Run large batches of tasks in parallel across multiple Node.js processes, with zero dependencies. Progress and results are stored on the file system, so an interrupted run (crash, power outage) can resume where it left off.
New in 4.0.0 — task_storage: 'aof' (append-only file), now the default: memory-grade speed with full resume — a killed run simply continues where it left off. One config field; set task_storage: 'file' for the classic per-task-file layout. See Task storage modes.
Install:
npm install multi-tasksQuick start:
let multiTasks = require('multi-tasks').multiTasks;

//your tasks, as a plain array
let tasks = [];
for(let i = 0; i < 50; i++){
    tasks.push({name: `task-${i}`});
};

multiTasks({
    initialTasks: tasks,
    //process one task and return its result (a plain value or a Promise)
    processTask: (task, helper) => {
        return `done: ${task.name}`;
    },
    taskRootFolder: './my-tasks', //progress and results live in ./my-tasks/demo
    taskId: 'demo',
    numberOfWorkers: 3, //worker processes running in parallel
    autoCloseAfterCompletion: true, //exit the process when all tasks are done
    onFinish: (report) => {
        console.log(`${report.succeeded} succeeded, ${report.failed} failed`);
    },
});
Results are appended to <taskRootFolder>/<taskId>/results/succ.json, failures to results/errors.json — one JSON line per task ({"subid": ..., "data": ...}); other storage modes lay them out differently (see Task storage modes). A runnable copy of this example lives in examples/example0.
Results and errors:
processTask may return a plain value or a Promise:
let processTask = (task, helper) => {
    let {taskCount} = task; //0-based index of this task

    return new Promise((resolve, reject) => {
        setTimeout(() => {
            resolve({data: `task${taskCount} complete`});
        }, 100);
    });
};
A failing task never stops the batch — its error is captured and saved to results/errors.json (in memory mode it is kept in the master's memory and surfaced via onFinish), the rest keep going:
let processTask = (task, helper) => {
    let {taskCount} = task;

    if(taskCount === 3) throw 'exception'; //a thrown value is persisted as-is
    if(taskCount === 4) return Promise.reject({err: 'a test error'}); //a rejection value is persisted as-is
    if(taskCount === 5) aaa = bbb; //a ReferenceError is captured too

    return {data: 'succ'};
};
Creating new tasks dynamically:
//scenario: crawl a paginated API — each page tells you if there is a next one
let processTask = async (task, helper) => {
    let page = await fetchPage(task.url); //your logic here

    if(page.nextUrl){
        //a discovered next page becomes a new task;
        //the pages are finite, so the queue always drains on its own
        helper.createNewTasks({url: page.nextUrl});
    };

    return {url: task.url, items: page.items};
};

multiTasks({
    initialTasks: [{url: 'https://api.example.com/items?page=1'}], //start from the first page
    processTask,
    taskRootFolder: './my-tasks',
    taskId: 'api-crawl',
    numberOfWorkers: 3,
    //keep autoCloseAfterCompletion false (the default) while tasks may still be created
});
The point: new tasks come from work discovered while processing, and discovery stops when the data runs out — no artificial bound needed. Keep autoCloseAfterCompletion at its default (false) so workers stay alive for late-arriving tasks.
Timeouts and retries:
multiTasks({
    initialTasks: tasks,
    processTask,
    taskRootFolder: './my-tasks',
    taskId: 'demo',
    numberOfWorkers: 3,
    taskTimeout: 30000, //a task that overruns 30s fails with a timeout error
    maxTaskRetries: 2, //auto-retry a failed task (worker crash, processTask error, or timeout) up to 2 times
});
Resuming an interrupted run:
Just re-run the same code — multiTasks(config) detects the existing task folder and auto-resumes, re-running only the stuck tasks:
multiTasks(config); //same command, same config as the interrupted runOr point initialTasks at the task folder — same effect:
multiTasks({...config, initialTasks: '/myworks/my_scan_tasks/my-task'});Or resume from the task folder alone — the config (including processTask) is restored from task_config.json:
multiTasks.resume({taskFolder: '/myworks/my_scan_tasks/my-task'}); //taskFolder: the full path of the existing task folderNote: functions revived from task_config.json must be self-contained (no outer-scope variables; require(...) inside the body) — otherwise pass them again; fields you pass always win:
multiTasks.resume({taskFolder: '/myworks/my_scan_tasks/my-task', processTask});Retrying failed tasks:
Resume an interrupted run and also re-run the tasks that failed:
multiTasks.retry_fails({taskFolder: '/myworks/my_scan_tasks/my-task'});Restarting from scratch:
Throw away all progress and results in a task folder and re-run all the initial tasks (the config, including processTask and initialTasks, is restored from task_config.json):
multiTasks.restart({taskFolder: '/myworks/my_scan_tasks/my-task'});Unlike retry_fails (which re-runs only the failed tasks), restart re-runs all the initial tasks — tasks created dynamically via helper.createNewTasks are not restored and will not be re-run. Fields you pass override the saved config and are written back into it; the same self-contained-function note as in Resuming applies.
Broadcasting events between workers:
multiTasks({
    initialTasks: tasks,
    processTask: (task, helper) => {
        helper.setListener('task-done', (payload, meta) => {
            console.log(`worker ${meta.fromWorkerPid} says: task ${payload.seq} done`);
        });
        helper.emit('task-done', {seq: task.seq}); //broadcast to all workers
        return {data: 'succ'};
    },
    taskRootFolder: './my-tasks',
    taskId: 'demo',
    numberOfWorkers: 3,
});
System events:
Send events from a worker to the master with helper.emitSys:
multiTasks({
    initialTasks: tasks,
    setSysListener: (event, payload, meta) => {
        console.log(`sys event "${event}" from worker ${meta.fromWorkerPid}:`, payload);
    },
    processTask: (task, helper) => {
        helper.emitSys('task-started', {seq: task.seq});
        if(task.fatal){
            helper.emitSys('TERMINATE_ALL_WORKERS'); //built-in event: stop everything
            return;
        };
        return {data: 'succ'};
    },
    taskRootFolder: './my-tasks',
    taskId: 'demo',
    numberOfWorkers: 3,
});
Task storage modes:
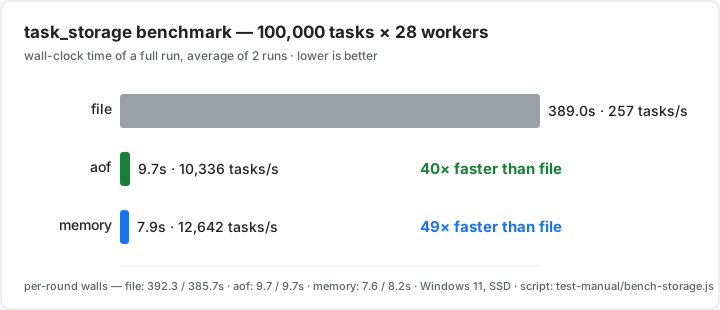
By default (aof mode) you get near-memory speed with full resume. The classic file mode (per-task files on disk, live-monitorable) is one config field away. The three modes side by side:
| Mode | Time (100k tiny tasks) | resume / retry_fails / restart | Results readable from disk | Live monitoring (multi-tasks-monitor) |
|---|---|---|---|---|
| file | 389s (~6.5 min) | ✓ | ✓ | ✓ |
| aof (default) | 9.7s | ✓ | ✓ | ✗ |
| memory | 7.9s | throw | ✗ | ✗ |
Same API for all three — one config field:
multiTasks({
    initialTasks: tasks,
    processTask,
    taskRootFolder: './my-tasks',
    taskId: 'demo',
    task_storage: 'aof', //'aof' (default) | 'file' | 'memory'
    onFinish: (report, helper) => {
        helper.foreachResult((count, task, result, succeeded) => {
            //collect / batch-insert / write out your results here
        });
    },
});
Reading results: in aof mode results stream into results/succ.json/results/errors.json — one JSON line per task; mid-run a task may appear on several lines (last one wins), at the end each file holds exactly one line per task. In memory mode results never touch disk — collect them in onFinish(report, helper) via helper.foreachResult (or foreachSuccResult/foreachErrorResult). Neither mode creates the classic per-task directories (progress/, logs/, results/succ|errors/) — in aof mode the task folder holds just task_config.json, .sys, and the aggregate result files; in memory mode it holds only task_config.json and .sys.
Caveats of memory mode:
- Worker crashes: without
maxTaskRetries, a crashed worker's in-flight task is lost for good (noresumeto pick it up). - Dynamic tasks: tasks sent via
helper.createNewTasksbut not yet applied are lost if the master is killed. And keepautoCloseAfterCompletionat its defaultfalsewhen workers create tasks dynamically — in-transit tasks can miss the dispatch window and the workers get closed early.
Caveats of aof mode:
- Results: result files can lag a moment behind completion during the run; a resumed run always ends with a complete set.
Real-Time Monitoring
Monitor your running tasks with multi-tasks-monitor — see its npm page for full details.
Quick start (requires multi-tasks >=3.2.0 and task_storage: 'file' — aof/memory runs have nothing to monitor): once your multi-tasks run has started, the startup log prints the monitor command with the task folder path already filled in — just copy-paste it into another terminal:
npm install multi-tasks-monitor
npx multi-tasks-monitor --task-dir "D:\tasks\multitasks20260806..." --port 3777
API:
Entry functions:
multiTasks(config)— run tasks; auto-resumes if the task folder already exists orinitialTaskspoints to one.multiTasks.resume(config)— resume from the task folder alone ({taskFolder}); the config is restored fromtask_config.json, fields you pass override it and are written back. Usually you don't need this: re-runningmultiTasks(config)auto-resumes.multiTasks.retry_fails(config)— same asresume, and also retries the failed tasks.multiTasks.restart(config)— wipe the task folder's progress and results and re-run from scratch ({taskFolder}). All previous progress and results are deleted.
Config options:
initialTasks— an array of task objects; a function returning the array (or a Promise of it); or a task folder path string to resume from.- Function form, for performance: every worker process re-runs your entire entry script, so top-level task-generation code (scanning folders, querying a database, ...) runs once per worker. Wrapped in a function it is called only once, in the master process, and workers never call it. The (resolved) value must be an array, otherwise the master exits with an error. Only the resulting array is saved — not the function — so the self-contained-function note under Resuming does not apply to it.
processTask(task, helper)— required; return a result or a Promise with result. Results are appended as JSON lines toresults/succ.json(infilemode stored as per-task JSON files underresults/succ; inmemorymode kept in the master's memory and iterated viaonFinishhelpers); if a result is not JSON-serializable, the task still counts as succeeded (a placeholder is stored) and a warning shows up in the command line.taskRootFolder— the task run folder (named bytaskId) is created under this directory.taskId— task folder name undertaskRootFolder.numberOfWorkers— how many worker processes run in parallel; a number, or a percentage string of CPU cores like"50%"(default).taskTimeout— optional, milliseconds; an overdue task fails with a timeout error.maxTaskRetries— optional, max times a failed task is auto-retried.workerPriority— optional, OS scheduling priority for worker processes:'low' | 'below_normal' | 'normal' | 'above_normal' | 'high', or a nice number (integer -20~19). Lower priority keeps the machine responsive while a long batch occupies all cores; invalid values throw.progressBar—trueby default: shows a live progress bar in the terminal; setfalseto fall back to plain log output.worker_status_poll_ms— worker status poll interval in ms; default2000;0(orfalse) disables the worker status table;truemeans the default rate.task_storage—'aof'(default) |'file'|'memory': where task states and results are kept; see "Task storage modes". Note: onresume/retry_fails/restartthe folder's own mode always wins (an old folder is never re-interpreted under the new default), and passing atask_storagethat contradicts it throws.autoCloseAfterCompletion— settrueto kill workers and exit the process when no tasks are left; default isfalse, i.e. workers stay alive waiting for dynamically created tasks.shouldTerminate(info)— returntrueto terminate the whole process. If it throws, the error is logged and the task is dispatched anyway (treated as "don't terminate").setSysListener(event, payload, meta)— optional, handle custom system events (sent viahelper.emitSys) on the master;metahasfromWorkerIdandfromWorkerPid.onFinish(report, helper)— called once after all workers exit (only whenautoCloseAfterCompletionistrue; termination viashouldTerminateor'TERMINATE_ALL_WORKERS'exits without calling it).reportsummarizes the run:{ taskId, taskFolder, startTimestamp, endTimestamp, cost, total, succeeded, failed, failedTasks, succButSaveFailed, workers }—costis the run duration in ms (a resumed run measures only the current round);failedTaskslists the failed tasks' subids;succButSaveFailedcounts tasks that ran fine but whose results could not be JSON-serialized;workersis{ count, crashed }— the configured worker count and how many workers crashed and were replaced.helperwalks every persisted task result:helper.foreachSuccResult((count, task, result) => {})— iterate all succeeded results (results/succ.json; infilemoderesults/succ/);countis a 0-based index,taskis the original task object (nullif the original task can't be recovered),resultis the value returned byprocessTask(undefinedwhen the task returned nothing; a{type: 'result_serialize_error', message}placeholder when the value could not be JSON-serialized).helper.foreachErrorResult((count, task, err) => {})— iterate all failed results (results/errors.json; infilemoderesults/errors/);erris the persisted error object as-is ({ex}/{subTask, exception}/{type: 'timeout', ...}/{type: 'worker_crash', ...}). A non-Errorrejection value that is not JSON-serializable is persisted as{ex: {type: 'unserializable_error_value', ...}}.helper.foreachResult((count, task, result, succeeded) => {})— iterate all results regardless of outcome (succeeded first, then failed;countruns continuously across both);succeededistruefor succeeded results andfalsefor failed ones (whereresultis the persisted error object).- In
filemode the iteration order is unspecified; inmemoryandaofmodes the helpers iterate in completion order.onFinishruns synchronously at the very end and the master process exits shortly after it returns — don'tawaitinside it.
Other options:
taskFolder— full task folder path; only used byresume/retry_fails/restart.
Task helper (the helper object passed as the second argument of processTask):
helper.createNewTasks(tasks)— create new tasks dynamically while processing.helper.emit(event, payload, option?)— broadcast an event to all workers (relayed by the master, best-effort);option.includingMedefaults totrue— pass{includingMe: false}to exclude the sender. Payload must be JSON-serializable.helper.setListener(event, handler)— listen for broadcast events; one handler per event per worker process (re-registering replaces it), so calling it insideprocessTaskis always safe;handler(payload, meta)getsmeta.fromWorkerIdandmeta.fromWorkerPid. Broadcasts are runtime-only messages — not persisted, not replayed on resume.helper.emitSys(event, payload?)— send a system event to the master (consumed by the master itself, not relayed). Built-in event:'TERMINATE_ALL_WORKERS'force-kills all workers and exits the master; any other event goes toconfig.setSysListener.helper.log(...args)— write a log line to.sys/run.log; echoes to the terminal likeconsole.logwhen the progress bar is off or the output is not a TTY.
Changelog:
- 4.0.1 Minor tweaks
- 4.0.0 Add
task_storage: 'aof'mode (memory-grade speed with full resume) as the new default - 3.5.2 Fix Readme
- 3.5.1 Fix bench-storage.svg
- 3.5.0 Add
task_storage: 'memory'mode (~17x faster, no resume) - 3.4.1 Rewrite README: simpler structure, all examples verified by test cases
- 3.4.0 Show per-worker load (ELU/CPU/memory) under progressBar; stability fixes
- 3.3.0 Unserializable results still succeed; shouldTerminate throwing is safe; progressBar counters added
- 3.2.3 Support workerPriority: set OS scheduling priority for worker processes
- 3.2.2 initialTasks accepts a function (sync or async) that is called only once, in the master process
- 3.2.1 Fix retry bug: user-defined taskCount/index no longer overwritten on task retries
- 3.2.0 Add progressBar (on by default); console output diverted to run.log; new startup banner
- 3.1.9 Print the multi-tasks-monitor command on startup
- 3.1.8 Small refinements
- 3.1.7 onFinish: iterate all succ/failed results via helper.foreachSuccResult/foreachErrorResult
- 3.1.6 Fix silent task loss under heavy load with maxTaskRetries
- 3.1.4 Rewrite methods multiTasks.resume/retry_fails/restart
- 3.1.0 Support worker broadcast and system events; default numberOfWorkers is now "50%" of CPU cores
- 3.0.3 Support 'maxTaskRetries'
- 3.0.2 Support 'taskTimeout'
- 3.0.1 Versions 3.0.0 and above are maintained by AI
- 3.0.0 and earlier: see the git history
Gitee:
https://gitee.com/zhanglei923/multi-tasks