
pdf-ring-watermark
v1.2.0
Published
Embed a traceable ID into PDFs as a discreet, human-readable concentric-ring watermark for leak tracing.
Downloads
83

Maintainers
 turrex0100
Readme
pdf-ring-watermark
Embed a traceable ID into a PDF as a discreet, human-readable concentric-ring watermark — so that any copy of a document can be traced back to its source.
ring-watermark.teckentrup.software — project website with docs and an interactive demo.
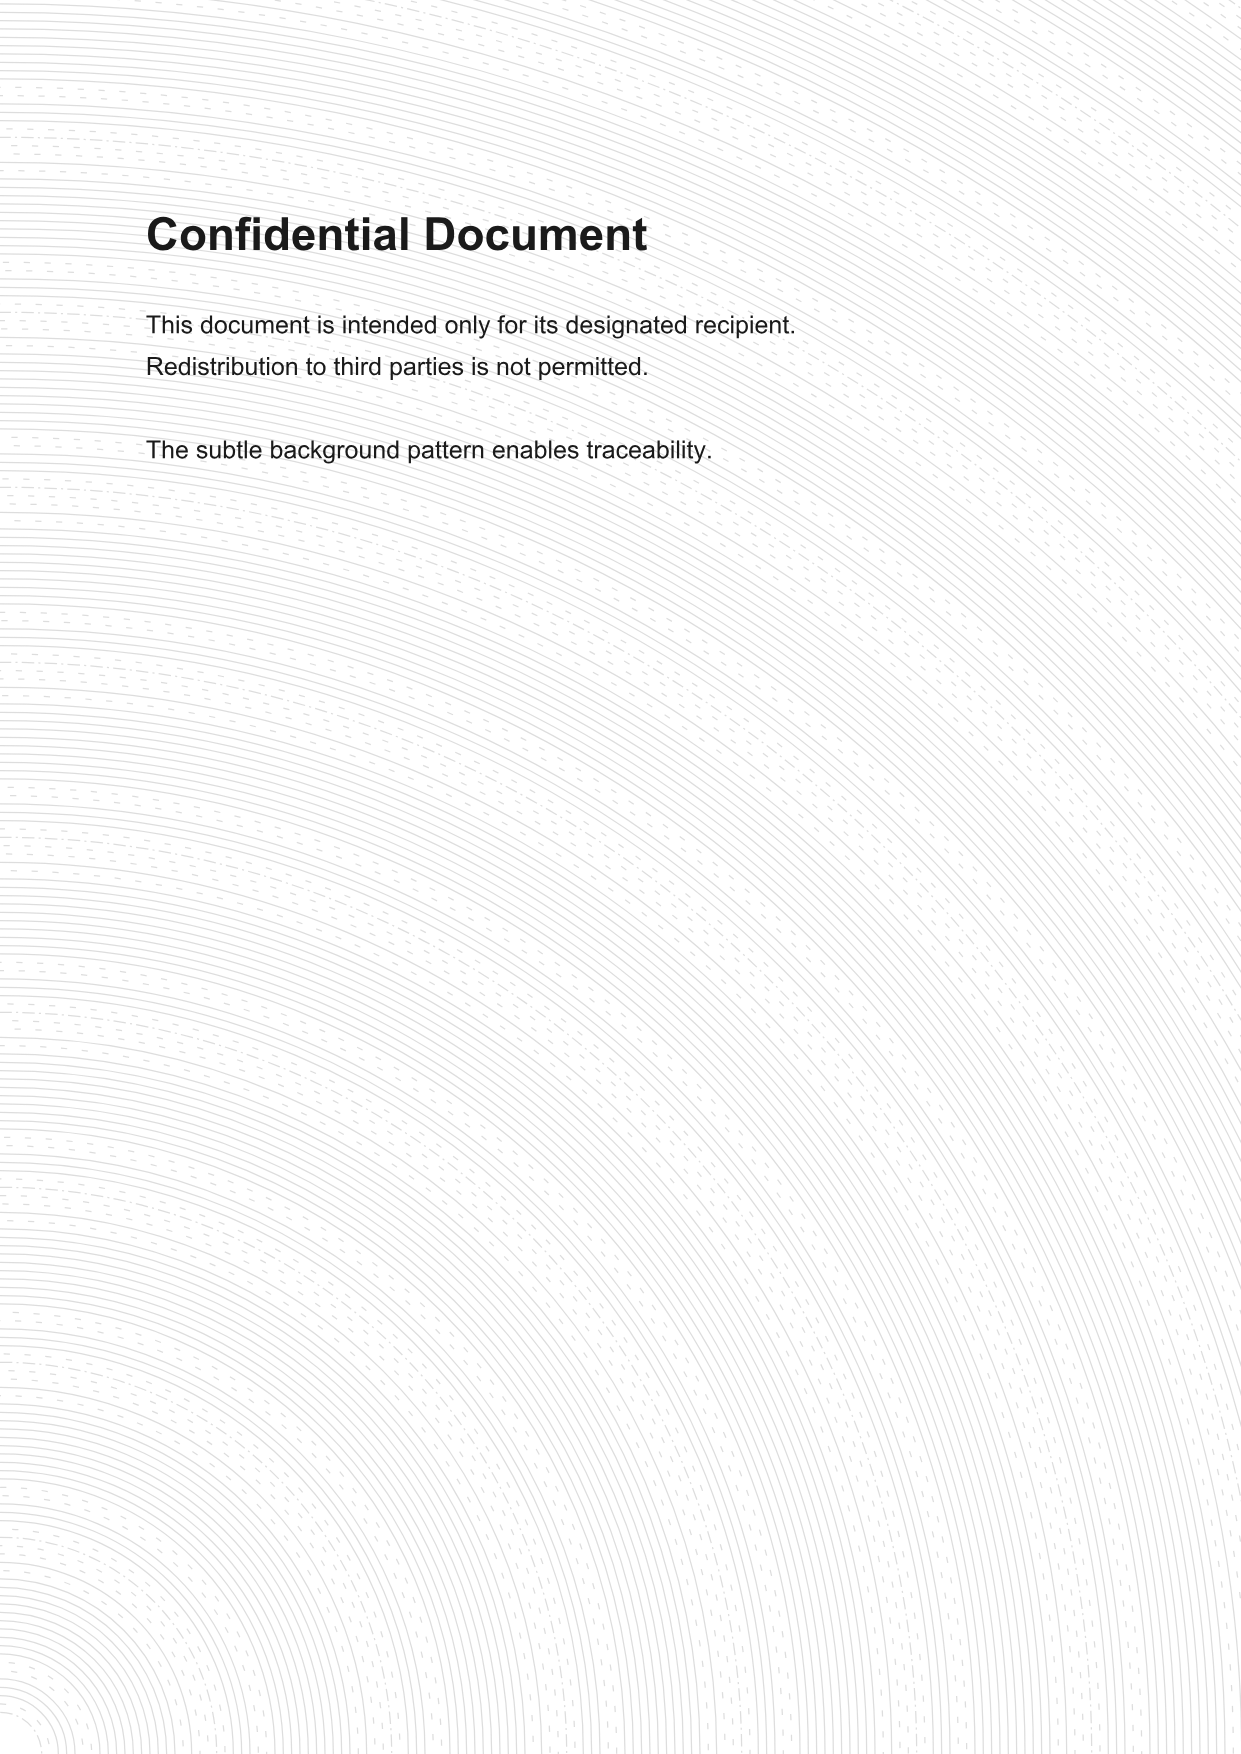
The watermark looks like a subtle decorative background of concentric rings. In reality each ring is one bit of an error-protected codeword: a solid ring is a 1, a dashed ring is a 0, and a distinctive dash-dot ring marks the start of the sequence. Because the pattern repeats across the whole page, even a small photographed crop usually contains a full copy of the ID.
Why this exists
Classic leak tracing ("traitor tracing"): give every recipient a personalized copy, and if a copy turns up where it shouldn't, read the embedded ID to trace the source. pdf-ring-watermark provides two carriers:
- Metadata — the ID is written to the PDF's document properties. Convenient, but trivially stripped.
- The ring pattern — the forensic channel. It survives copying, re-export, screenshots, and printing, and it can be read by a machine or by a human with no tools.
Features
- Discreet — renders as a faint guilloché-style background; content stays fully legible.
- Crop-robust — the codeword tiles radially, so a partial crop still carries the ID. A ~3 × 3 cm fragment is enough for the default profile (see capacity).
- Error protection — an optional Hamming SECDED code corrects one misread ring and detects two, and guarantees every two IDs differ in ≥ 4 ring bits.
- Human-readable fallback — read the rings by eye, type the bits, and a CLI recovers the ID.
- Matched detection — even an incomplete or slightly wrong read can be matched against your list of issued IDs.
- Three pattern modes — concentric
rings(best camouflage, 2-D spread) orhorizontal-lines/vertical-lines(axis-aligned, easiest to read and to decode automatically). - Fully parameterizable — pattern mode, ID capacity, error protection, spacing, stroke width, darkness, and opacity.
Install
npm install pdf-ring-watermarkRuntime dependencies are only pdf-lib and @pdf-lib/fontkit. Rendering a PDF to an image (needed only for the experimental automatic image decoder) is left to you.
Quick start
import { createRingWatermark } from "pdf-ring-watermark";
import { readFile, writeFile } from "node:fs/promises";

const watermark = createRingWatermark(); // defaults: 14-bit ID, SECDED, discreet

// Tag a copy with document ID 10234, fitting it onto A4:
const source = new Uint8Array(await readFile("contract.pdf"));
const tagged = await watermark.tagPdfOnPaper(source, { userId: 10234 });
await writeFile("contract-10234.pdf", tagged);

// Later, recover the ID from a manual read of a leaked copy:
console.log(watermark.decodeBits("01110011111111110100")); // { userId: 10234, ... }
Reading a leaked document by hand
No tools required — this is the whole point of the visible channel.

- Find a dash-dot ring — that is the start marker (bit 0 begins just outside it).
- Read the rings outward from there: solid = 1, dashed = 0.
- Note the sequence. You can also read the rings inward of the start marker — they belong to the previous, identical repetition and fill the high bits.
- Feed the bits to the CLI, marking the start ring with
.,,, or!:
npx pdf-ring-watermark decode-bits "1110100,0111001111"- A complete read returns the ID (and auto-corrects a single misread or a single gap).
- An incomplete read — or one you're unsure about — is matched against your issued-ID list:
npx pdf-ring-watermark match-bits --ids issued-ids.txt "0111,00111111"This ranks the candidates by likelihood; the correct ID wins even from a partial read, because your list bounds the search.
The line modes read the same way — find the dash-dot line and read across it (top→bottom for horizontal lines, left→right for vertical).
If you can't tell a ring's style apart, type x (or ?) in its place. It's kept as an erasure so the following bits stay aligned: with SECDED a single uncertain ring is still recovered automatically, and match-bits simply ignores the unknown positions.
The CLI must use the same profile the document was tagged with. If you changed
idBitsorprotection, pass--id-bits <n>and--protection <none|secded>.
API
createRingWatermark(options?) → RingWatermark
All options are optional; defaults produce a discreet, A4-friendly watermark with 1-bit error protection.
| Option | Default | Meaning |
| --- | --- | --- |
| mode | "rings" | "rings", "horizontal-lines", or "vertical-lines". |
| idBits | 14 | Payload bits — the ID space is 2 ** idBits (16,384 IDs). |
| protection | "secded" | "none" (max density) or "secded" (correct 1 / detect 2 bit errors). |
| spacingPt | 4 | Radial spacing between adjacent rings — the radius step from one ring to the next (for line modes: the perpendicular gap between lines), in PDF points. |
| strokeWidthPt | 0.6 | Ring stroke width, in points. |
| firstRadiusPt | 20 | Radius of the innermost ring, in points. |
| darkness | 0.42 | Ink darkness of the rings, 0–1. |
| opacity | 0.15 | Stroke opacity, 0–1 (lower = more discreet). |
Instance methods
// Encoding
watermark.createTestDocument({ userId, paper? }): Promise<Uint8Array>;   // blank demo page
watermark.tagPdf(source, { userId }): Promise<Uint8Array>;              // overlay, keep page size
watermark.tagPdfOnPaper(source, { userId, paper? }): Promise<Uint8Array>; // fit onto paper, full-bleed

// Manual decoding (fallback)
watermark.decodeBits(input): ManualDecodeResult;                        // full read -> ID
watermark.matchBits(input, candidateIds): ManualMatchResult;            // partial read -> ranked IDs

// Experimental automatic image decoding (see Limitations)
watermark.decodeImageExperimental(image, candidateIds): ImageDecodeResult;

// Geometry
watermark.codewordBits;        // total pattern bits per ID
watermark.elementsPerCodeword; // rings/lines spanned by one codeword (incl. sync)
watermark.periodMm();          // length of one codeword across the pattern, mm
watermark.safeCropSquareCm();  // side of a crop square that always contains a full ID
tagPdfOnPaper is the recommended way to tag a document you will print: it places the content on the target paper (A4 by default) and draws the pattern edge-to-edge, so it prints without margins. tagPdf keeps the source page size (useful when the source already matches your paper).
Capacity & crop size
More payload bits and stronger protection cost more ring bits, which means a larger crop is needed to capture a whole ID. Guaranteed error-tolerant capacity (minimum Hamming distance) for a 16-bit-class codeword:
| Protection | Guaranteed distance | Correctable | IDs (14-bit payload) |
| --- | --- | --- | --- |
| none | 1 | 0 bits | 16,384 |
| secded | 4 | 1 bit (2 detected) | 16,384 |
For the default profile (14-bit, SECDED, 4 pt spacing): the codeword is 20 bits, one codeword spans 21 rings ≈ 3.0 cm, so a ≈ 3 × 3 cm crop guarantees a full ID in any position and rotation. Mere identification via match-bits typically needs only ~2 × 2 cm.
An interactive calculator (payload bits + protection → rings and crop size) is available on the website.
How it works
- Geometry. Rings are concentric quarter-circles centered at a page corner, stepping outward by
spacingPt. Every group ofcodewordBits + 1rings starts with a dash-dot sync ring followed by the data rings; the codeword repeats outward for redundancy. - Bits. Each data ring's line style encodes one bit (solid
1/ dashed0). - Codec. The user ID is turned into a codeword by the payload codec. With
secded, a Hamming single-error-correct / double-error-detect code adds parity so every two IDs are far apart in bit space and single misreads self-correct. - Decoding. A reader measures each ring's duty cycle (ink along the arc) into a soft value, aggregates repetitions, and either decodes the codeword directly or correlates the soft values against a candidate ID list (matched detection). The sync ring anchors the absolute bit positions; rings can even be counted locally, without recovering the pattern center.
Limitations
- The automatic image decoder is experimental. Recovering an ID directly from a photo/scan works well for full pages and corner-region crops, but degrades far from the center where the arcs are nearly straight. Always check the returned confidence, and prefer the manual
decodeBits/matchBitspath when in doubt. The metadata channel and the manual channel are the reliable core. - The metadata channel is trivially stripped — treat it as convenience only.
- Printing a page onto a different paper size letterboxes the pattern; tag with
tagPdfOnPaperfor your target paper, or print at 100 %.
License
MIT — see LICENSE.