
tanuki-context
v0.20.0
Published
Cut 79-91% of the input tokens your logs and command output cost. MCP server or drop-in proxy: park bytes outside the conversation, fetch exact slices, draw a slice as dense PNG pages when that is cheaper - and it says when plain text is cheaper instead.

Maintainers
 osyna
Readme
tanuki-context
Big logs and command output are the expensive part of talking to an AI. tanuki-context makes them 79 to 91% cheaper, keeps every byte recoverable, and tells you when it is not worth doing.


Try it · Set it up · Commands · Is it worth it? · Which model? · Evals · Changelog · Manual
What you are paying for
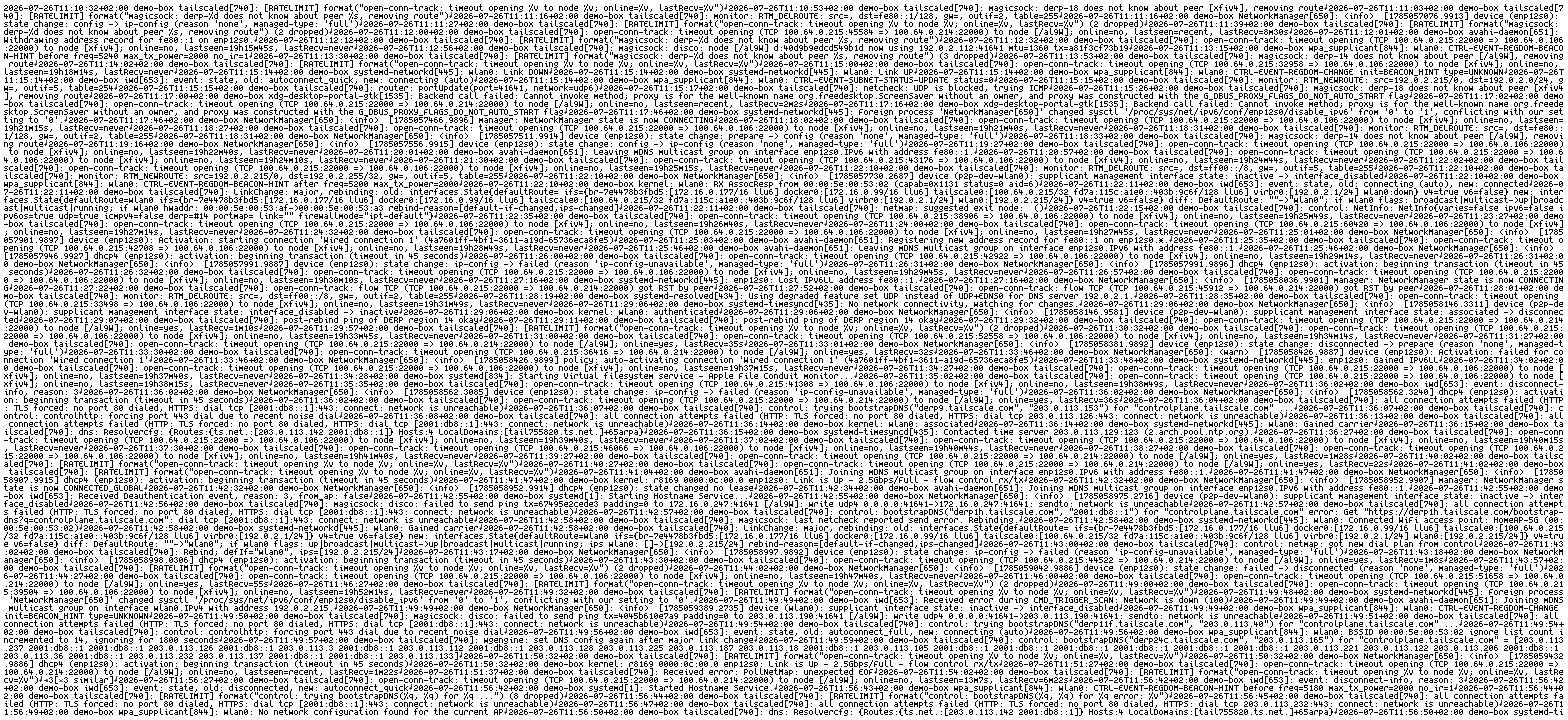
Paste a 200 KB log into a chat and you have just spent about 51,200 input tokens. The painful part comes next: every following turn resends the whole conversation, so you pay for that same log again, and again, for as long as the session lasts. A long debugging session can spend more on re-reading one log than on all the actual thinking.
tanuki-context makes the bulky parts small. It draws text as dense image pages the model can read, or parks it outside the conversation so the model pulls back only the lines it needs. That same 200 KB log costs 10,752 tokens as pages, and 5,264 if the repeated noise is dropped first.
Three things it will not do to you:
- No AI summarising. Nothing is reworded or "condensed" by a model. Error lines survive character for character.
- No lost passwords or ids. Secrets are never drawn as pixels. Exact strings like ids, hashes and MAC addresses always travel as real text.
- No selling you something that does not pay. When plain text is cheaper, it says so and recommends you skip it. It refused to image two of the four real files we pointed it at.
Try it in one command
Nothing to install and nothing to sign up for. It renders no images and costs nothing to run. All it does is the arithmetic:
npx tanuki-context estimate your.logHere is a real run on a 200 KB slice of system journal. It comes out at 81,527 text tokens rather than the 51,200 quoted above because this particular journal is denser, and the estimator prices character classes instead of dividing the character count by four:
{
  "rawTextTokens": 81527,
  "imageTokens": 10416,
  "pages": 8,
  "fidelity": { "level": "high", "approxAccuracy": "~98%" },
  "route": {
    "pick": "image",
    "savedPct": 77,
    "reason": "imaging clears the read-back band and beats the text side on tokens"
  },
  "cost": {
    "cheaper": "PIPELINE",
    "textUsd": 1.222905,
    "imageUsd": 0.15624,
    "savedPct": 87
  }
}
You only need four of those fields:
| field | what it is telling you |
| --- | --- |
| route.pick | The recommendation. image means draw it as pages, text means shrink it but keep it as text, raw means leave it completely alone. |
| route.reason | Why, in a sentence. Worth reading when the answer surprises you. |
| cost.cheaper | PIPELINE or TEXT, in real dollars. Add --model to price it for your model, and --cached if the content is already in the prompt cache. |
| fidelity.level | How reliably a model can read the pages back. high is safe, unreliable means keep it as text. |
Ask for a price against your own model:
npx tanuki-context estimate your.log --model claude-opus-5
npx tanuki-context estimate your.log --model gpt-5           # OpenAI tile rule
npx tanuki-context estimate your.log --model gemini-2.5-pro  # Gemini tile rule
And watch it turn itself down. Two real refusals, both from the command above:
--model claude-sonnet-4-5   (a model measured at 0% on reading pages)
  "pick": "text"
  "reason": "this model reads dense pages at 0% task success while scoring
              100% on the same task as text (EVALS §3) - stay text"

a file containing an AWS secret key
  "pick": "raw"
  "reason": "credential content is never imaged - stay text"
Set it up
Four ways to use it, and they do not conflict. Most people want the first two together.
| If this sounds like you | Go to | | --- | --- | | I use Claude Code, Cursor, or another app that supports MCP | 1. MCP server | | I want the model to use it properly without me asking | 2. Add the skill | | My app cannot be configured, or I do not want to touch it | 3. Proxy | | I just want to shrink a file or a command's output myself | 4. Terminal only |
You need Node 18 or newer, or the single Rust binary. There is nothing to compile, no dependencies to pull in, and no config file anywhere.
1. MCP server
MCP is the standard socket for handing an AI app extra tools. Plug tanuki in and the model decides for itself when something is too big, without you prompting it.
Claude Code, one line:
claude mcp add tanuki-context -- npx -y tanuki-contextAny other MCP client takes the same command in its config file:
{
  "mcpServers": {
    "tanuki-context": { "command": "npx", "args": ["-y", "tanuki-context"] }
  }
}
Restart the app, then check it connected:
claude mcp listtanuki-context: npx -y tanuki-context - ✔ ConnectedThe model now has five tools it can reach for on its own:
| tool | what the model uses it for |
| --- | --- |
| tanuki_estimate | Price something before touching it. Always the first call. |
| tanuki_render | Draw the text as pages, once estimate says it pays. |
| tanuki_stash | Park a big thing outside the conversation, get back a small map of it. |
| tanuki_fetch | Pull back only the slices it needs: regex search, line range, or free-word find. |
| tanuki_verify | Check a value it read off a page against the original bytes. |
Three more tools (tanuki_distill, tanuki_compress, tanuki_stats) are hidden
by default, because every advertised tool costs you tokens on every single
request. Turn them on with TANUKI_ALL_TOOLS=1 if you want them.
2. Add the skill
The MCP server gives the model tools. The skill gives it the habits: estimate before rendering, stash anything large, never retype an id off a page, quote errors from the sidecar rather than the pixels. Without it you will find yourself prompting the workflow by hand.
npm i -g tanuki-context
cp -r "$(npm root -g)/tanuki-context/skills/tanuki-context" ~/.claude/skills/
From a git checkout it is cp -r skills/tanuki-context ~/.claude/skills/. The
same file works in any skill-aware harness that reads that directory.
3. Proxy
Use this when the app cannot be configured, or when you would rather not touch it. The proxy sits between your app and the model's API and rewrites the oversized parts as they go past. Your app carries on thinking it is talking straight to Anthropic.
npx tanuki-context proxytanuki-context proxy on http://127.0.0.1:8484 -> https://api.anthropic.com
level=0 distill=false codebook=false font=normal recency=1 minChars=4000 ratio=0.75 minSave=300
rules: system prompt & tools untouched · in-place blocks only · last 1 message(s) kept as text
· secrets never imaged · cache_control skipped · identical blocks imaged once
· imaged prefix marked cacheable
point your client at it: export ANTHROPIC_BASE_URL=http://127.0.0.1:8484Then, in the shell that runs your app:
export ANTHROPIC_BASE_URL=http://127.0.0.1:8484It prints its own rules on startup because those rules are the reason it is safe to leave running. Your system prompt and your tool definitions are never touched. The most recent message always stays as text. Anything holding a secret is left alone. If a transform throws for any reason, your original bytes are forwarded unchanged rather than the request failing.
Knobs worth knowing: --distill drops repeated log noise before drawing,
--min-chars 4000 sets how big a block has to be before it is worth touching,
--recency 1 is how many recent messages stay text, --port and --upstream
move it somewhere else.
4. Terminal only
No AI client involved at all. Useful for shrinking something before you paste it anywhere, or just to see what a file would cost.
npx tanuki-context estimate your.log       # what would this cost?
npx tanuki-context run -- npm test         # run a command, keep the output small
npx tanuki-context stash big.log           # park it, get a map back
The commands
Every command works with npx tanuki-context <command>, or directly if you
installed it globally.
| command | what it does |
| --- | --- |
| estimate <file> | Prices the file. Renders nothing. Add --model, --cached, --distill, --codebook, --font tiny. |
| run -- <command> | Runs your command, prints a shrunk version of the output, stashes the full thing. |
| stash <file> | Parks the file and returns a map of it plus an id. |
| fetch <id> | Pulls slices back out with --query <regex>, --lines 40-90, or --find "free words" (top-scored windows, never imaged). |
| verify <id> <value> | Checks a value against the stored original. No model involved. |
| render <file> [level] [outdir] | Writes the actual PNG pages to a directory. |
| distill <file> | Prints the text with repeated lines collapsed, errors untouched. |
| proxy | Starts the middlebox described above. |
| serve | Starts the MCP server on stdio. This is the default with no arguments. |
run: the one to try first
It wraps any command, so long output stops being a problem you have to think
about. Real output from journalctl, with hostnames trimmed out:
npx tanuki-context run -- journalctl --no-pager -n 3000[tanuki run] exit 0 · 3058 -> 1795 lines · 41% of chars removed
stashed e82f2452b264 · 394225 bytes · 3058 lines
distill map: 3058 -> 1795 lines · 41% of chars removable · 370 error/warn lines
top repeats:
×176 Jul 31 08:00:55 tailscaled[801]: magicsock: derp-14 does not know about peer, removing route
×78 Jul 31 08:01:12 tailscaled[801]: open-conn-track: flow TCP got RST by peer
×72 (template) Jul 31 08:00:42 iwd[668]: event: state, old: disconnected, new: autoconnect_quick
first: Jul 31 08:00:38 systemd[1]: Reached target Local Integrity Protected Volumes.
last: Jul 31 08:19:48 tailscaled[801]: open-conn-track: timeout opening to node; online=no
fetch: tanuki_fetch {"id":"e82f2452b264","query":"<regex>"} or {"id":"e82f2452b264","lines":"a-b"}The exit code is preserved, the error and warning lines are all still there, and
the full 394 KB is one fetch away whenever you want it.
stash, fetch, verify: the exact-bytes path
This is the part with no fidelity risk at all, because nothing becomes a picture unless the slice you ask for is genuinely enormous.
$ npx tanuki-context stash app.log
stashed a45a0618b179 · 74514 bytes · 1204 lines
distill map: 1204 -> 87 lines · 94% of chars removable · 40 error/warn lines

$ npx tanuki-context fetch a45a0618b179 --query "FATAL"
verify is the backstop for the one thing pixels are bad at. If a model reads a
value off a page and gets a character wrong, this catches it without asking any
model anything:
$ npx tanuki-context verify a45a0618b179 42440ce06042
{"candidates":[],"found":"42440ce06042","line":401,"status":"exact"}

$ npx tanuki-context verify a45a0618b179 42440ceO6042   # the 0 misread as an O
{"candidates":[],"found":"42440ce06042","line":401,"status":"corrected"}

$ npx tanuki-context verify a45a0618b179 deadbeef1234
{"candidates":[],"found":null,"line":null,"status":"absent"}
absent is the important one. It means the model invented the value, and you
found out for free.
Is it worth it? The honest answer
Sometimes. Here is the case against, first, because you should read it before you rely on any of this.
| the catch | the measurement | | --- | --- | | Pages need a capable reader | 2 of 5 models tested score 0% on a task they solve 100% of the time as text | | Exact strings never survive pixels | 0 of 14 test strings came back character-perfect on any model, so they ride a text sidecar instead | | The money case is capped by caching | cached content bills at $0.30/Mtok, so plain inlining wins the median case by 3.5× |
So the honest claim for imaging is predictable, not cheaper: $0.124 to $0.225 across nine runs, against inlining's $2.94 worst run. And every percentage on this page is input-side. With output measured at 53% of spend, halving your input tokens is at best about a 23% cut to the bill (EVALS §6).
Two capabilities carry none of those caveats, and they are the ones to reach for first:
- Park, fetch, verify is exact by construction. stash, fetch and diff over
19.7 MB of real logs recovered 19,722,893 of 19,722,893 characters
byte-identical.
tanuki_verifyturns a one-character misread intocorrectedwith no model call at all (EVALS §7). - Text reduction has no fidelity risk and no model dependence.
distillcuts a real pacman log 45% and a JSON dump 94%, and the output is still ordinary text (EVALS §4).
The strongest evidence the router is built honestly is that it refuses to sell itself. Pointed at four real files it declined to image two of them, one for credentials and one for being past the read-back cliff.
Which models can read the pages
There are two separate questions here, and mixing them up is the usual mistake. Can the model read a dense page? And what does that page cost on its provider? The second is implemented for three tile rules. The first can only be answered by measuring, and we have measured five models.
Read-back capability, measured at n=8 seeds
Same task, same file, text version against imaged version (EVALS §3):
| model | as text | as pages | verdict |
| --- | ---: | ---: | --- |
| claude-opus-5 | 100% | 100% | use pages freely |
| claude-opus-4-8 | 88% | 88% | use pages freely |
| claude-sonnet-5 | 100% | 88% | use pages freely |
| claude-sonnet-4-5 | 100% | 0% | keep it text |
| claude-haiku-4-5 | 100% | 0% | keep it text |
Page-reading does not track how good the model is. claude-sonnet-4-5
solves this task every time as text and never as pages, while the older, smaller
claude-opus-4-8 manages 88% at both. No ordering here could have been guessed
from benchmark scores or parameter counts, which is exactly why the next section
asks you to test rather than telling you what to expect. Pass model to
tanuki_estimate and it will refuse to route a measured weak reader to images.
What a page costs, per provider
The same 200 KB journal, rendered once, counted by each provider's own rule:
| provider | how it counts an image | image tokens | vs Anthropic |
| --- | --- | ---: | ---: |
| Anthropic | 28 px patches | 10,528 | n/a |
| OpenAI | 512 px high-detail tiles, 85 + 170/tile | 10,880 | +3% |
| Google Gemini | 768 px tiles, 258/tile | 6,192 | −41% |
| anything else | falls back to the patch grid | 10,528 | approximate; set TANUKI_RATES {"default":{...}} |
Gemini's coarser tiles make an identical page notably cheaper to send. That is a counting fact and nothing more. It says nothing about whether Gemini can read the page, which is the question above.
Help us measure yours
The models below are unmeasured. We are not going to guess on your behalf, and the table above is the reason why.
| model | read-back | | --- | --- | | GPT-5 / GPT-5-mini | unmeasured | | Gemini 2.5 Pro / Flash, Gemini 3 | unmeasured | | GLM-4.6 / GLM-4.5V | unmeasured | | Qwen2.5-VL, Qwen3-VL | unmeasured | | DeepSeek-VL, Mistral, Llama vision | unmeasured |
The fixtures are committed, so testing one takes a few minutes and needs no changes to the harness. The question is stored beside them, word for word:
This service log has exactly one FATAL panic line - the root cause. Reply with ONLY the component name in its
component=field (the word aftercomponent=, drop any #id).
- Text arm: send
reference/task/seed-11.logwith that question. - Image arm: send
reference/task/seed-11-default/page0.pngplus theverbatim.txtbeside it, same question. - Both should answer
vclock-merger. Ground truth for every seed is inreference/task/answers.json. Repeat acrossseed-23andseed-37.
A model that answers the text arm and fails the image arm is a weak reader, and
belongs in the refusal list. npm run taskqual automates this, but it posts to
the Anthropic API today, so other providers need the manual run above or a
provider adapter, which is a very welcome contribution.
Please open an issue with what you find, including the model id and which seeds you ran. Measured results go into the table above and into the router's refusal list, where they stop other people wasting money.
Every feature, measured
One sweep, four real corpora (journald log, pacman log, JSON, TypeScript
source), current engine. [calc] means arithmetic at published rates rather
than an end-to-end measurement. Every row is reproducible from the linked eval
section.
| Feature | Applies to | Tokens saved (measured) | Task / fidelity result | Verdict & comment | Evals |
| --- | --- | ---: | --- | --- | --- |
| (text-side transforms) | | | | | |
| L1 whitespace | any text | 0% on all 4 corpora | lossless | Safe no-op. Only pays on ragged or indented text. | §4 |
| L2 prose / L3 dense | prose | 0–0.1% | light/medium loss | Not worth enabling. Irreversible rewording for a tenth of a percent. | §4 |
| L4 caveman | prose | 0–1% | heavy loss | Not worth enabling. Worst trade in the codebase. | §4 |
| distill (stage 0) | logs, noisy output | 30% log · 45% pacman · 94% JSON · 16% TS | keeps every error line verbatim | Best text feature. The only text tier that pays for itself. | §4 |
| table (columnar) | JSON/NDJSON only | 59% JSON · 0% elsewhere | reversible | Excellent, narrow. Keys stated once. | §4 |
| codebook (sigils) | repeated long tokens, paths | image 5,264 → 3,808 (−28% off image) | reversible; confusability guard | Free win, no downside measured. | §4 |
| crush knob (0.20) | big JSON/NDJSON row sets | 94% on 500 rows (96% with table) | reversible: full set stashed, pointer line names the id | headroom's SmartCrusher shape fused with the stash. Keeps head 10 / tail 5 / every error row. | §12 |
| run rule table (0.20) | dev-command output | 79% weighted on 13 real fixtures | errors kept verbatim; never-worse guard; exit code passes through | rtk's design: success elision + noise rules. Full output always stashed. | §11 |
| Hedge rewrites L2+ (0.20) | hedge-laden prose | hedge-dense fixture: L2 0→27% | README control: byte-identical | caveman's rewrite rules. Fires on hedges, zero effect on technical prose. | §13 |
| recommend.crush composed route (0.20) | row sets, priced on every estimate | 500 thin rows: old route 14,247 tok → 112 (99%); fat rows 44,804 → 1,008 (98%) | selection then table × codebook × pages; probe is pure (stashes nothing); route.reason steers | The new selection feeding the old imaging walk - neither wins alone on fat rows. | §15 |
| (imaging) | | | | | |
| Imaging, normal font | bulk you will read | 85–91% vs raw text | capable readers match their own text score (88–100%); 2 of 5 models score 0%; exact strings 0/14 | The headline, and the only conditional capability here. | §2, §3 |
| tiny font (4×6) | bulk you will never read | 91–96% (−40% off image) | 0/5 task, 3/10 needle recall | Cheapest number on the page and it cannot do the job. Lossy-bulk only. | §3, §4 |
| distill + imaging | navigation index | 88–100% | 1/5 task | Locating only, never understanding. | §4 |
| (exactness & safety) | | | | | |
| verbatim sidecar | ids, hashes, MACs, base64 | costs ~42% of render payload | 100% of at-risk ids over 19.7 MB; 94.5% on never-seen shapes | Essential. It is what makes imaging safe at all. | §7 |
| verbatim: "lazy" | cold, one-shot renders | cuts 42% of payload | no measurable cost win; 97% cache hit | Opt-in. Cached bytes bill at $0.30/Mtok, so cutting them saves the cheapest thing. | §6 |
| stash | content beyond the window | n/a, a capability | 19,722,893 / 19,722,893 chars byte-identical | Flawless. Not an optimisation, a capability. | §7 |
| fetch + match-count | slice retrieval | n/a | retrieval precision 73.3% across 5 strategies | Essential. The match-count marker is the only text route to an aggregate answer. | §10 |
| fetch --find (0.20) | bare-word answers | n/a | 3/3, the only strategy carrying a bare English word as text; never imaged | The pixels-only unit miss from 0.16 finally has a text route. | §10 |
| verify | settling a misread value | ~40 tokens | corrects one-character misreads, no model | Flawless backstop. Covers the sidecar's residual. | §7 |
| Credential gate | secrets | refuses to image | never imaged | Essential. | §8 |
| Redaction on fetch | secrets in returned slices | n/a | 2 false positives in 166,985 lines, both real secrets | Essential. fetch returned secrets as text until 0.18. | §8 |
| dense refusal | identifier-dense pages | forces text | 2 of 1,393 pages flagged | Correct. Prevents a silently capped sidecar. | §7 |
| Weak-reader gate | haiku-4-5, sonnet-4-5 | forces text | those two: 100% as text, 0% as pages | Essential, but only fires when the caller passes model. | §3 |
| Filename gate (0.20) | .env*, keys, .aws/... | refuses render/distill/stash | deliberately overcautious (secretary-notes.md refuses too); --allow-sensitive overrides | caveman's pre-flight complement to the content scanner. | §13 |
| Fidelity band | all imaging | n/a | band now agrees with outcome: good ↔ 100%, unreliable ↔ 20% | Honest since 0.19. Previously called distill "degraded" while it solved 1/5. | §9 |
| Router | every call | n/a | declined to image 2 of 4 real corpora (credentials; past the cliff) | Best evidence the engineering is sound: it refuses to sell itself. | §5 |
| (proxy) | | | | | |
| In-request dedupe | repeated blocks | repeat → ~283-byte pointer | safe: the first copy still carries pages and sidecar | Keep. | §6 |
| Cross-request reuse | n/a | n/a | rejected: changes the prefix and invalidates the cache it meant to save; also drops the sidecar | Built, measured, reverted. Guard test mirrored into Rust. | §6 |
| cache_control breakpoint | multi-turn conversations | 2.1× / 3.0× / 4.7× at 3/5/10 turns [calc] | byte-stable pages | Biggest cost lever found. Cache writes are the whole variance story (5.1×). | §6 |
| Fail-open | any transform throw | n/a | survives malformed, astral-plane and null-byte bodies | Essential. A throw used to kill every in-flight call. | §6 |
| Session diagnostics (0.20) | every proxied request | n/a (diagnosis, not savings) | cache-break attribution, never-invoked tool tax, volatile-system-prompt flag; zero forwarded bytes changed | ctxdiff's questions answered live; found a real classifier bug via a Rust panic. | §14 |
| (accounting) | | | | | |
| textTokens (class-weighted) | every routing decision | n/a | real content median 3.3% / worst 16.2%, vs chars/4 at 38.3% / 65.6% | Fixed a 3× error in both directions. One documented bound: 239% on pure camelCase blobs. | §9 |
| Output-share reporting | every workload | n/a | output = 53.3% of spend | The ceiling: no input-side tool can cut more than 46.7% of the bill. Tightens as the tool succeeds. | §6 |
The three-line version. Unconditional value: distill (30 to 94%), table
on JSON (59%), and stash with verify (byte-exact). Conditional value:
imaging at the normal font (85 to 91%), for a measured-capable reader, for
comprehension, never for exact strings. Not worth enabling: L2, L3, L4,
and both tiny font and distill+imaging when the goal is understanding.
What imaging saves
Measured on a 200 KB slice of a real system journal (identifiers rewritten,
repetition and every error line untouched). Reproduce with npm run tiers.
| how the log enters the conversation | tokens | saved | | ----------------------------------- | -----: | -------: | | pasted as raw text | 51,200 | 0 | | drawn as image pages | 10,752 | -79% | | noise removed first, then drawn | 5,264 | -90% | | plus codebook and tiny font | 2,576 | -95% |
Every row is one command on your own file:
npx tanuki-context estimate your.log 0 --distill --codebook --font tinyThe last two rows are lossy on purpose, and measured, they are lossy about
the task as well. On a capable reader the normal font holds 5/5 on the
root-cause task while cutting 76%, distill drops to 1/5, and tiny font
to 0/5 (EVALS §4). Reach for them when you only need
the gist of something, never for a log you will be asked questions about.
When not to reach for it
- Your model cannot read dense pages. Measured at n=8: Opus-4-8, Opus-5 and
Sonnet-5 match their own text score off pixels (88 to 100%), while Sonnet-4-5
and Haiku-4-5 score 100% as text and 0% as pages
(evals). Pass
modeltotanuki_estimateand it refuses to route those to images. Profile your own withTASK_MODELS=… npm run taskqual. - The exact bytes have to survive. Secrets and credentials are auto-refused
and never imaged, and they are masked out of a fetched slice
(
redact:falsewhen you really do want them). Dense random strings misread silently: even frontier models read back only 0 to 1 of 14 test strings character-perfect (evals). That is why theverbatimsidecar ships ids, hashes, MACs, pod names and base64 as text beside the pages, covering 97% of unrecoverable identifiers across 19.7 MB of real logs and 92.9% against id shapes it was never designed for. - The content is small, or your bill is output-dominated.
tanuki_statsreports the output share so you can tell which one you are. - You are not on Anthropic pricing. Pass
modeltotanuki_estimatefor provider-correctcost(OpenAI tiles, Gemini tiles), overridable withTANUKI_RATES.
Measured and rejected
Ideas that were built or priced and then declined. A dead end nobody records costs the next reader a week:
tinyfont as a densification lever. 1.67× denser, and 0/5 on the comprehension task where the normal font scores 5/5. It stays what the fidelity band always called it: a lossy-bulk tier, not free tokens.verbatim: "lazy"as the default. The sidecar is 42% of a render's tokens, so deferring it looked like the largest payload cut available. Measured as its own arm it halves cache writes and lifts the hit rate to 97%, and saves nothing outside the noise, because a cached payload bills at $0.30/Mtok, so removing 42% of it removes 42% of the cheapest thing in the request. Lazy stays opt-in, and stays right for cold one-shot renders (EVALS §6).- Sidecar prefix-folding. Factoring shared prefixes out of the carried strings saves 68 tokens, which is not worth a second encoding that both engines have to agree on byte for byte.
- Template dedup inside distill. distill already cuts a real pacman log 70.9%, above the ceiling a naive template-collapse pass was projected to reach.
- In-block frequency for needle detection. It would add 19 to 32 false
needles per page on real logs (
DISCONNECTED,configuration,firmware), enough to tip pages todense, which forfeits imaging outright, all to chase a shape with zero instances across 19.5 MB of real logs (EVALS §7).
More
- Changelog: every release with the measurement or the decision that caused it, including the ideas that were built and then rejected.
- Full manual: three run modes, all eight tools, stash and fetch, the table knob, benchmarks, internals.
- Design notes: why each pipeline stage exists.
- Evals: we publish the harness rather than a number.
needles(read-back fidelity),paired(cost per successful task),taskqual(task success on pages against text). - Research roadmap: how tanuki maps onto DeepSeek-OCR, Glyph and VIST.
Prior art. ctxdiff by @salmanzafar949 (Apache-2.0), a local-first debugger for the agent context window: content-hashed block capture, git-style turn diffs, prompt-cache break attribution, and detection of tool schemas you pay for on every call but never invoke. It answers what did the model see and what changed; tanuki decides what it sees at all, so the two compose rather than compete. Run ctxdiff around an agent using tanuki and the imaged blocks show up as ordinary diffs. Its fail-open guarantee and schema-bloat framing are the source of the three properties audited in 0.16.1.
More prior art, new in 0.20.0 - each entry is a technique tanuki reimplemented from scratch, measured, and credits:
- rtk (rtk-ai, Apache-2.0): CLI proxy that
filters dev-command output with per-command rules.
tanuki-context runalready followed its wrapper shape; 0.20 adds its rule table - success elision, noise strips, a never-worse guard - measured at 79% weighted on committed real outputs (EVALS §11). - headroom (Tejas Chopra,
Apache-2.0): context-optimization layer. Its SmartCrusher keeps head, tail
and anomalous rows of big JSON arrays behind a retrieval sentinel; tanuki's
crushknob is that shape fused with the existing stash (94-96% on a 500-row NDJSON, EVALS §12). Its CacheAligner volatile-prefix warning became the proxy'svolatileSystemflag. - caveman (Julius Brussee, MIT): telegraphic compression. tanuki's L2-L4 independently converged on the same filler/function-word core; 0.20 ports the rules it lacked - fourteen hedging rewrites (hedge-dense prose L2 0% → 27%) and the filename-based credential gate (EVALS §13).
- context-mode (Mert Koseoğlu,
Elastic-2.0): park-and-search with a BM25/FTS5 knowledge base. tanuki's
stash already followed the park shape; 0.20 adds
find- free-word relevance search reimplemented independently with integer scoring (no floats, no SQLite, no code shared), the only retrieval strategy that carries a bare-word answer as text (EVALS §10).
Rust instead of Node. Same engine, one static binary, held byte-exact and pixel-exact with the npm package by a parity harness:
cargo install --git https://github.com/Osyna/tanuki-context --branch rustMIT. The bundled glyph atlas derives from the Spleen font, GNU Unifont, and pxpipe; see NOTICE.