
windupjs
v1.9.0
Published
Windup — testes E2E em linguagem natural: a LLM planeja uma vez, o replay roda sozinho

Maintainers
 orbitaltec
Readme
Windup 🤖
Natural-language E2E tests with deterministic replay — the LLM plans once, replays run without it.
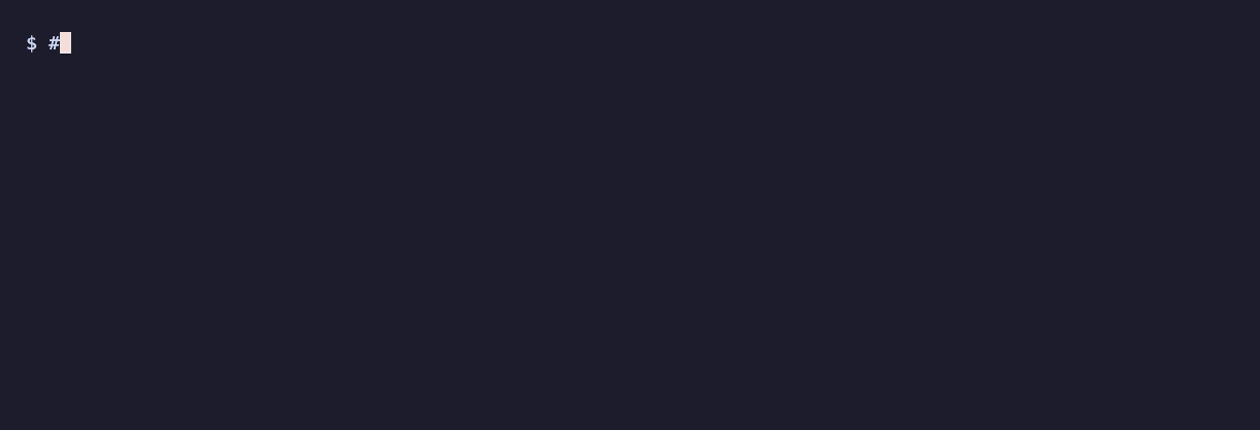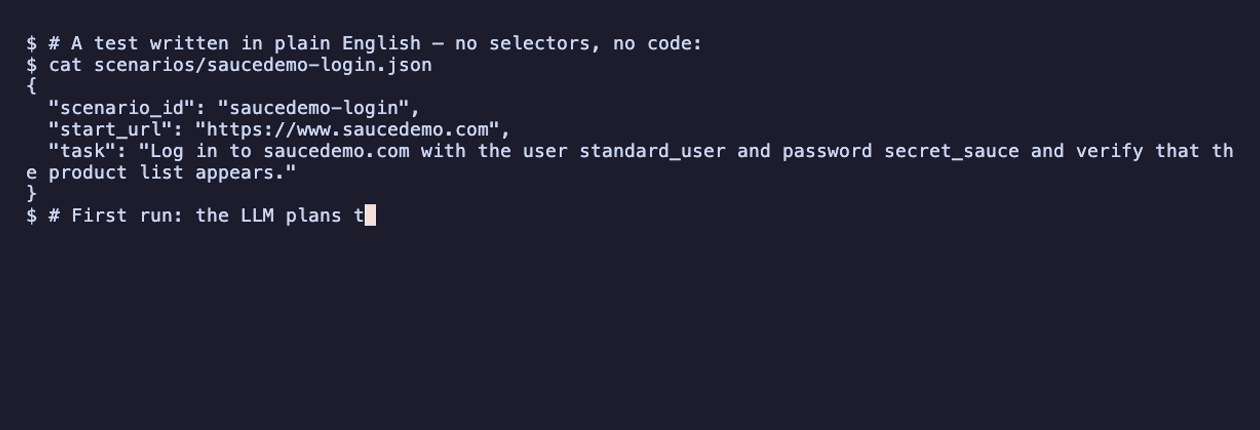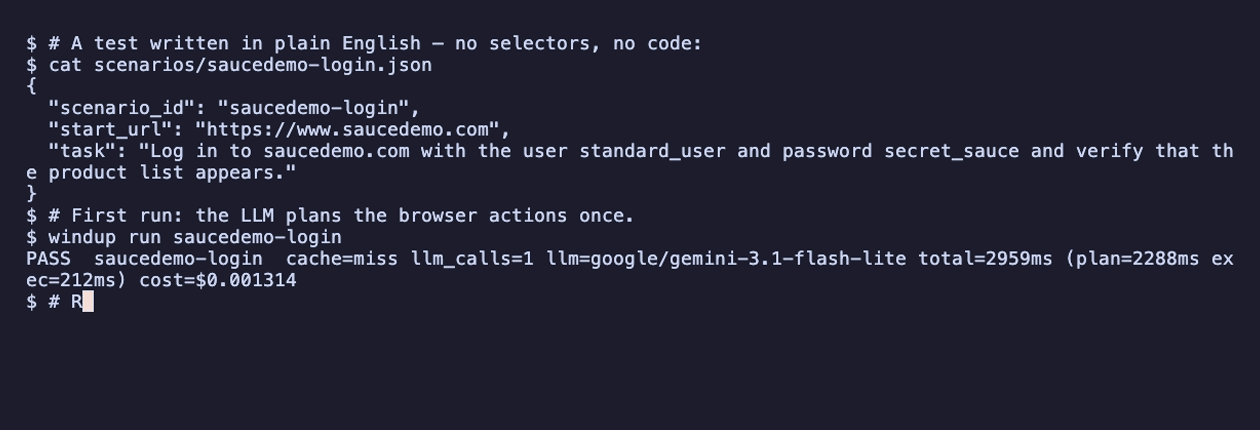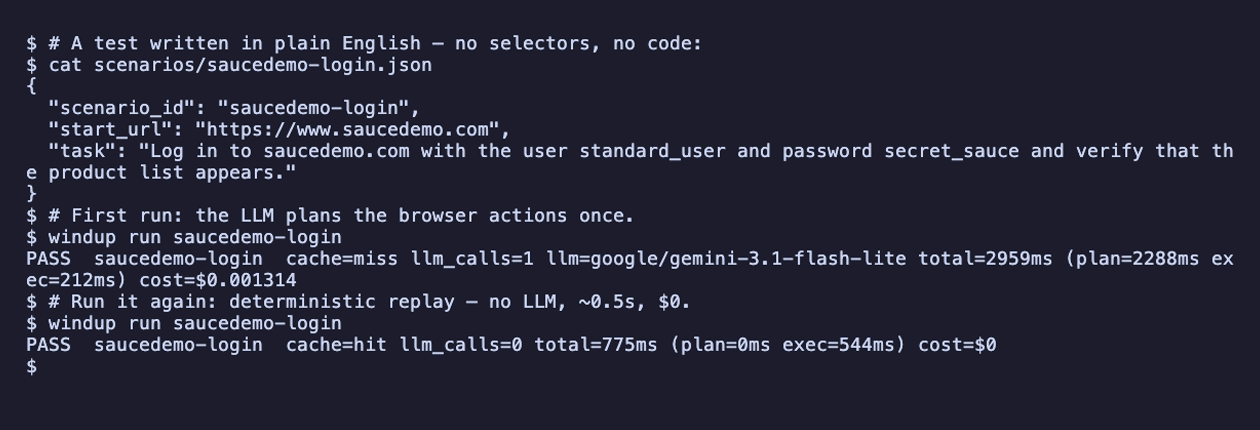
Describe a test in plain language — "log in as the test account, add product X to the cart, check out and verify the order confirmation" — and Windup turns it into a deterministic JSON plan of browser actions. From the second run on, the test replays with zero LLM calls: ~1 second, $0, stable results.
npm i -D windupjs        # Chromium is provisioned automatically (one-time, machine-wide cache)
npx windup init          # 3 questions → windup.config.ts + example scenario
npx windup scan          # index your app's routes & elements from source code
npx windup new "log in as admin and create an invoice"   # LLM-assisted scenario authoring
npx windup run checkout  # 1st run: the LLM plans · every run after: ~1s replay, $0
Requirements: Node ≥ 20 and an API key for your planner LLM in .env.local or .env (.env.local wins — use it when your .env is committed): GOOGLE_GENERATIVE_AI_API_KEY for Google (default) or OPENAI_API_KEY for OpenAI. Keys are only used for planning; cached replays never call an LLM. To use an existing Chrome instead of the auto-downloaded Chromium, set CHROME_PATH; to skip the download entirely, set PLAYWRIGHT_SKIP_BROWSER_DOWNLOAD=1.
How it works
natural-language task ──▶ planner (LLM, 1 call) ──▶ JSON action plan
                                                        │
       trajectory cache ◀── cheap verification ◀── deterministic executor
             │
└──▶ subsequent runs: zero LLM, ~1s, $0- Plans are data, not code — schema-validated JSON; no generated scripts, no conditionals.
- Cheap verification — DOM/URL postconditions after every action. A failed verification invalidates the cached plan and triggers an automatic re-plan.
- Site map — every execution feeds a graph of pages and transitions;
windup scanseeds that graph straight from your source code before the first run, so the planner uses your app's real selectors instead of guessing. - Fragments — proven action blocks (e.g. login) that the planner composes via
{ "type": "use" }instead of regenerating. - Zero hardcoded site knowledge — the engine knows frameworks and the web, never your site. All site knowledge arrives as input (scenarios, config, manifest) or is discovered at runtime.
- What the cache buys is
$0, not "instant" — a cache hit skips the LLM planning (plan=0ms,llm_calls=0), but the plan's Playwright actions still run, and anydepends_onchain still executes. Wall-clock is real-browser time, not a lookup. Each run reports the breakdown —total=… (plan=… deps=… exec=… setup=…)— so you can see where it goes:depsis thedepends_onchain,execis this scenario's actions,setupis the browser context. The HTML report splits each scenario's duration into a reconciling bar (setup · deps · plan · nav · actions) — wherenavis the goto + page load/hydration before the first action, usually the real time sink in an SPA (so a 113 ms action that reads as "3.6 s" is actually setup + nav, not the action). Windup proceeds as soon as the page renders interactive elements or the network goes idle — so a display-only page doesn't sit on the readiness timeout. The suite header shows wall-clock (real elapsed) as the headline, not the sum of per-scenario totals — that sum inflates ~N× under--concurrency N. In the per-scenario bar, the leftover under concurrency is labeledcontention(time the scenario spent waiting for a CPU/browser slot while siblings ran — idle, not work), and anactivems figure is shown — the scenario's own work, roughly stable across--concurrency, so you can compare scenarios without the parallelization noise (a scenario that reads as "19.7 s" under--concurrency 4is often ~2 s of real work + contention). Speed levers:depends_onsession snapshots restore auth instead of re-running the login flow (deps≈0), and--concurrencyoverlaps runs.
A five-minute tour
The full workflow on a fresh project, with what you should expect to see:
# 1. Install — Chromium is provisioned automatically
npm i -D windupjs

# 2. Initialize — 3 questions (base URL, model, scenarios dir)
npx windup init
#    → windup.config.ts + e2e/scenarios/ + .windup/ (cache & map committed; state/runs/reports gitignored)

# 3. Index your app from source — before anything ever runs
npx windup scan
#    scan complete (full): framework=react-router routes=106 elements=1125
#    (Next.js, react-router and TanStack Router file-based routing are indexed)
#    The site map now knows your real routes and selectors; the planner
#    will use them instead of guessing. Re-run after big changes
#    (windup scan --update re-indexes only files changed since, via git).

# 4. Register test credentials once — values never touch git
npx windup secret set admin        # hidden prompts → .env.local + mapping

# 5. Author a scenario from a rough instruction
npx windup new "log in with the admin account and create an invoice for ACME"
#    → e2e/scenarios/create-invoice-acme.json — precise task grounded in
#      your real screens, account referenced by name, final verification

# 6. First run — the LLM plans once (~3-5s, ~$0.002 on the default model)
npx windup run create-invoice-acme
#    PASS  create-invoice-acme  cache=miss llm_calls=1 ... cost=$0.0024

# 7. Every run after — deterministic replay, zero LLM
npx windup run create-invoice-acme
#    PASS  create-invoice-acme  cache=hit llm_calls=0 total=600ms cost=$0

# 8. Read results like a human, ship reports to CI
npx windup run --all --summary --reporter html
npx windup costs                   # AI spend: totals, per provider/model
If a run fails after an app change, the cached plan is invalidated and re-planned automatically on the next run — you edit scenarios, not selectors.
Planning cost, honestly. A simple scenario that plans on the first try is one call: ~3-5s, ~$0.002 on the default model. That is the best case, not the average. A retry path exists and it can cost 10-30× that — when a plan comes back invalid, or the model's reply truncates (more likely on element-heavy pages), the planner retries: measured at 3-5 calls, 30-90s and $0.02-$0.09, and if it never clears validation you pay that for a failure. So a
$0.07line inwindup costsis the retry path, not a bug. Windup prints why each extra call happened (planner retried 2× — truncated response → raising the output budget), and raises the output budget after a truncation rather than repeating the same request. The cheapest fix is almost always the task: quote the exact text to verify ("…verify the text 'Popular parking' appears") — Windup then writes that assertion itself, deterministically, in one call.
Scenarios
A scenario is a JSON file in your scenarios directory (default e2e/scenarios/):
{
  "scenario_id": "checkout",
  "start_url": "/",
  "task": "Log in as the qa account, add 'Backpack' to the cart, check out and verify the order confirmation message appears.",
  "hints": ["Optional site-specific tips for the planner. Delete if not needed."]
}start_urlis optional (defaults to/) and should stay environment-free: a path, resolved against the effective base URL.- End the task with what to verify — that becomes the plan's final postcondition. Beyond "an element is visible" or "the URL is X", the plan can assert richer conditions: text contains a string, an element count (
equals/min/max), a selector is gone (not visible), or an attribute equals a value — so "verify 3 orders appear", "verify the error banner disappears" or "verify the field is marked valid" become precise checks. Phrase the task that way and the planner emits the matchingexpect. - Quote the text you want verified — Windup asserts it for you. When the task names a literal in quotes ("…and verify the text 'Popular parking' appears") and the plan's final check turns out to be weak, Windup rewrites it into a
text_containson that exact text — deterministically, with no extra LLM call, and only after confirming the page really contains it. This is the reliable way to get a strong assertion: it doesn't depend on the model choosing well. - A verification that cannot fail is rejected. A final check is worthless when it passes regardless of the feature: a bare landmark (
body,html,main,div,#root) or any bare selector that matches more than one element on the live page (h2on a page with five headings — deleting the whole section still leaves four). Windup checks both — the landmark list offline, the match count against the real page at plan time — and rejects such a plan, re-planning with an error that says how many elements matched and what to assert instead. Content assertions are fine on any selector:text_contains: { selector: "main", text: "Popular parking" }passes, because what it asserts is the text. Already-cached plans keep replaying untouched; runwindup explain <id>to spot a weak verification you already have (it prints⚠ weak verification: …). - Never put secrets in tasks. Reference accounts from the project manifest (below); the plan will use
value_ref: "ENV:VAR"and the real value is resolved only at runtime, never cached. - Native dialogs & non-toast verification. Windup handles native browser dialogs (
window.confirm/alert/prompt) that guard destructive actions (archive, delete, cancel): the planner adds"dialog": "accept"(or"dismiss"to cancel) to the action that opens the dialog — otherwise the dialog is auto-dismissed and the action silently does nothing. It also steers the final verification toward a persistent signal (a row that disappears, a changed label, a URL) over an ephemeral toast/snackbar that vanishes in seconds. - Dialog default for the whole scenario (
on_dialog). If a flow triggers the same confirmation on several steps (bulk delete, "leave page?" guards), set"on_dialog": "accept"(or"dismiss") once on the scenario and a persistent handler answers every native dialog for the entire run — no per-actiondialogneeded. The per-actiondialogstill works for one-offs; whenon_dialogis set it takes over. - Force one interaction per step (
atomic_steps). By default the planner may compress a reveal-then-act into a single action. Set"atomic_steps": trueand it must emit one interaction per action — never merging an expand/open click with the control it uncovers — so the replay stays granular and the report legible when the UI hides controls behind disclosure. - Quarantine a flaky scenario (
quarantine). Set"quarantine": trueand the scenario still runs and reports, but a failure won't fail the suite (non-zero exit) — so one stubborn flake stops blocking CI while you fix it, without deleting the test or letting it redden every build. It's surfaced loudly (a🔶console line, aQUARANTINEDbadge in the report,quarantined: truein JSON), never silently skipped. Pair it withwindup trends <id>to see whether it has stabilized. - Accessibility-label fallback (automatic). When a plan's CSS selector misses at replay, Windup retries the target by its accessible name (the action's description matched against label/placeholder/role) and acts only when exactly one visible field matches — recovering from a brittle guessed selector without a re-plan. The recovered step is flagged in the report (
≈ found "<label>" by label …). If neither selector nor label resolves, the failure says the control likely has no accessible label (a11y gap) and to anchor it with a hint — so a broken run doubles as an accessibility finding. - Per-scenario determinism (
network/clock). Thenetworkstubs andclockfreeze thatwindup.config.tsexposes globally can also live on a single scenario — scoped to just that run and merged over the global config, scenario winning. That's how you test one error state without collateral:{ "scenario_id": "erro-lista-500", "network": [{ "url": "v1/passports", "status": 500 }] }forces a 500 on that endpoint only here (global stubs still apply; the normal listing scenario is untouched).clockmerges field-wise (scenarionow/timezoneoverride global). Applied at context launch, never cached — the plan is planned against the stubbed page, so an error-UI assertion is stable. (A scenario with its ownnetwork/clockskips browser prewarming — the prewarmed context only carries the global config.) The error a stub deliberately produces is excluded from thefailOngate — a stubbed500won't trip--fail-on-resource/--fail-on-5xx. - Per-scenario
failOn. Open a runtime-health exception for one scenario instead of blinding the whole suite:{ "scenario_id": "…", "failOn": { "resourceErrors": false } }, or a scenario-only"ignore". It's merged over the globalconfig.failOn— the boolean gates take the scenario's value when set, andignorelists concatenate (global noise + this scenario's). So a URL you only need to silence for one listing stops being anignoreentry every other scenario also has to carry. - Organize by folder. Scenarios are discovered recursively, so you can group them in subfolders (
e2e/scenarios/contacts/list.json,e2e/scenarios/auth/login.json). Thescenario_idis the identity —run --all, the vitest suite anddepends_onall resolve by it, independent of the file path (duplicate ids are reported).
Scenario dependencies (depends_on)
Flows rarely start from zero — creating a bank account requires being logged in. Declare prerequisites and each scenario stays small, focused and individually cacheable:
{
  "scenario_id": "create-bank-account",
  "depends_on": ["login"],
  "task": "Already on the dashboard, open Settings > Bank accounts, create an account named 'Inter' and verify it appears in the list."
}- Dependencies run in the same browser session, in order, each with its own cache — a warm suite replays the whole chain with zero LLM calls.
- Without a
start_url, the dependent scenario continues from where the last dependency ended — and on first planning the LLM sees that real page (the post-login dashboard), instead of planning blind. - Chains work (
login→select-company→create-account), cycles are rejected, and a failing dependency fails the run with kinddependencybefore the scenario itself starts. - Each dependency keeps its own self-healing: if its cached plan breaks, it re-plans and re-caches — dependents benefit automatically.
- Guided self-heal. A re-plan tells the planner the exact selector that failed ("don't reuse it"), re-emphasizes your hints, and — with
--suggest— feeds the same expert diagnosis you'd read back into the re-plan, so it corrects instead of re-proposing a refuted selector. If a scenario keeps re-planning without stabilizing, Windup warns that the app likely lacks a stable selector (an a11y gap) or has a race, instead of churning silently. - Editing a scenario's
tasknow invalidates its cached plan (a rewritten test is a different test). - Flakiness becomes signal. Fast deterministic replay + strict postconditions + dependency re-execution is a sharp detector of hydration/redirect races in SPAs: a plan that stops replaying deterministically (
cache=miss llm_calls=1on every run, alternating PASS/FAIL) is telling you the app is non-deterministic, not the test. - First-run warm-up: a dependent scenario's cache key includes the state it inherits from its dependency, which only exists after the dependency runs once. So the first pass of a chain shows
cache=miss(it plans), and it settles tocache=hitfrom the second run on — expected, not a cache failure. - Session snapshots skip the chain replay (the big speed lever). Re-running a login flow through the UI for every scenario that depends on it is the dominant wall-clock cost of a cached suite. So Windup captures each dependency's exit state — Playwright
storageState(cookies + localStorage) plus its final URL — after it runs, and on a later cached replay it restores that state into a fresh context and skips re-running thedepends_onchain (deps≈0ms, reported asreused_session_from). The restored run is still verified: if the session is stale or the state wasn't fully captured (verification fails), Windup drops the snapshot and transparently falls back to re-running the full chain — no false pass, no wasted LLM call. Snapshots live in.windup/state/(gitignored — they hold auth cookies/tokens; never commit them) and refresh whenever the chain runs.
windup new handles dependencies both ways: --depends-on login declares them explicitly, and the author LLM also suggests them on its own — it sees every existing scenario (id + task) and, when the instruction presupposes a state one of them produces ("already logged in…"), emits depends_on automatically (mechanically filtered against real scenario ids — never invented). Either way the task is written from the dependency's final state, without repeating its steps.
Data preconditions (requires). depends_on captures a scenario dependency; requires documents a data one — the seed data a scenario assumes: "requires": ["1 active attraction", "a paid order"]. It's declarative (Windup shows it in the report so a failure caused by missing data is legible, and it maps out the create→use→archive cycle) — to actually seed the data, use setup/suite.setup.
Isomorphic plan reuse (like)
At scale, many scenarios are the same flow on a different route/entity — create a contact, create a deal, create a company all drive the same form. Instead of paying an LLM planning call for each, a scenario can reuse another's already-proven plan:
{
  "scenario_id": "deals-create",
  "start_url": "/deals/new",
  "task": "Type 'Big Deal' into the Name field and click Save; verify a new row appears.",
  "like": { "scenario": "contacts-create", "set": { "Alice": "Big Deal" } }
}like.scenarionames the scenario whose active cached plan is the template. Windup instantiates it for this scenario — thisstart_url, andlike.setswaps any differing fill values ("source literal" → "value to use here", applied tovaluefields only; selectors andvalue_refsecrets are untouched).- The reused plan is still executed and verified before it's trusted and cached — exactly the gate every plan passes. If the pages aren't actually isomorphic (a selector doesn't match, verification fails), Windup falls back to normal LLM planning. It never bypasses verification, so it can't produce a silent false green.
- When it verifies, the run cost zero LLM calls (
llm_calls=0, shown as reused) and the scenario now has its own cached plan; subsequent runs are ordinary$0replays. - The source must have been planned once first (its plan is the template). In a suite where the source runs later, the
likescenario simply plans with the LLM that round and reuses on the next — no error, just a missed optimization.
Reuse whole plans with like; reuse an action block across otherwise-different flows with a fragment (windup fragment extract). Both keep the deterministic, verified guarantee.
Client-side fixtures (seed)
Some state lives entirely in the browser — a shopping cart in localStorage, a selected POS device in sessionStorage. Building it through the UI every time is slow and couples the test to that flow. seed injects that state before the plan runs, deterministically and with no server call:
{
  "scenario_id": "cart-updates-quantity",
  "start_url": "/checkout/cart",
  "task": "Increase the first item's quantity to 3 and verify the total updates.",
  "seed": {
    "localStorage": { "cart": "[{\"id\":\"tkt-1\",\"qty\":2,\"price\":50}]" },
    "sessionStorage": { "pos_device": "reader-7" }
  }
}- Seeded per origin (default: the
start_urlorigin; override withseed.origin) via a Playwright init script that runs before the app's scripts, so the page loads already in that state. - Each key is set only if absent — the app's own mutations (a cart the test then edits) are never clobbered on later navigations.
- It's not part of the cached plan: it's applied on every run (including
$0replays), so seeded scenarios stay deterministic. - CI-safe by construction: you reach a client-side state directly instead of driving a flow that might hit the server. Great for cart/checkout and POS scenarios.
Authoring with windup new
The task and its final verification are the LLM's best guess from your instruction and the site map — an LLM can pick a plausible-but-wrong destination.
windup newnow steers the verification toward the instruction's actual goal (a visible element/text over a guessed route), and recommends confirming withwindup new "..." --validate(generate → run → self-refine until green) or a firstwindup run.
While iterating on a scenario, windup run <id> --watch re-runs it every time you save the file — a tight authoring loop.
You don't have to write detailed tasks by hand. Give windup new a rough instruction and the LLM acts as a test author — it rewrites it into a precise, verifiable scenario using the site map (real screens, menus and elements from windup scan and past runs) and the project manifest (accounts referenced by name, never literal credentials):
npx windup new "log in with the qa user, add the backpack to the cart and check out"
# → e2e/scenarios/purchase-backpack-qa.json — real screen names, concrete fake
#   form data, account referenced as "the qa account", explicit final verification
It generates the scenario_id, picks the start_url from known routes (falling back to / — it never invents paths), and adds selector hints from the map when they help. Add --validate to have it run the generated scenario and, if it fails, refine it from the failure and retry (up to 3 attempts) — you get back a scenario that already passed once, with a warm cache:
npx windup new "log in and create a cost center named Marketing" --validate
#   attempt 1: FAIL — element button:has-text('Save') not visible
#   attempt 2: PASSED
#   ✓ validated in 2 attempts — the plan is cached
``` **Credentials in the instruction never land in the scenario file**: they are auto-registered as a named account (values in `.env.local`, mapping in `windup.credentials.json`) and the task references the account — see Test credentials below. Flags: `--id <id>`, `--force` (overwrite), `--llm <provider[:model]>`. The output is a file for **you to review, edit and commit** — authoring is assisted, the test remains yours. One LLM call (~$0.001), recorded in the `windup costs` ledger under `authoring`.

### Author by demonstration (`windup record`)

The inverse of `windup new`: instead of *describing* the flow, **show it**.

```bash
npx windup record --url http://localhost:3000
Windup opens a headful browser at your app. Click through the flow; a small floating toolbar sits at the bottom:
- ◉ marcar verificação — then click the element the test should verify (its visibility, or its text). Mark nothing and Windup verifies the final page's URL.
- ■ finalizar — stop (Ctrl-C also saves).
On finish it writes the scenario file and caches the recorded plan, so npx windup run <id> replays it immediately at $0, no LLM. If the cache later invalidates (a real UI change), it self-heals by re-planning from the task, like any scenario.
- Selectors are unique-checked at capture. Each candidate along the anchor ladder (
#id → [data-testid] → [name] → [aria-label] → [placeholder] → clean unique text) is accepted only if it uniquely identifies the element on the page at that moment. Text is used only when it's short, unique, and carries no dynamic value (a count/price is skipped, so a cart link never records"1…R$ 35,00…"), and it's read from the element's own direct text, not its descendants'. When nothing stable is unique it falls back to a short structural path and flags the interaction unstable — Windup then prints those (⚠ N interaction(s) have no stable anchor …), the same spots a screen reader struggles with, so you know where to add adata-testidor hand-edit before the scenario enters a suite. - The task is human-readable even with
--no-llm. It's synthesized from the visible labels of what you clicked —Recorded flow: click "Ver ingressos" → fill "Quantidade" → click "Continuar", verifying "Continuar" (ends at /checkout)— not an opaque "14 interaction(s)", so a self-heal after an invalidation re-plans from a real description of the flow. (With an LLM key it still writes the one-sentence summary;--no-llmskips that call.) - A typed password never enters the plan: it's registered to
.env.local(gitignored) and the action stores avalue_ref.
It's a local dev tool — interactive and headful, so it needs a TTY (not CI). Under an agent/wrapper with no TTY, allocate a PTY: script -q /dev/null npx windup record. Flags: --url <start> (defaults to config.baseUrl), --id <id>, --force, --no-llm (a task is synthesized from the flow's labels instead of the one-call summary).
Test credentials
A scenario says "log in as the admin account" — never the password. Credentials never live in scenario files, plans, the cache or git; only references do. Where things are stored:
| What | Where | Committed? |
|---|---|---|
| The real values (users, passwords) | .env.local (created 600) | No — gitignored automatically; in CI, the same variable names are secrets |
| The account → variable-name mapping | windup.credentials.json | Yes — no values, only ENV: references |
| The live wiring | merged into the manifest (context.credentials) at startup | — |
A value is read only by the executor, when it fills a field — never by the planner, the plan, the cache or git. Variable names follow WINDUP_<ACCOUNT>_<FIELD> (e.g. WINDUP_ADMIN_PASSWORD).
npx windup secret set admin        # hidden prompts → .env.local (values) + windup.credentials.json (mapping)
npx windup secret list             # accounts + whether each value is [set] / [MISSING] — never prints values
npx windup secret remove admin     # drop the account: mapping + its .env.local lines (alias: rm)
Then reference the account by name in the task:
{ "scenario_id": "create-invoice",
  "task": "Log in as the admin account, open Invoices, create one for ACME and verify it appears in the list." }
Windup tells the planner the admin account maps to ENV:WINDUP_ADMIN_USER / ENV:WINDUP_ADMIN_PASSWORD, so the plan fills those with value_ref: "ENV:WINDUP_ADMIN_PASSWORD", resolved to the real value only at execution time. windup new does this automatically: credentials typed in the instruction are detected, registered and scrubbed — the scenario mentions the account, never the values. You can also declare the mapping directly under context.credentials in windup.config.ts. In CI, define the same variable names as pipeline secrets; windup secret list flags any that are missing before a run.
Dynamic values — OTP codes, magic-links (config.resolve)
Some values only exist at run time: a one-time code, a magic-link URL, a token. Declare a resolver in windup.config.ts — a source Windup fetches (with polling) at the moment it's needed — and the plan references it by name:
resolve: {
  otp_code:   { source: { kind: "cmd", command: "psql \"$DATABASE_URL\" -tAc \"select code from otp_codes order by created_at desc limit 1\"" }, extract: { regex: "(\\d{6})" }, poll: { timeout_ms: 30000 } },
  magic_link: { source: { kind: "http", url: "https://inbox.test/latest" }, extract: { json: "body.url" }, url: true },
}- The plan uses
{ "type": "fill", "value_ref": "otp_code" }for a field, or{ "type": "goto", "url_ref": "magic_link" }to navigate to a resolved URL. The planner is told the available names and emits these instead of a literal (it never sees or invents the value). - Sources (
kind):cmd(a shell command's stdout — read a DB, runcurl),http(fetch a URL — a test-inbox API like Mailosaur/MailSlurp), orfn(a project JS/TS module that exportsasync () => string).extractpulls the value out — aregex(capture group) or ajsondot-path.pollretries until it appears (default 30 s / 1 s), because the code/email arrives with a delay. - The source is author-declared, never LLM-generated — so
cmd/http/fnrun only what you wrote, never something the model invented. And the resolved value is ephemeral: it is used for the fill/goto and never written to the cache, the report, or logs. - Bind the field deterministically with
resolveFields(recommended for CI): declareresolveFields: { "[name=otp]": "otp_code" }(a selector substring → resolver name) and any fill on a matching field is filled from the resolver — overriding whatever the plan put there. This is the reliable path: the OTP flow no longer depends on the planner guessing to emitvalue_ref(if it fills a literal, or a differently-cased name, Windup still resolves the field). The planner is also told these fields are auto-bound. Names are matched leniently too —OTP_CODE/otp-codenormalize to a declaredotp_code. - This unblocks any flow gated by a runtime value: OTP/magic-link/passwordless login, and everything behind it.
Idempotency, setup & teardown
A replay re-runs the same cached plan with the same values. That is ideal for idempotent flows — edit a fixed record to a fixed value, toggle something and check the final state, read/list/filter. It does not fit a pure CREATE whose resource has a non-reusable unique key: the first run creates it, every replay violates the constraint.
Two ways to cover writes:
- Prefer idempotent scenarios — e.g. edit a known test record instead of creating a new one; the replay is
$0and leaves no residue. setup/teardownhooks — shell commands that run outside the cached plan (so they run on every replay), for fixtures or cleanup (hard-delete what the test created, reset via SQL/HTTP):
{
  "scenario_id": "create-contact",
  "task": "Open Contacts, create a contact named 'QA Tester' with CPF 111.111.111-11 and verify it appears in the list.",
  "setup":    "psql \"$DATABASE_URL\" -c \"delete from contacts where national_id = '11111111111'\"",
  "teardown": "psql \"$DATABASE_URL\" -c \"delete from contacts where national_id = '11111111111'\""
}
setup runs before the scenario (and before its dependencies); teardown runs after, always — pass or fail. They are your own trusted commands (like a test's beforeEach/afterEach), run in the project root with the process env, and never enter the plan or cache. A failing teardown is surfaced as a warning; a failing setup fails the run before planning.
Suite-level fixtures. For state shared by the whole suite — seed a fixture database once, start an external stub — use suite.setup / suite.teardown in windup.config.ts (see Configuration). They run once around a run --all (setup before the first scenario, teardown after the last — always), the suite analogue of beforeAll/afterAll. A failing suite.setup aborts the suite before any scenario runs; a failing suite.teardown is a warning.
Environments (dev / staging / CI)
The start URL origin comes from, in precedence order: --base-url flag → WINDUP_BASE_URL env → baseUrl in windup.config.ts → an absolute start_url in the scenario. An explicit override rebases even absolute scenario URLs (path and query are preserved).
The plan cache is environment-portable: cache identity uses the start URL path, not host/port. A plan generated against localhost:8080 replays on staging or CI with zero LLM calls.
npx windup run checkout --base-url https://staging.example.com
WINDUP_BASE_URL=http://localhost:8080 npx windup run --all
LLM providers
The planner is provider-agnostic. Google Gemini and OpenAI are supported; configure several at once and pick one per run:
// windup.config.ts
llm: {
  provider: "google",                       // default for runs without --llm
  model: "gemini-3.1-flash-lite",
  // apiKeyEnv: "GEMINI_API_KEY",           // already have the key under another name? point at it
  providers: {
    openai: { model: "gpt-5-mini" },        // default model when --llm openai is used
    // openai: { apiKeyEnv: "MY_OPENAI_KEY", baseUrl: "https://my-proxy/v1" },
  },
},
npx windup run checkout # config default (google)
npx windup run checkout --llm openai # provider default model (gpt-5-mini)
npx windup run checkout --llm openai:gpt-5-nano # explicit provider:model
WINDUP_LLM=openai:gpt-5-mini npx windup run --all # same thing via env (CI)--llmworks onrun,bench(compare providers on the same scenario) andscan(LLM-assist layer).- API keys:
GOOGLE_GENERATIVE_AI_API_KEY/OPENAI_API_KEYby default. To reuse a key your project already stores under another name, point at it withapiKeyEnv— either at thellmlevel (llm.apiKeyEnv: "GEMINI_API_KEY", applies to whichever provider has no override) or per provider (llm.providers.openai.apiKeyEnv, which wins). No need to duplicate the secret.windup doctorreports the exact variable it expects. - A wrong model name is caught as a config error, not a test failure: the provider's 404 becomes an actionable message naming known models, the run fails with
kind: config(never retried by--retries), andwindup doctorwarns up-front when the configured model isn't in the known-model table. baseUrl(OpenAI only) points at any OpenAI-compatible endpoint — Azure, a proxy, or a local model server.- Switching providers never invalidates the plan cache: plans are data, replays are LLM-free regardless of who planned them.
- Self-heal keeps your provider: when a cached plan fails and re-plans, Windup reuses the provider that originally made it (recorded in the plan) before the config default — so a scenario planned with
--llm claude-codere-plans with claude-code even if the later run didn't pass the flag. Explicit--llmalways wins. windup costsbreaks spend down by provider and by model, so alternating between LLMs keeps per-vendor spend visible.
Planning with your Claude subscription (--llm claude-code)
If you already pay for a Claude plan (Pro/Max), you can plan with it instead of buying API tokens — Windup drives the claude CLI you already have, no API key, no extra server.
Opt-in, never a default. Using a subscription to plan programmatically is a gray area not endorsed by Anthropic, and Windup does not operate it. For reliability-sensitive work (CI, shared suites) prefer
--llm googleor--llm openai. Cached replays never call any LLM, so a plan made this way still replays at $0 with nothing running.
Setup — one command
npx windup claude login    # installs the claude CLI if missing, then signs it into your plan
npx windup claude status   # anytime: "claude CLI: ready — [email protected] (max plan)"
windup claude login installs the Claude Code CLI (with your confirmation — never a silent global install, never in CI) and launches Anthropic's own browser sign-in; you click authorize on your account. The desktop app and the CLI sign in separately, so having the desktop app is not enough. If you'd rather do it by hand: npm install -g @anthropic-ai/claude-code, then claude → /login (pick "subscription", not an API key).
That's it — no wrapper, no Python, no local server. Windup spawns claude in non-interactive mode for each plan (from an isolated temp dir, so it never picks up a project's CLAUDE.md).
Several accounts — one per project (--profile)
The CLI's login is global: one token, in one config dir, so every project plans on whichever account signed in last. If you hold a personal plan plus one per client, that means client work quietly burns your own plan. Bind each project to its own account, once:
cd ~/work/acme
npx windup claude login --profile acme     # own config dir + binds this project + signs in
npx windup claude status                   # → confirms which account this project bills
--profile acme gives that account its own config dir (~/.claude-acme — an independent session), binds the project to it by exporting CLAUDE_CONFIG_DIR in .envrc, runs direnv allow, and then opens the sign-in. From then on, cd-ing into the project makes that account the one that plans — including the claude process Windup spawns, which inherits the environment. Repeat per project with a different name; your default ~/.claude stays untouched as the unnamed profile.
Your .envrc is never clobbered by accident: an existing file is appended to (other exports intact), re-running is a no-op, and a binding to a different profile stops and tells you to re-run with --force — which rebinds that one line and prints what it replaced. No direnv? The command prints the export to put in your shell.
npx windup claude status                 # which account is active here (email + plan) — no tokens spent
npx windup claude status --profile acme  # check a named profile without switching to it
npx windup claude login --profile acme --force  # point this project at another profile (rebinds .envrc)
npx windup claude login --force          # switch the ACTIVE account (signs out first, saying whose)
npx windup claude logout --profile acme  # sign that profile out (other profiles untouched)
npx windup claude logout --profile acme --remove   # …and delete its config dir: profile retired
Two things worth knowing: a project's .claude/settings.json cannot switch the account (the config dir is resolved before those settings load) — that's why the binding lives in .envrc; and cached replays call no LLM at all, so with .windup/cache/ committed a suite runs at $0 without touching any account.
npx windup run checkout --llm claude-code                 # default model: claude-sonnet-4-6
npx windup run checkout --llm claude-code:claude-opus-4-6
WINDUP_LLM=claude-code npx windup run --all               # via env
Optionally pin it in config so plain windup run uses it:
// windup.config.ts
llm: { provider: "claude-code", model: "claude-sonnet-4-6" },- Cost is reported as $0 in
windup costs— the tokens are real and stay in the ledger, but they're covered by your subscription, so Windup does not invent a per-token price for them. - If
claudeisn't installed or logged in, the run fails fast with an actionable message (install //login), not a stack trace. - Slower to plan than a hosted API (each plan spawns the CLI's agent — ~8–12s vs ~2–4s), but planning happens once and is cached; replays are $0 and instant regardless.
- Under the hood: there's no JSON mode, so Windup carries the plan schema in the prompt and un-fences the reply mechanically (Ajv still validates every plan);
temperature/seedhave no CLI equivalent and aren't sent (harmless — seed jitter exists for a Gemini-flash quirk).
Instead of the CLI, you can point Windup at claude-code-openai-wrapper — a third-party, community-maintained local proxy that exposes an OpenAI-compatible endpoint over your Claude Code session. Useful if you already run it, want an HTTP boundary, or reach Claude through Bedrock/Vertex behind it. Windup uses the wrapper (instead of spawning the CLI) whenever a URL is configured:
# start the wrapper (needs Python 3.11+ and Poetry), then:
WINDUP_CLAUDE_CODE_URL=http://localhost:8000/v1 npx windup run checkout --llm claude-code
// windup.config.ts — same effect, persisted
llm: { provider: "claude-code", providers: { "claude-code": { baseUrl: "http://localhost:8000/v1" } } },Its own client auth is off by default; set CLAUDE_CODE_API_KEY only if you enabled it. Same $0 cost, same un-fencing. A down wrapper fails fast with a message naming the URL.
CI/CD
npx windup run --all --reporter junit --report-file reports/windup.xml- Commit the plan cache so CI needs no LLM (the whole point). A replay is
$0because it uses the cached plan instead of the planner — so for CI (and any machine without your planner's CLI/key) the plan cache must be committed.windup initsets this up for you: it versions.windup/cache/(plans) and.windup/map/(site map) and gitignores only.windup/state/(auth cookies),.windup/runs/and.windup/reports/. Plan the suite once locally,git add .windup, and CI replays every scenario at $0 with no LLM and no Claude CLI. Plans are portable and secret-free (selectors +value_ref, never resolved values). When a new scenario (or a real UI change) causes acache=miss, that one needs the planner — regenerate locally and commit, or give CI a non-interactive planner (--llm google/--llm openaiwith an API key, orclaude-code-openai-wrapperviaWINDUP_CLAUDE_CODE_URL). (Upgrading from an older project? If your root.gitignorehas a blanket.windup/, narrow it to.windup/state/,.windup/runs/,.windup/reports/and commit.windup/cache/.) --allruns every scenario in the directory (one warm browser for the whole suite).- Suite summary & module grouping.
--all(or a multi-scenario run) prints a suite line — pass rate, cache-hit rate, re-plans, LLM calls, cost, and wall-clock time (real elapsed; the inflated sum-of-totals is shown alongside with the concurrency, e.g.wall 130s (sum 512s · concurrency 4)) — plus a per-module (folder) breakdown. The HTML report groups by module, leads with the wall-clock, and gives each scenario a duration breakdown bar that reconciles to its total; JUnit emits one<testsuite>per module; JSON carries the full summary (wall_ms,concurrency,by_module,flaky) and a per-caseduration_breakdown. - Flake score + root-cause hint.
--repeat <n>aggregates per scenario — one that passes some-but-not-all of its runs is listed flaky (passed X/N), with a hint at the likely cause drawn from its runs (start-page signature drift → hydration race; a network failure; always-same-action → an unstable selector; cache churn → non-deterministic replay) — so data-dependent flakiness surfaces, and points somewhere, before you commit a green. - Retry a flake (
--retries N). Re-run a scenario that failed a transient way (a network reset, a hydration-race verification miss, a wobblysetup/dependency) up to N extra times — the first pass wins. Aconfig.forbidblock is never retried (a deliberate guard, not a flake). The flake is surfaced, not swallowed: a scenario that only goes green on a retry is flaggedflaky—↻ N passed only on retryon the console, aFLAKY N×badge in the HTML report,flaky/attemptson the JSON record and therun:endstream event — so you fix the root cause instead of laundering a red build green. - Time budget (
--all --max-wall <seconds>). A CI guard-rail: once the suite's wall-clock crosses the cap, Windup stops starting new scenarios (in-flight ones finish — nothing is cancelled mid-run) and exits non-zero, so a runaway suite fails the build instead of hanging the runner. Works sequentially and under--concurrency. Prints⏱ --max-wall Ns exceeded — X/Y ran, Z not started. - Fail fast (
--all --bail). Stop starting new scenarios after the first failure — quick feedback in a PR check instead of waiting out the whole suite. Completes the guard-rail trio with--retries/--max-wall; works sequentially and under--concurrency. - Runtime health as a gate (
--fail-on-console/--fail-on-resource/--fail-on-5xx). A scenario can "pass" while the page threw a JS error, failed to load a resource, or got a silent 5xx. Windup observes all of it passively and records it always (RunMetrics.diagnostics, shown in the console/HTML/JSON reports — informational, like--a11y); these flags (orconfig.failOn) turn them into a failure (kinddiagnostics). The two console-noise classes are separated:--fail-on-consolegates JS errors (uncaught exceptions,console.error, CSP violations) while--fail-on-resourcegates sub-resource 4xx loads (a broken image/font/xhr) — so you can gate JS health without drowning in broken images. Each recorded console error carries its originating URL and ajs/resourcekind.ignore(below) silences known noise by message or URL, and deliberateconfig.networkstubs (e.g. a{ status: 500 }) are excluded — so testing an error state never trips the gate. - Device emulation (
--device "<preset>"/config.device). Run at a Playwright device preset —"iPhone 14","Pixel 7","iPad Pro 11"— applying viewport, user-agent, scale and mobile/touch. Cached plans are keyed per device, so mobile and desktop are separate trajectories (a mobile run can't clobber the desktop plan). Mobile emulation needs chromium. - Web vitals + performance budgets (
--web-vitals/config.budgets). Capture the final page's TTFB / FCP / LCP / DCL / load / CLS and report them (informational under--web-vitals). Setconfig.budgets({ lcp_ms: 2500, cls: 0.1, load_ms: 4000 }) and a breach fails the scenario (kindbudget). Perf timing varies run to run — set budgets with headroom. - Sharding.
--all --shard i/nruns shard i of n (round-robin split of the scenario list) — spread a big suite across parallel CI runners (--shard 1/4,--shard 2/4, …), each a separate job. - Tags. Tag scenarios (
"tags": ["smoke", "checkout"]) and run a subset:--all --tag smoke,checkoutruns any scenario carrying one of those tags. Run smoke on every push, the full suite nightly — composes with--shardand--changed. - Trace + screenshot on failure (
--trace). When a scenario fails, Windup saves a Playwright trace (.windup/reports/traces/<id>.zip— open it in the Playwright trace viewer: DOM snapshots, network and console per step) plus a full-page screenshot, and the HTML report links both from the failed row. See exactly what happened in CI instead of guessing from timings. (Captured only on failure — a passing run keeps nothing.) - GitHub Actions output (
--github, auto-on underGITHUB_ACTIONS). Emits a::error::annotation per failed scenario (shown inline on the PR) and writes a Markdown suite summary + per-scenario table to the job page ($GITHUB_STEP_SUMMARY) — results surface without opening an artifact. - Accessibility (
--a11y). After each scenario, run an axe-core audit on the final page and report violations — a free a11y check riding on infrastructure Windup already has (it reads the page anyway). Informational: it never fails the run. Opt-in tool:npm i -D axe-core. --concurrency <n>runs scenarios in parallel (one shared browser, isolated contexts) — measured ~2× faster on a mixed 11-scenario suite at--concurrency 4, more on suites with planning or long flows.- Browser prewarming (on by default;
--no-prewarmto disable). In a sequentialrun --all, while a scenario runs Windup pre-creates the fresh context + page the next scenario needs — so its ~200 ms launch happens off the critical path instead of as dead wait (a scenario'ssetupsegment drops to ~0). Isolation is unchanged: every scenario still gets its own clean context. Only sequential runs prewarm —--concurrency > 1already overlaps launches across workers. - Incremental runs (
--changed/--since <ref>). With--all, run only the scenarios a change affects:--changeddiffs the working tree againstHEAD,--since main(or any git ref) diffs against that ref. A scenario is selected when its own file changed, when it has no cached plan, or when its plan visits a route whose indexed source changed (the site map's file→route attribution). Selection is sound-but-coarse and never a silent false green: if the diff touches files the map can't attribute to a route (shared code, config), or there's no git/site map, Windup runs the whole suite and prints why. Re-scan (windup scan) keeps the attribution current; use plain--allfor a full pre-merge/nightly gate. - Exit code is non-zero when any scenario fails.
--reporter junitemits JUnit XML (GitHub Actions, GitLab and Jenkins consume it natively);--reporter jsonemits a machine-readable summary;--reporter htmlemits a self-contained human-friendly page (zero JS/deps — upload it as a CI artifact or open locally). Default output:.windup/reports/. The HTML report's per-scenario action list shows each step's type and target (a4 · fill · otp,a2 · click · Add to cart,a1 · goto · →/checkout) — a fill's value is never shown (secrets/OTP stay out).windup costs --jsonreports AI spend for pipeline tracking.windup coveragefinds coverage gaps: it cross-references the routeswindup scanindexed with your scenarios' start URLs (and cached plans) and lists the routes that have no scenario yet — the "what am I missing" report, generated from data Windup already has (no LLM).--jsonfor pipelines; a gate could fail the build when critical routes are uncovered.
Non-destructive testing — stay at the side-effect boundary
A suite that runs on every push must never charge a card, send an email/OTP, create an account, or mutate persistent state. The reliable rule: test up to the boundary of a side effect, and stop there. In practice almost every screen is coverable this way — the valuable checks fire before the network call:
- Client-side validation — invalid email/CPF/card, required fields, out-of-range values. The message ("CPF inválido", "Preencha os dados do cartão") appears before any request, so asserting it is safe.
- Navigation & read screens — lists, filters, tabs, detail views, empty states.
- Client-side state via
seed— cart quantities/removal/limits (localStorage), a POS device (sessionStorage) — reached without a server round-trip. - Error states from bogus tokens/slugs —
/order/BOGUS→ "not found", an invalid share link → "expired". Fully deterministic, no seed data needed. - Confirmation dialogs — open and cancel. Assert the "Delete?" dialog appears, then dismiss it (a native
confirmvia"dialog": "dismiss"; a modal by clicking Cancel). You verify the guard UI without performing the destructive action.
Keep out of CI: real payment, OTP/email/WhatsApp sends, account/company creation, saving config that persists (watch single-click toggles that save with no confirm step), a check-in that consumes a voucher, and — most dangerous of all — changing the test account's password. The discipline lives in the scenarios: every one stops before the irreversible action — and forbid in the config is the machine-enforced backstop (a run that ever targets a denied selector or URL aborts). setup/teardown (and suite.setup/teardown) exist for the writes you genuinely must exercise — do them against a disposable fixture, never production data.
Example GitHub Actions step:
- run: npm ci && npx playwright install chromium
- run: npx windup run --all --base-url http://localhost:8080 --reporter junit --report-file reports/windup.xml
  env:
    GOOGLE_GENERATIVE_AI_API_KEY: ${{ secrets.GEMINI_KEY }}
- uses: dorny/test-reporter@v1
  if: always()
  with: { name: windup, path: reports/windup.xml, reporter: java-junit }
Commands
| Command | Description |
|---|---|
| windup init | Create windup.config.ts, .windup/ (cache & map committed; state/runs/reports gitignored) and an example scenario |
| windup new "<instruction>" [--id x] [--force] [--depends-on ids] [--validate] | Generate a scenario from a rough instruction; --validate runs and refines it until it passes (≤3 attempts) |
| windup record [id] [--url <start>] [--force] [--no-llm] | Author by demonstration: drive a headful browser, mark a verification with the toolbar, finish — writes the scenario + caches the recorded plan ($0 replay). Needs a TTY |
| windup run [scenario] | Run one scenario (replay when cached, plan on miss) |
| windup run --all | Run every scenario — CI mode |
| windup run --all --changed / --since <ref> | Incremental CI: run only scenarios a change affects (working tree vs HEAD, or vs a git ref). Falls back to the full suite when impact can't be proven — never a silent false green |
| windup scan [--update] [--no-assist] | Statically index routes and interactive elements into the site map; --update re-indexes only files changed since the last scan (git diff); --no-assist skips the LLM layer (zero cost) |
| windup costs [--last n] [--days n] [--json] | AI usage report from the run ledger: totals, free replays, per-provider, per-model and per-scenario breakdown, scan and authoring spend |
| windup status | Site-map pages by source, staleness, cached scenarios, fragments |
| windup coverage [--json] | Cross-reference indexed routes (windup scan) with your scenarios — which routes have a scenario and which have none (finds coverage gaps automatically) |
| windup why <scenario> [--json] | Diagnose one scenario: cache state (replay-ready or will-plan), re-plan churn, depends_on chain, run history and the last failure — all from the ledger, no LLM |
| windup explain <scenario> [--json] | Print the cached plan as readable steps (go to / click / fill / verify). Review a plan without opening the JSON; a fill's secret value is never shown |
| windup diff <scenario> [--json] | Compare a scenario's two most recent runs — result flip, cache, and Δ time / Δ cost / Δ actions (a regression check) |
| windup badge [--json] [--out <path>] | Suite-status badge from each scenario's latest run — a self-contained SVG (N/M passing · $0) or a shields.io endpoint JSON |
| windup trends [scenario] [--last n] [--json] | Historical pass-rate, cost and duration per scenario from the run ledger (worst pass-rate first); a scenario id shows its runs over time. No LLM |
| windup suggest-scenarios [--limit n] [--force] [--dry-run] [--llm p] [--json] | Propose (write) scenarios for the indexed routes that have no scenario yet — one LLM call per route, reusing windup new; drafts for you to review. --dry-run lists them without calling the LLM |
| windup doctor | Preflight checks before a run — LLM key for the provider, browser installed, scenarios all parse, no orphaned fragment references, site map scanned. No browser/LLM/network; non-zero exit on a hard problem |
| windup fragment extract <scenario> <a1..aN> --id <id> --description <text> | Promote a slice of a cached plan to a reusable fragment |
| windup secret set <account> [--user u] [--password p] | Register test credentials: values → .env.local, mapping → windup.credentials.json (interactive hidden prompts without flags) |
| windup secret list | Accounts + whether each ENV is set (never prints values) |
| windup secret remove <account> | Remove an account: drops the mapping and its .env.local values (alias: rm) |
| windup claude login [--profile <name>] [--force] | Connect the claude CLI to your Claude subscription for --llm claude-code (installs it if missing, then signs in). --profile gives that account its own config dir and binds this project to it; --force switches the active account |
| windup claude status [--profile <name>] | Which account is active here — email + plan, plus the profiles on this machine (non-zero exit when not ready) |
| windup claude logout [--profile <name>] [--remove] | Sign out of the active account or a named profile; --remove also deletes that profile's config dir (never the default ~/.claude) |
| windup sig <url> [--repeat n] | Structural page signature (diagnostics) |
| windup bench <scenario> | Full validation protocol (generation, replay determinism, failure recovery) |
| windup cache clear | Drop the trajectory cache (next runs re-plan) |
run flags: --all · --no-cache · --no-map · --repeat <n> · --concurrency <n> (parallel) · --retries <n> (re-run a flake; forbidden never retried) · --max-wall <seconds> (suite time budget) · --bail (stop on first failure) · --fail-on-console · --fail-on-resource · --fail-on-5xx (runtime health gates) · --device <preset> (emulate a device) · --web-vitals (capture TTFB/FCP/LCP/CLS) · --no-prewarm (disable next-scenario browser prewarming) · --browser chromium|firefox|webkit · --verbose (planning/execution heartbeat) · --stream (NDJSON events) · --headed (show the browser) · --slowmo <ms> (demo pace) · --base-url <url> · --llm <provider[:model]> · --summary (AI debrief) · --suggest (fix hint on failure) · --reporter junit|json|html · --report-file <path> · --shard i/n · --tag <names> · --trace · --github · --a11y · --watch
AI debrief (--summary)
For humans reading results (not CI), --summary adds one LLM call after each run that writes a short debrief: what the test did, the outcome, concrete values observed on the final page (prices, messages, product names — quoted literally from the page), and any difficulties (slow steps, re-planning, failures). It prints in the terminal, lands in the run ledger, and shows as a highlighted block in the HTML/JSON reports.
npx windup run checkout --summary --reporter html
# summary: "The test logged in and completed checkout for 3 items; the
#  confirmation page showed 'Thank you for your order'. Prices observed: ..."
Off by default on purpose — cached replays stay at zero LLM calls and $0. The debrief cost (~$0.0005 on the default model) is tracked separately in the run metrics and included in estimated_cost_usd.
Verbose progress (--verbose)
Planning with a slow provider (e.g. --llm claude-code, ~1–3 min/plan) prints nothing until the result, so a run can look frozen. --verbose emits milestones to stderr as planning and execution advance — each line prefixed with the scenario id and elapsed time:
contacts-columns  planning… (llm: claude-code/claude-sonnet-4-6)  (+0.0s)
contacts-columns  calling claude-code (attempt 1.1)…  (+0.2s)
contacts-columns  plan received: 4 actions, validating…  (+48.9s)
contacts-columns  a1 goto /workspace/contacts ✓  (+49.1s)
contacts-columns  a2 click … ✗ verification failed  (+51.0s)
contacts-columns  verification failed at a2 → self-heal re-planning  (+51.0s)
It never changes results and is off by default. Best read at --concurrency 1 (parallel runs interleave, though each line is scenario-prefixed).
Fix suggestions on failure (--suggest)
When a run fails, --suggest adds one LLM call that acts as a senior QA engineer debugging it: it compares the executed plan and the failing step against the real final page and the site map's known selectors, then proposes a concrete fix to the scenario — the wrong selector and the real one, a targeted screen that doesn't hold what the task expects, a missing step, or a timeout too short for a slow page.
npx windup run create-invoice --suggest
# FAIL  create-invoice  ... element button:has-text('Save') not visible
#   suggested fix: The 'Save' button does not exist; the dialog's real button
#   is labeled 'Create'. Change the hint to button:has-text('Create').
It turns a red run into a specific edit — instead of reverse-engineering the app by hand. Only fires on failure (green runs cost nothing), never edits the scenario itself, and shows as a highlighted block in the HTML/JSON reports. Pairs naturally with --summary.
Browsers
Windup runs on Chromium by default (provisioned automatically on install). To run the same scenarios on Firefox or WebKit, install that browser once and select it:
npx playwright install firefox        # one-time, per browser
npx windup run checkout --browser firefox
npx windup run --all --browser webkit
Set it per project in windup.config.ts (browser: "firefox") or per run with --browser / WINDUP_BROWSER. A plan generated on one browser replays on the others — selectors are cross-browser — so you author once and run everywhere.
Configuration (windup.config.ts)
import { defineConfig } from "windupjs";

export default defineConfig({
  baseUrl: "http://localhost:3000",
  llm: {
    provider: "google",
    model: "gemini-3.1-flash-lite",
    // Several providers at once — pick per run with --llm (see "LLM providers"):
    providers: { openai: { model: "gpt-5-mini" } },
  },
  scenarios: "e2e/scenarios",
  framework: "react-router",          // detected by init; used by scan
  // browser: "chromium",             // or "firefox" / "webkit" (need: npx playwright install <name>)
  scan: {
    llmAssist: { enabled: true, maxCalls: 20 },   // hard cost cap per scan
  },
  // Project manifest: team-provided knowledge injected into the planner prompt.
  context: {
    conventions: ["every interactive element has a data-testid"],
    credentials: {
      qa: { user: "ENV:QA_USER", password: "ENV:QA_PASSWORD" },
    },
    vocabulary: { "order": "the Order entity, screen /orders" },
  },
  // Reusable readiness signals per route glob (anti-flake) — see below.
  readySignals: {
    "**/workspace/**": "#app-ready",              // wait for this before acting on any /workspace/* page
    "**/reports/**": ["#grid", "[data-loaded]"],  // one or more selectors
  },
  // Suite-level fixtures: run once around `run --all` (beforeAll / afterAll).
  suite: {
    setup:    "npm run db:seed",
    teardown: "npm run db:reset",
  },
  // Safety denylist: abort if a plan ever touches these (CI guardrail).
  forbid: {
    selectors: ["#change-password", "[data-danger]"],  // substring match on a plan's selector
    urls: ["**/account/password", "**/admin/**"],       // path globs the run must never reach
  },
  // Request stubbing: deterministic responses for matched requests (test a 500, an empty list, a slow/failing endpoint).
  network: [
    { url: "**/api/orders", json: [] },                 // force an empty list
    { url: "**/api/report", status: 500 },              // simulate a server error
    { url: "**/analytics", abort: true },               // drop the request (network error)
  ],
  // Frozen clock: pin the page's time and/or timezone for date-dependent scenarios.
  clock: { now: "2026-01-15T09:00:00Z", timezone: "America/Sao_Paulo" },
  // Runtime health gates: fail a scenario on a JS error / resource 4xx / 5xx seen during the run.
  failOn: { consoleErrors: true, resourceErrors: true, http5xx: true, ignore: ["/analytics", "gravatar.com"] },
  // Device emulation: a Playwright preset applied to every run (viewport/UA/mobile). Cache is keyed per device.
  device: "iPhone 14",
  // Performance budgets: fail when the final page's metric exceeds the threshold (ms, or unitless for cls).
  budgets: { lcp_ms: 2500, cls: 0.1, load_ms: 4000 },
});context.credentialsmaps account names to ENV references. When a task mentions the account, the plan usesvalue_ref— manifest credentials take precedence even if the page displays values, and the planner is forbidden from inventing ENV names.readySignalsmaps a route glob to the CSS selector(s) that must be visible before the executor runs the first action on a matching page. It's applied deterministically at run time (no LLM, $0, not part of the cached plan) — so a hydration/loading wait is defined once per route instead of repeated as a hint in every scenario. It closes the load-time race where an element is present but its handlers aren't attached yet (which Playwright's per-element wait can't see). Best-effort: a signal that never appears within the timeout logs a warning and co